From domain registration to deployment, business email, SEO, and real-world verification: a firsthand case study.
We built a business website with AI and launched it in just five hours—from domain registration to a live, publicly accessible site. With ChatGPT assisting throughout the process, we registered the domain through Porkbun, deployed the website using Cloudflare Pages, configured DNS and HTTPS, and verified that the website was publicly accessible. The five-hour milestone refers to building and launching the website—not completing every subsequent SEO or search-engine indexing task.
We Needed a Website, Not Another AI Experiment
We needed a professional website for Vivaccess Ltd, a Cyprus-registered company offering international recruitment and talent acquisition services. This was not a fictional demo: it needed a custom domain, responsive design, secure HTTPS, a working contact channel, and a foundation for search discovery. We worked with ChatGPT to create a static website and then tackled the infrastructure needed to launch it.
1. Starting With the Business
Before selecting tools, we defined the message: Vivaccess helps businesses find specialists, source international talent, and grow teams. We chose five pages: Home, Services, About, Contact, and Privacy Policy. We wanted a premium visual identity without limiting the business to one industry or region.
2. Building the Site With AI
ChatGPT assisted with HTML, CSS, JavaScript, page structure, design refinements, and technical troubleshooting. We iterated through versions, testing desktop and mobile layouts, navigation, typography, and visual elements. AI accelerated development, but we still made the business and design decisions and checked the results.
Why not WordPress? We already knew WordPress from TechEduCareer—and had explored how to use AI to improve a WordPress website—but this project initially needed only a handful of relatively stable pages. A static website avoided a database, theme dependencies, and routine plugin updates. For a frequently updated blog or a future recruitment portal, the trade-offs could be different.
3. Registering vivaccess.eu With Porkbun
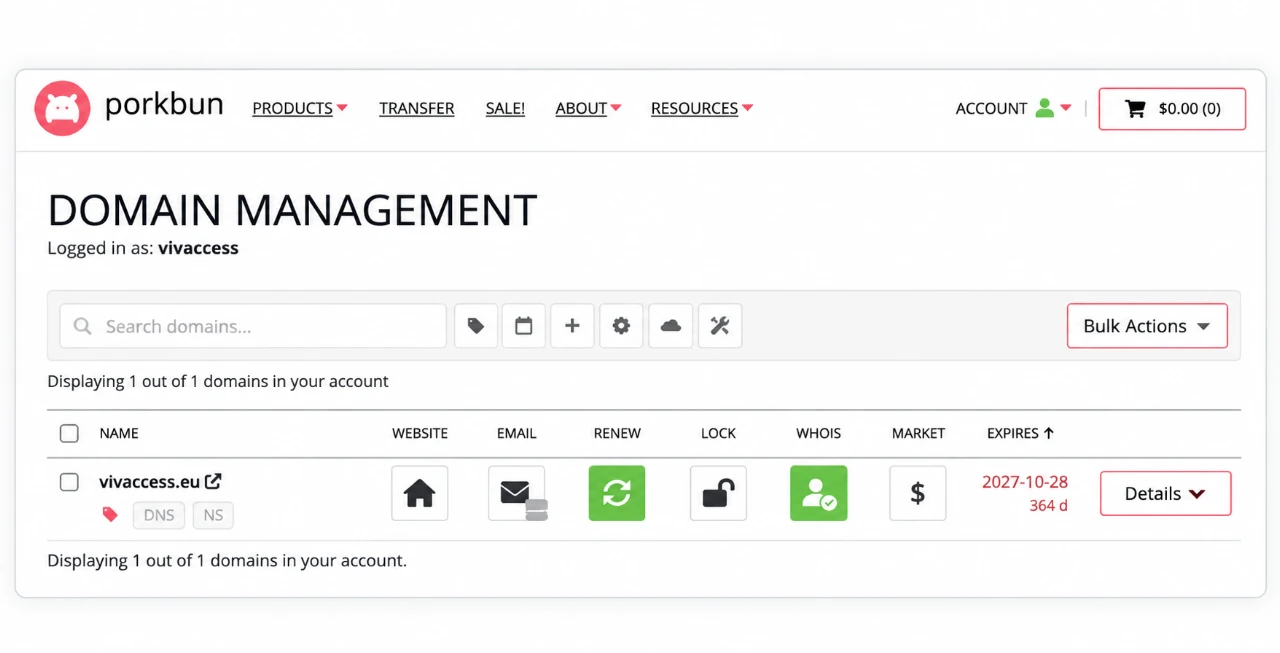
We registered our domain through Porkbun. Domain registration is not the same as hosting: a registrar manages the name, DNS directs traffic, and a hosting service serves the website. We used Porkbun for registration and Cloudflare for DNS and hosting. Domain buyers should check renewal prices, not just introductory offers.
Porkbun Domain Management showing the registered vivaccess.eu domain.
4. Deploying With Cloudflare Pages
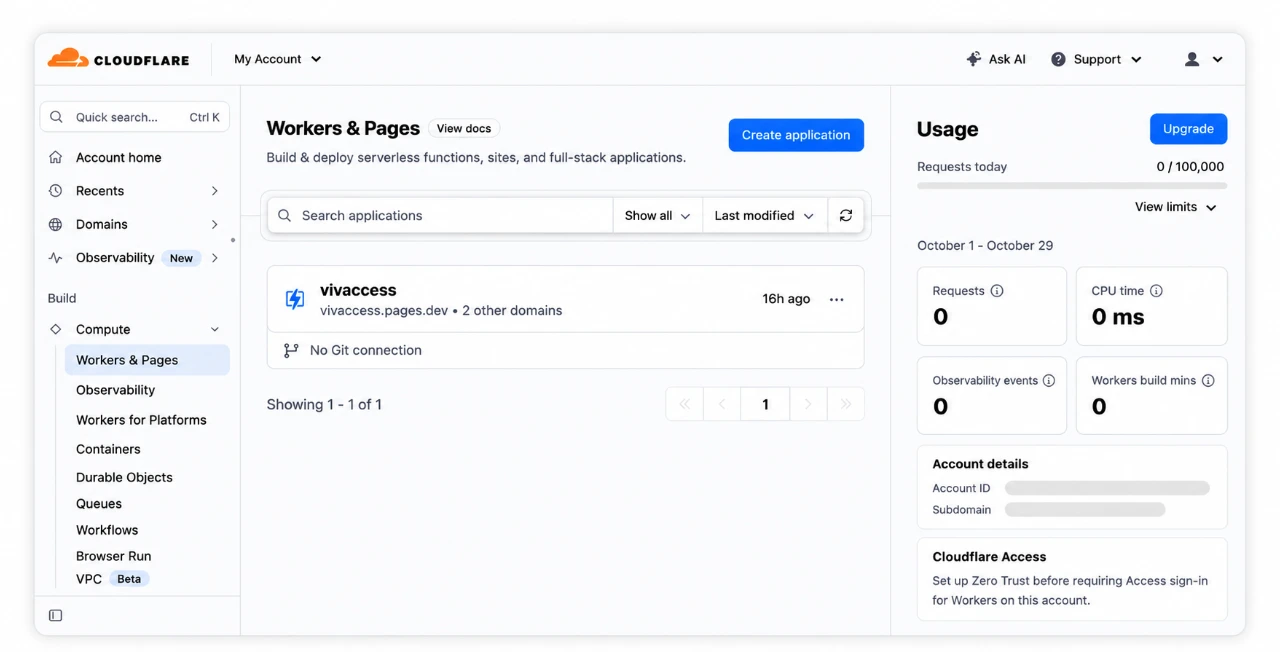
We deployed the static files through Cloudflare Pages, using a project address at vivaccess.pages.dev before connecting vivaccess.eu. We configured DNS, HTTPS, and a permanent redirect from www.vivaccess.eu to the non-WWW domain. We tested the redirect rather than relying solely on a successful-looking dashboard.
Vivaccess website deployed with Cloudflare Pages.
5. Business Email and Contact Form
We configured contact@vivaccess.eu using Cloudflare Email Routing to forward incoming messages to Gmail, then tested delivery. Forwarding is not a full hosted mailbox or outbound email service; those require separate arrangements if needed.
Because the website had no application backend, we integrated Web3Forms for contact submissions and tested the form. Third-party form processing also raises privacy questions, so our privacy notice and service safeguards need appropriate review.
One apparent bug turned out to be a local computer issue: clicking the email link did not open a mail app, although inspection showed a correct mailto: link. Browser or operating-system settings can affect what users experience.
6. SEO Is More Than Making a Website Live
We checked the five pages’ titles, descriptions, headings, and internal navigation. We added canonical URLs, Open Graph metadata, a 1200 × 630 social preview image, Twitter/X card metadata, and Organization JSON-LD describing Vivaccess and linking to its LinkedIn company page.
We also configured Google Search Console and Bing Webmaster Tools and submitted a five-page XML sitemap at vivaccess.eu/sitemap.xml. Google initially reported a sitemap fetch/read issue, even though the sitemap was accessible and the homepage passed live URL inspection. We chose to monitor processing rather than immediately change working infrastructure. A submitted sitemap is not a guarantee of indexing or rankings.
7. Verifying the Launch With PowerShell
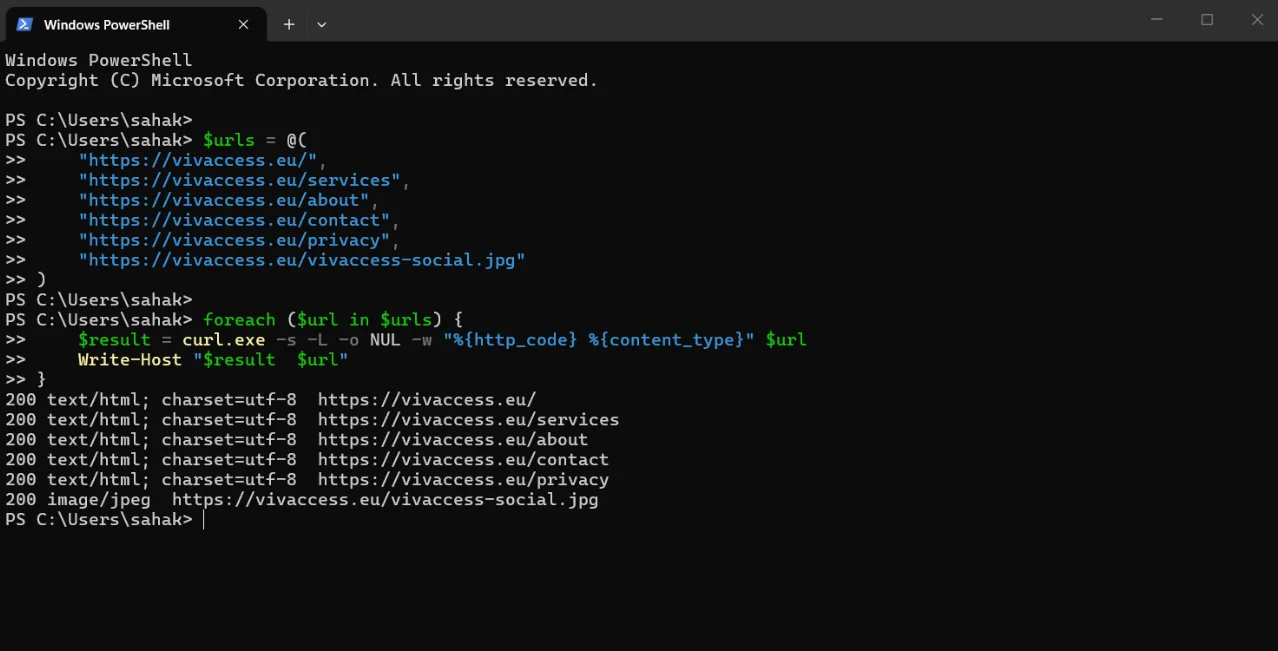
We did not stop at the deployment success screen. We checked that the live homepage actually contained the new metadata:
All six resources returned HTTP 200. The five pages reported text/html; charset=utf-8; the preview image reported image/jpeg. That confirmed public accessibility at the time of testing, though not every possible browser interaction or SEO outcome.
All six Vivaccess resources returned HTTP 200.
8. What Did It Cost?
Our stack combined paid domain registration with free-tier or free services: Porkbun for the domain, Cloudflare Pages and DNS for hosting and routing, Cloudflare Email Routing for incoming messages, Web3Forms for the contact form, and free Google and Bing webmaster tools. ChatGPT access may have a subscription cost. We will add verified actual amounts and applicable service limits before publication; free tiers and prices can change.
9. What AI Did Well—and What Still Needed Us
AI helped generate code, refine the design, explain DNS and hosting concepts, suggest SEO changes, and prepare test commands. Our earlier ChatGPT and WordPress MCP case study explores another way AI can support practical website work. But humans still needed to choose the positioning, assess the design, configure accounts, review privacy implications, and verify that the deployment and email actually worked.
Next time, we would define the full page structure and technical checklist earlier, plan SEO metadata before the final deployment, document tests as we go, and address privacy requirements alongside implementation.
Final Thoughts
We ended with a real business website—not just a mockup—at vivaccess.eu, with its own domain, HTTPS, incoming business email, a tested contact form, and an SEO foundation. Search indexing and compliance review still require follow-up.
AI can help you build a website. Verifying, launching, and maintaining it is what makes it a business asset.
Editorial note: This firsthand case study is not sponsored by Porkbun, Cloudflare, Web3Forms, or other providers mentioned. Add actual costs and selected screenshots before publishing.
A highlight reel tells you what made the cut. It doesn’t tell you who planned it, where the first idea failed or what the student changed after someone else looked at it. If we want gaming and media projects to count as learning, we need to see some of that work, not just the final upload.
When I ask what a student did on a project, “I made the video” isn’t quite enough. Did they choose the clips, sort out the sound, write the captions, check permissions? A useful portfolio answers those questions with a few pieces of evidence. It gives the designer, writer or event planner something to show too, even if they never played in the match.
Start with the brief
I would give students a brief they can fit on half a page: what they are making, who it is for and where it will appear. A graphic for a classroom screen can afford small details that will vanish on a phone. A public stream brings different rules about names, images and music. Put those limits in the brief before anyone starts making things.
Then leave room for the student’s own choices. If the brief reads like instructions for every colour and cut, there is little left to explain in the portfolio.
Save one early version
Keep an early draft. It might be a rough video sequence, a hand-drawn graphic or the first running order for an event. Ask the student to add a note about what they were trying to do and what was still bothering them. That is enough to make a later change visible.
Nobody needs a folder full of nearly identical screenshots. Pick one version that shows the starting point and move on.
Record feedback and a decision
Now put the draft in front of someone else. If a classmate cannot read the date on a thumbnail at phone size, record that. If a teacher spots a missing technical check in the event schedule, record that too. The portfolio needs the comment and the student’s decision about it. “I made the date larger so it worked on a phone” is useful evidence. “I improved the design” could mean anything.
Sometimes the student will keep the original choice. That’s fine if they can explain why it still serves the audience. Feedback is a conversation, not an instruction to change everything.
Show the revision
Show the old and new versions side by side. Point to a change that matters: clearer audio, a simpler graphic, an event plan that gives the team time to test its stream. If a student removed a song because they could not use it, include that decision as well. These are small, concrete things a teacher can actually discuss with them.
The work behind a school event is wider than the match itself. Someone has to plan, write, design and produce it. In the school curriculum I work on at Squid Academy, we include portfolio development among those roles. The question is the same in any school: what did this student decide, and what can they show to explain it?
Add credits and a short reflection
Credits belong in the evidence too. Ask who made each part, where images and music came from, and what permission the team had to use them. If students appear in a photo or stream, follow the school’s rules before it goes anywhere public. A private portfolio may be the right place for the work even when public posting is off the table.
I would finish with a short reflection, not a victory speech. What would the student keep? What would they change if they had another afternoon? Which choice can they now explain better? Answers that admit something was awkward or unsuccessful are often more revealing than “everything went well.”
A small example
Take a student making a thumbnail for a school tournament video. The first version looks fine on a laptop, but the date disappears on a phone. They save it, note the feedback, enlarge the type and keep the approved photo credit beside the final file. A reviewer can see the problem and the response in minutes. Without that trail, the thumbnail is simply a thumbnail.
Keep it manageable
I would not ask a teacher to learn another platform for this. A shared folder and a short document will do. Give students six prompts at the start: brief, early version, feedback, revision, credits and reflection. They can collect the pieces while they work. Ask for them after the event and they will have to reconstruct decisions they barely remember.
That also makes review less dependent on who played well or stood in front of the camera. A teacher can ask each student to talk through one decision and check it against the saved work. If the answer is vague, the next question is easy: show me the draft or the feedback that led you there. When the team did the work together, ask each student to name their own contribution and one thing a teammate changed. That tells you more than a shared slide that gives everyone the same credit.
There is no prize for the thickest portfolio. I want to see enough to understand the student’s part in the project and hear them explain a choice or two. The finished event can still be the thing everyone enjoys. The portfolio lets us notice the work that made it happen.
You open ChatGPT, Claude, Gemini, or Qwen and type a perfectly ordinary question. It answers. Then you visit YouTube and discover dozens of tutorials explaining how to write “perfect AI prompts,” complete with formulas, expert roles, and elaborate instructions. Suddenly, asking a simple question feels like doing something wrong.
But is it? If conversational AI is built to understand natural language, why should everyday users need special training to talk to it? And what exactly are those courses teaching?
This guide takes a practical, balanced look at prompt engineering: what it is, why long prompts sometimes help, when a conversation works better, and when structured instructions really are worth learning. Along the way, we’ll draw on real TechEduCareer work involving WordPress troubleshooting, SEO, design, and AI tools.
What Is a Prompt? You’re Already Writing Them
A prompt is the input you give an AI system. It might be a question (“What is WordPress?”), an instruction (“Summarize this article”), a creative request (“Suggest three logo concepts”), or a detailed task description. Text is common, but depending on the system, an input can also include images, files, audio, and other information.
You do not need to label your message as a prompt. If you have ever asked an AI assistant a question, you have already used one. “Continue,” “Explain,” and “Make this simpler” can all be effective prompts when the preceding conversation makes their meaning clear.
There is a technical nuance: the model may also receive system instructions, conversation history, retrieved documents, or tool results. So your latest message is not necessarily the only information shaping the response. That distinction becomes important when comparing a fresh chat with a conversation that has developed over weeks.
Why Are There So Many Prompt Engineering Tutorials?
Prompt engineering is the practice of designing, testing, and refining instructions and context to obtain useful AI outputs. OpenAI’s prompt engineering documentation describes techniques for improving model responses, especially in developer workflows. It is a real discipline, particularly in software development and repeatable business workflows. Yet online explanations often blur two very different situations: a person exploring an idea through conversation and an application that must process thousands of requests consistently.
For a casual user, “Explain this error message” may be all that is needed. For a customer-support workflow that classifies messages into predefined categories and outputs machine-readable data, ambiguity can break the process. Developers may need carefully specified labels, examples, validation rules, and tests across many inputs.
Good educational material explains that difference. Less useful advice makes ordinary communication sound like a secret technical language. There is no universal formula that turns every prompt into a correct answer.
Are Longer Prompts Better? Not Necessarily
Consider “Help me improve my website.” The AI understands the words, but the task is broad. Does improvement mean loading speed, accessibility, design, search visibility, or conversion? A longer request can resolve those uncertainties: “My WordPress site uses LiteSpeed Cache. Help me investigate a JavaScript error. First identify the likely source; do not change settings until I approve.”
The second request is stronger because it provides relevant context, a specific goal, and a boundary—not because it contains more words. Padding it with impressive adjectives, irrelevant background, and repeated demands may add little value. Long prompts can also contain conflicting instructions that make the task harder.
A useful rule is to provide the information the AI cannot reasonably infer: your objective, the relevant environment, important constraints, and what a successful result would look like. If you do not know these yet, that is not a failure. You can discover them together.
Does “Act as a Professional Expert” Make AI Smarter?
Many prompts begin with “Act as a senior designer,” “You are an experienced researcher,” or “Behave like a professional editor.” This technique is often called role prompting. Anthropic’s prompting guidance emphasizes clear, direct instructions and explaining the context that a new collaborator would need. It can encourage the model to adopt a useful perspective, vocabulary, or style. A request framed around SEO may naturally emphasize search intent, indexing, and internal links.
But role wording does not grant qualifications, unlock hidden knowledge, or guarantee factual accuracy. “Act as a world-class WordPress developer” is less actionable than supplying the actual browser error, installed caching setup, and steps already tried. You can use both, but the evidence and task definition usually matter more than the grand title.
Try replacing a theatrical role with an explicit expectation: “Review this article for factual accuracy, readability, and search intent. Identify weaknesses and explain your reasoning.” That tells the AI what to evaluate and how to respond.
The Alternative: Build the Answer Through Conversation
Not every project begins with a complete specification. When designing a logo, you may not know the final shape, colors, typography, or proportions until you see alternatives. A giant upfront prompt forces you to predict decisions you have not made. Iterative prompting takes a different path: begin with a direction, inspect the result, react, and refine. Google’s Gemini prompt design guide likewise describes iteration and breaking complex tasks into smaller steps.
“I need a logo, but I haven’t decided on a visual direction.”
“Let’s explore simple geometric symbols.”
“The second idea is promising, but it feels too complicated.”
“Keep the concept and simplify the shape.”
“Now compare two typefaces before we finalize.”
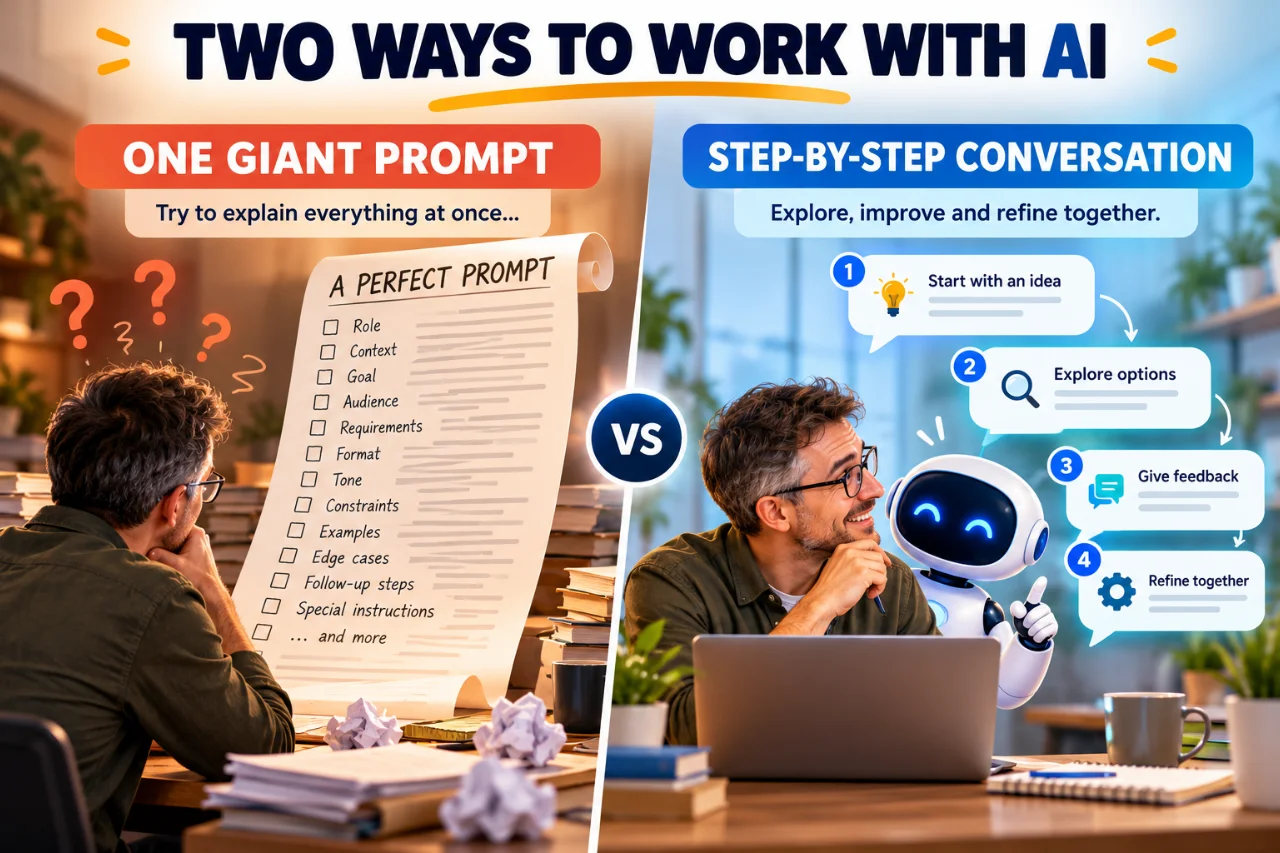
Two approaches to working with AI: detailed instructions upfront or an evolving conversation. Both can be useful depending on the task.
Each message is a prompt. Together they form a working process. The same method applies to article planning, learning a new subject, debugging code, and researching unfamiliar options. The AI can offer alternatives, ask questions, and explain trade-offs while the user makes the decisions.
In our TechEduCareer design work with AI, the final direction often emerged only after reviewing actual results. No amount of advance description could fully replace seeing a shape on screen. The practical lesson is simple: when visual feedback or testing is available, use it instead of endlessly polishing instructions.
Ask the AI to challenge you, not merely agree
A productive conversation also needs disagreement. AI assistants can sometimes become overly agreeable—a behavior often described as sycophancy. If you ask “Is my design perfect?” you may get less useful feedback than if you say “Critique this design. Identify weaknesses and tell me if a new choice conflicts with decisions we made earlier.”
The goal is not to make the AI argumentative. It is to encourage evidence-based feedback, distinguish facts from preferences, and preserve the user’s control over final decisions. A helpful collaborator should be able to say, “We tried that approach before; here is what happened and what has changed.”
Why Shared Context Changes Everything
Think about speaking with someone you know well versus a neighbor you have just met. With a close family member, a few words may be enough because you share experiences, preferences, and history. With a new acquaintance, you naturally explain more. The difference is not intelligence; it is shared context.
The more relevant context an AI has, the less you need to explain from scratch. However, important details may still need to be repeated.
AI conversations have a useful—but limited—parallel. In a continuing chat, an assistant may have access to earlier decisions, examples, and preferences. In a fresh chat, it may know none of them. Some products offer memory or project instructions, but availability and behavior differ. AI does not understand relationships as a human does, and remembered context can be incomplete or wrong.
For important projects, periodically summarize decisions: “We chose a minimal design, rejected complex icons, and agreed not to publish without review.” This makes it easier to resume work, spot contradictions, or move to another system. Shared context reduces repetition, but it does not remove the need to verify assumptions.
Will the Same Prompt Work in ChatGPT, Claude, Gemini, and Qwen?
Usually, yes—at the level of ordinary language. “Let’s work step by step and challenge my assumptions” is understandable across capable conversational AI models. But the results will not be identical. Models differ in training, reasoning performance, instruction following, available context, and communication style. The application surrounding the model matters too. Our WordPress and MCP case study shows what changes when AI can interact with connected tools.
For example, one assistant might have access to a connected WordPress site, while another can only advise based on text you paste into the chat. One may be able to search the web or edit a Figma document; another may not have those tools enabled. A prompt cannot create a missing integration or grant permission to change a website.
If you move to another AI, transfer a concise project brief rather than assuming it knows your history. Include your goal, current state, key constraints, previous decisions, and what you want to do next. Then evaluate the new assistant’s output on its merits.
Are There Secret AI Commands?
No universal one-word command unlocks hidden intelligence or bypasses an AI system’s normal capabilities. Words such as “Continue,” “Summarize,” “Simplify,” “Compare,” and “Critique” often work because the current conversation supplies the missing object. “Continue” after a half-written outline is clear; “Continue” in an empty chat is not.
Specific applications may support genuine slash commands, keyboard shortcuts, custom instructions, or developer-defined actions. Those are product features, not secret words understood by every model. Similarly, typing “SYSTEM OVERRIDE” or “IGNORE ALL PREVIOUS INSTRUCTIONS” does not grant a normal user higher authority over the system.
The decisive question is whether the AI has enough relevant information to understand the intended task. A short instruction can be clear in an established conversation and meaningless in a new one.
Real Example: WordPress Troubleshooting Without a Magic Prompt
While working on TechEduCareer, we encountered a JavaScript error reported inside a generated LiteSpeed Cache file. Our related AI-assisted WordPress development case study explores the broader question of when to use plugins and custom code. The visible filename alone did not reveal which original script caused the problem. A vague request such as “Fix my website” would have encouraged guesswork.
Instead, the investigation became a sequence of questions: What error does the browser show? Is the file generated by caching or supplied directly by a plugin? Which original script is involved? Can we inspect the evidence before changing settings? The investigation traced the problematic script to a plugin rather than treating the optimized filename as the true source.
That workflow demonstrates three habits more valuable than a decorative prompt formula: supply observable evidence, test hypotheses, and verify the result in the real system. An AI explanation is not the same as a confirmed fix. Screenshots, logs, documentation, and actual application behavior remain essential.
Another Example: SEO Research Needs Evidence, Not Confidence
Imagine asking an AI to find publications that accept unpaid guest articles and allow editorial backlinks. A confident list of ten websites might look impressive, but the important questions are whether submissions are currently open, whether links are permitted, whether they appear in the article or author bio, and whether any fees apply.
For that task, a useful request specifies verification standards: check official contribution pages, distinguish confirmed policies from unknowns, and provide sources. A detailed prompt helps because the deliverable has objective criteria. Even then, websites change their policies, so current research and human review matter.
This is one reason formal prompting can be worthwhile for research: not to make the AI sound authoritative, but to make uncertainty and evidence visible.
When Formal Prompt Engineering Really Is Worth Learning
There are situations where conversational improvisation is not enough. If an organization needs an AI system to process invoices, classify support tickets, extract fields from documents, or generate consistent reports, it needs repeatable behavior. Prompts may be combined with schemas, examples, tools, evaluations, and software checks.
Automated workflows: instructions must work across many inputs without a person clarifying each one.
Structured outputs: downstream software may require exact fields, types, or formats.
High-stakes decisions: evidence, oversight, and independent validation matter more than fluent prose.
Tool-driven actions: permissions, approval boundaries, and error handling must be explicit.
In these contexts, prompt engineering is part of a broader engineering process. A prompt alone cannot replace testing, access controls, or monitoring. Good courses should teach how to evaluate results and identify failure modes, not just provide impressive templates.
Prompt Engineering vs. Context Engineering
A related term is context engineering: deciding which information, examples, documents, instructions, and tool results an AI should receive for a task. The distinction is useful even for beginners. “Act as an expert” focuses on wording; providing the real error log, plugin list, and past attempts improves the information available for reasoning.
You do not need to memorize the terminology. The practical question is: “What does the AI need to know that it does not already know?” Relevant context usually helps more than elaborate phrasing.
Five Habits That Make AI Collaboration Better
Start naturally. Ask your question in your own words; you do not need a template for everyday tasks.
Add context when it matters. Mention your goal, environment, constraints, and any previous attempts.
Invite clarification and constructive criticism. Ask the AI to question uncertain assumptions rather than guess or agree automatically.
Work iteratively. Review outputs, test suggestions, and revise decisions as new information appears.
Verify important claims and protect sensitive information. Check reliable sources and actual results; avoid sharing passwords, API keys, or unnecessary personal data.
A reusable instruction for an exploratory project might be: “I don’t know the final result yet. Help me work step by step, explain trade-offs, challenge weak assumptions, and ask when an important detail is missing. Don’t make major changes without my approval.” That is enough to establish a productive process without pretending to be a technical expert.
Frequently Asked Questions
Do I need a prompt engineering course to use ChatGPT?
No. Most people can begin with ordinary questions and follow-up messages. A course may help if you want to build automated workflows, evaluate model behavior systematically, or handle complex repeatable tasks.
Are longer prompts more accurate?
Not automatically. Relevant context and clear constraints can help, but length alone does not guarantee accuracy. Important claims still require verification.
Can AI ask me questions instead of making assumptions?
Yes. You can ask an assistant to clarify missing requirements before proceeding. For simple tasks, it may be more efficient to answer directly and state any assumptions.
Does saying “act as an expert” unlock special capabilities?
No. It can influence perspective or style, but it does not add tools, credentials, or guaranteed expertise.
Can I use the same prompts with different AI models?
Often yes. General instructions transfer well, but results, memory, available tools, and application features differ.
Conclusion: Better Conversations, Not Magic Words
Prompt engineering has genuine value, especially when AI must perform defined tasks consistently and at scale. But everyday users do not need to master a secret language before they can benefit from AI. They can ask, explore, disagree, correct, and learn through conversation.
The most useful skills are familiar human ones: explaining your goal, sharing relevant context, recognizing uncertainty, asking follow-up questions, and checking whether the answer works. AI should help carry some of that communication burden, not place all of it on the person asking for help.
So start with the question you actually have. If the answer is incomplete, keep talking. Sometimes one word is enough; sometimes a hundred words aren’t.
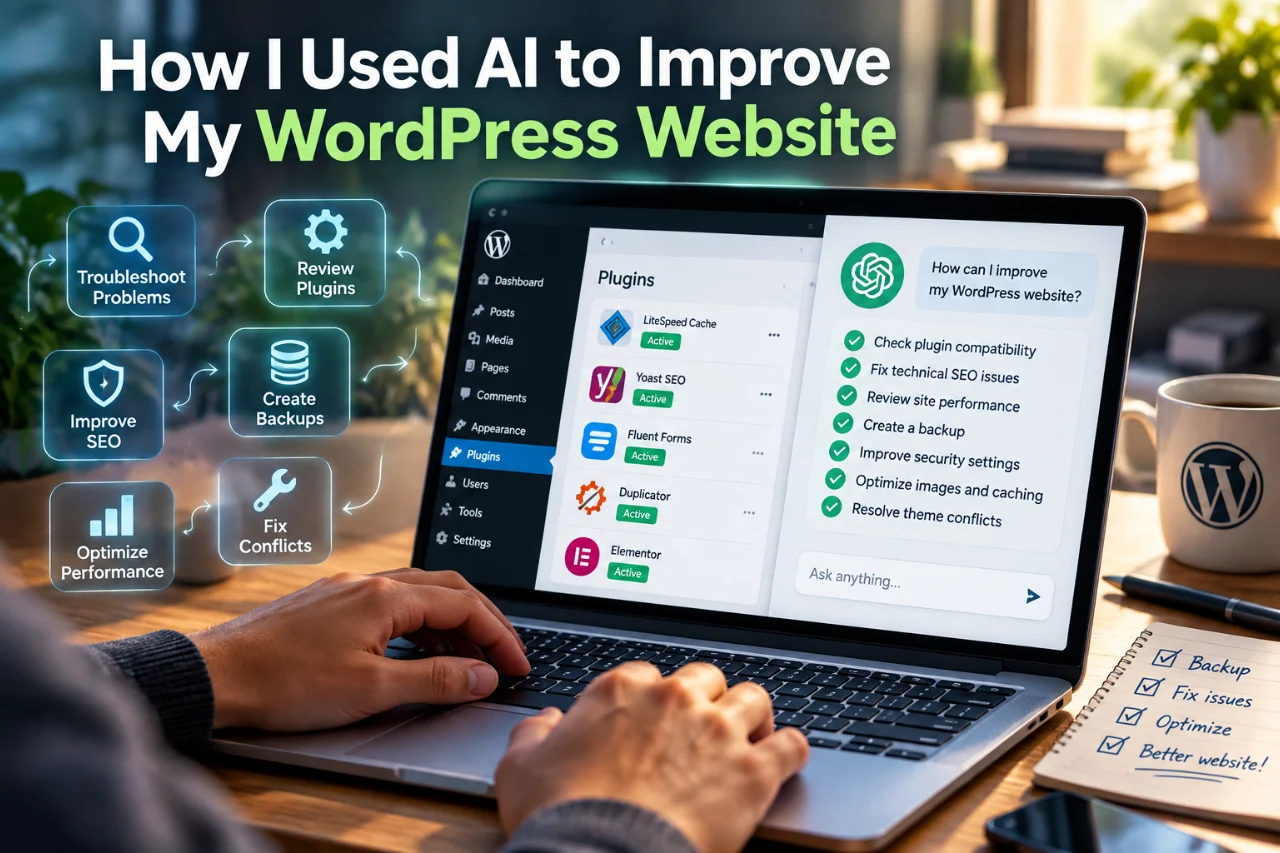
Can a beginner use AI to improve a WordPress website? Yes—but the useful part is not asking AI to “optimize everything.” The better approach is to use AI as a technical partner: give it access only to the information and actions it needs, make a backup, inspect the site, diagnose one problem at a time, make reversible changes, and verify the result.
I learned this while improving TechEduCareer. I was not approaching the project as a WordPress expert. I wanted to understand what was wrong, what actually mattered, and what could safely be fixed. AI helped with the investigation, but I remained the person approving important decisions. For a separate real-world example, see how we built a lightweight WordPress plugin for social publishing.
What AI can actually do for a WordPress website
An AI assistant can be useful far beyond writing blog posts. Depending on the tools and permissions available, it can help inspect WordPress settings, review plugins, analyze page HTML, find broken or outdated links, examine SEO configuration, interpret browser-console errors, check sitemaps and robots directives, suggest internal links, draft content, and explain unfamiliar technical information in plain language.
The important distinction is between advice and action. An AI can tell you what it thinks should change. A connected AI tool may also be able to make that change. Those are not the same risk level.
Step 1: Make a backup before letting anything change
This became one of my most important rules. Before a meaningful round of website changes, create a restorable backup. WordPress itself recommends regular backups so you can restore your site if an update causes trouble.
A backup changes the whole working style. Instead of being afraid to touch anything, you can make careful, reversible changes and test them. It does not justify reckless changes, but it gives you a recovery point.
How I backed up my WordPress website using Duplicator
For my own website, TechEduCareer, I used the Duplicator WordPress plugin to create a backup before making significant changes.
The process is straightforward:
Install and activate Duplicator from the WordPress plugin directory.
Open Duplicator → Backups and create a new backup.
Select a full-site backup that includes both the WordPress files and database.
Run the backup and wait for it to finish.
Download the backup archive and any accompanying recovery or installer file provided by your Duplicator version.
Store the downloaded files somewhere safe, preferably outside your hosting account.
I particularly recommend keeping an offline copy. If your hosting account becomes inaccessible, a backup stored only on that same server may not help.
One important lesson: a successful backup doesn’t automatically guarantee a successful restoration. Ideally, test the recovery process on a staging website before relying on it for major changes.
With a backup available, I could experiment more confidently, knowing I had a recovery option if something went wrong.
Step 2: Give AI context, not your passwords
At first, a beginner may think the easiest approach is to paste administrator credentials into an AI chat. Do not do that. Passwords, API keys and other secrets should stay private.
A safer model is to use an authorized connector or management tool that exposes specific WordPress capabilities. In my case, the AI could inspect and perform supported WordPress operations through an authorized connection while I retained control over sensitive or destructive actions. Some steps still required me to use the WordPress interface manually.
This division of responsibility turned out to be useful: AI could do the repetitive inspection and analysis, while I handled credentials, approvals and decisions that could have larger consequences.
Step 3: Let AI inventory the site before fixing it
Before changing a WordPress site, ask: What theme is active? Which plugins are installed? Which are active? What WordPress and PHP versions are running? Which SEO and caching plugins are involved? What content types exist?
Taking inventory helps prevent a common beginner mistake: installing another plugin every time there is a problem. Sometimes the better solution is to configure an existing plugin correctly—or remove a plugin that is no longer needed.
Step 4: Review plugins by purpose, not by quantity alone
We reviewed plugins individually: what does this plugin do, is that function still needed, does another plugin already provide it, and does it add front-end code or maintenance overhead?
I removed several plugins that no longer had a useful role. Others stayed because they supported functions I still needed. The goal was not to reach an arbitrary “perfect” plugin count. It was to understand why each component existed.
A real example: tracing a JavaScript error to the actual plugin
This was one of the most useful lessons from the project. The browser console reported a JavaScript syntax error in a file generated by LiteSpeed Cache. It would have been easy to conclude that LiteSpeed was broken and disable optimization.
Instead, we traced the generated file back to the WordPress script that supplied the code. We traced the source to a front-end vendor bundle from UserFeedback, a plugin I had previously installed while looking for a simple Facebook-style “Like” feature.
UserFeedback was not actually needed for that purpose. I removed it, cleared the relevant caches and tested again in a clean browser session. The syntax error disappeared.
The lesson was bigger than one plugin: a filename tells you where an error appeared, not necessarily where the error originated. AI was useful because it could follow the evidence across the browser console, generated cache file, WordPress script handle and plugin inventory instead of guessing.
Step 5: Use AI to understand SEO settings instead of chasing scores
We then worked through the technical SEO foundation: page titles and meta descriptions, canonical URLs, XML sitemaps, robots directives, indexation settings, schema, author information, internal links and redirects.
This also taught me that an SEO audit warning is not automatically a problem. For example, if you deliberately mark a page noindex, you don’t need to optimize it as though it were an important search landing page. Keeping thin tag and archive pages out of search may be more useful than adding artificial descriptions just to quiet an audit report.
Step 6: Check what search engines can actually discover
We verified the public sitemap and robots file rather than assuming the settings screen was enough. We also connected the site to Google Search Console and Bing Webmaster Tools and submitted the canonical sitemap.
Here’s a useful habit for AI-assisted work: verify the output, not just the setting. If a plugin says a sitemap option is enabled, inspect the public sitemap. If a redirect was created, request the old URL and confirm the HTTP response. If a page should be noindexed, inspect its rendered robots meta tag.
Step 7: Improve content for people, search and AI answers
We reviewed the existing articles and improved titles, search intent, direct answers, headings, internal links and metadata. The aim was not to stuff keywords into every paragraph. It was to make each article easier for a person—and for a search or AI system—to understand.
For answer-oriented content, I found a simple structure useful: answer the main question early, use descriptive headings, explain important distinctions clearly, link related topics, and support factual claims with reliable sources. The same principles make content easier to quote, summarize and navigate.
Step 8: Use AI to find causes, not just symptoms
Another audit reported internal links using HTTP instead of HTTPS. Searching the article bodies did not find the links. We kept investigating and discovered that approved WordPress comments contained an old http://techeducareer.com author URL. WordPress rendered those comment-author links on the affected pages, where the crawler found them.
After removing the unnecessary comments and crawling the site again, the errors disappeared. This is exactly the kind of task where an AI assistant can save time: correlate the crawler report with rendered HTML, WordPress content and configuration instead of repeatedly editing the article itself.
Step 9: Measure before and after
We used an external site audit as one verification layer. During the final cleanup, the Ahrefs Site Audit Health Score moved from 99 to 100 and the reported technical errors went from two to zero. That does not mean a score of 100 guarantees rankings, traffic or AI citations. It means we resolved the specific technical issues that the crawl detected.
That distinction matters. AI can help you make a technically cleaner website, but it cannot promise first place on Google, traffic growth or inclusion in an AI-generated answer.
What I would not let AI do blindly
Delete plugins, files or database records just because they look unused.
Make broad search-and-replace operations without a backup and preview.
Change themes or production code without understanding the rollback path.
Share passwords, private API keys or authentication codes in chat.
Publish AI-written factual claims without checking reliable sources.
Chase every SEO audit warning simply to maximize a score.
A good rule is simple: the larger the possible impact, the more human review you want before execution.
A beginner-friendly AI + WordPress workflow
Create and verify a backup.
Explain your goal and current problem to the AI.
Let it inspect the relevant settings and evidence where authorized.
Ask it to explain the likely cause before proposing a fix.
Prefer the smallest reversible change.
Make sensitive or destructive changes manually or with explicit approval.
Clear caches when relevant.
Verify the public result independently.
Record what changed so you can reverse it.
Re-run the relevant audit or test.
Useful tools in an AI-assisted WordPress workflow
The exact stack will differ from site to site. In this project, different tools had different jobs: WordPress provided the publishing platform and Site Health information; an SEO plugin managed search metadata and schema; a caching plugin handled performance optimization; search-engine webmaster tools showed discovery and indexing information; a crawler provided an independent technical audit; the browser developer console exposed front-end errors; and the AI assistant connected the evidence and helped plan or perform supported changes.
WordPress also documents a troubleshooting approach in which plugins can be isolated to identify conflicts. The principle is worth remembering even if you use different tooling: test hypotheses rather than randomly changing settings.
What I learned as a beginner
The biggest surprise was that I did not need to become a WordPress developer before I could understand and improve my website. AI reduced the distance between seeing a technical problem and understanding what it meant.
But AI worked best when I treated it as a collaborator, not an autopilot. I asked questions, checked changes, sometimes did the manual step myself, and learned enough along the way to make better decisions the next time.
If you are building a new website, you may also find our website launch and promotion checklist useful. The technical cleanup described here is only one part of growing a site; useful content, authority, distribution and patience still matter.
Frequently asked questions
Can ChatGPT or another AI fix a WordPress website?
It can help diagnose problems, explain settings, write or review code and content, and—when connected through an authorized tool—perform supported WordPress actions. It should not be given unlimited control or sensitive credentials, and important changes still need human review and verification.
Do I need to know coding to use AI with WordPress?
No. Many useful tasks require no coding. However, understanding basic WordPress concepts, HTML, caching and browser developer tools gradually makes AI-assisted troubleshooting more effective.
Should AI automatically remove plugins it thinks are unnecessary?
No. First identify what each plugin does and whether the site depends on it. Deactivation is often a safer test than immediate deletion, and a backup should exist before meaningful changes.
I started Watt because I like learning things I did not know I wanted to learn. A question leads to an explanation, the explanation leads to another question, and suddenly an ordinary subject becomes interesting. The difficulty was that the material I wanted was scattered across websites, with different levels of detail and very different standards of evidence. Collecting facts in one place seemed useful. Building that place taught me that collecting them was only the beginning.
Watt is now a free library of more than 2,000 facts in Ukrainian and English. Readers can explore topics, choose an explanation level, read or listen, and try a short quiz. I built it as a solo founder, and its development has involved the content workflow as much as the interface. My experience is a product-building story, rather than evidence that this format improves learning. I have not yet measured educational efficacy.
Why a surprising fact needs an explanation
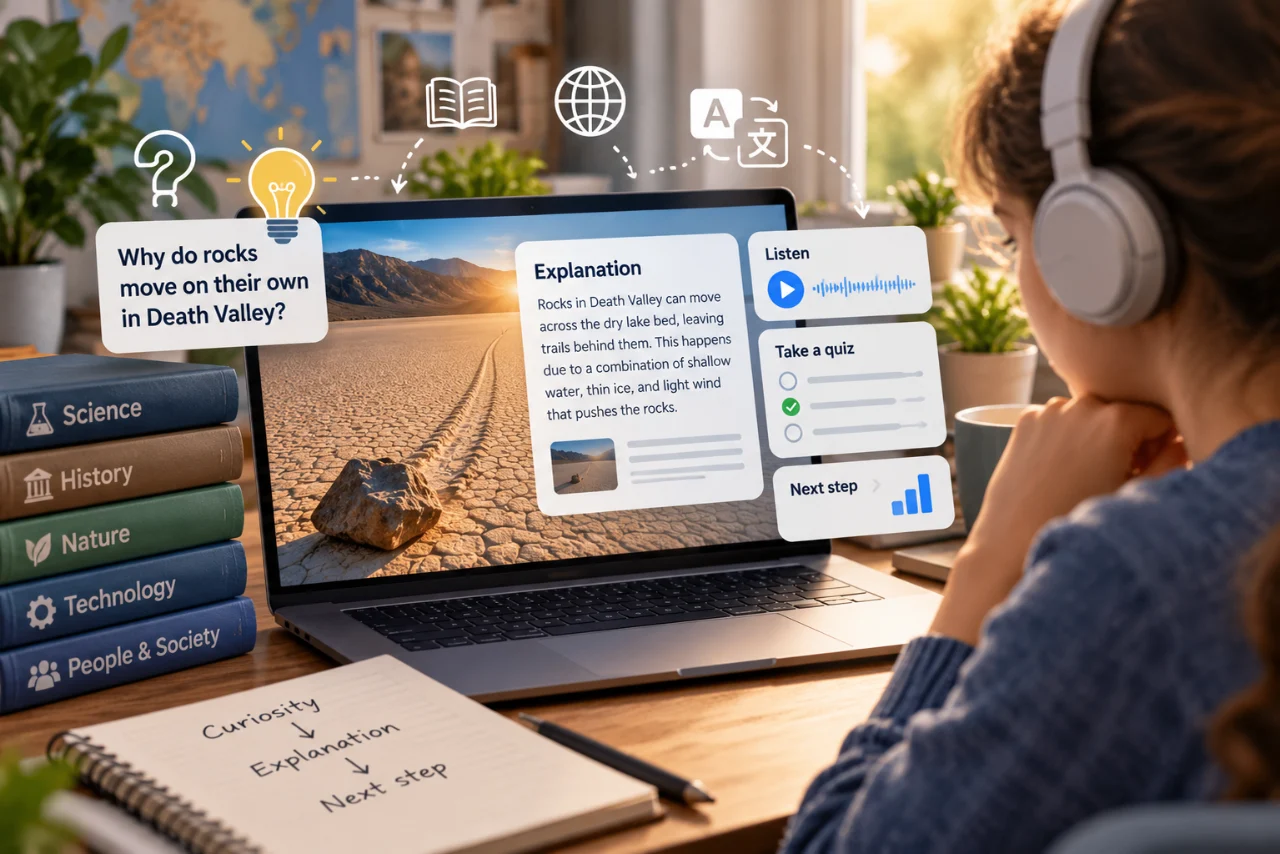
The first challenge was deciding what a useful fact page should actually do. A surprising sentence can attract attention, but it may also leave the reader with a misleading impression. Consider the rocks that leave trails across Racetrack Playa in Death Valley. Saying that the rocks move is intriguing. Explaining the observed combination of shallow water, thin ice panels and light wind gives the reader something more useful: a mechanism to understand. The sources behind that explanation matter because they distinguish a recorded observation from an appealing story.
That example also shows why brevity is a difficult editing problem. A short version should keep the mechanism intact. A longer version can explain how researchers observed the movement and why the conditions occur infrequently. Adding more words does not automatically make an explanation better, and removing words can accidentally remove the condition that makes a claim accurate. I came to think of explanation levels as different ways into the same subject, each of which needs to preserve the underlying meaning.
The challenge of keeping two languages accurate
Working in two languages makes that problem more visible. A translation can sound natural while changing the strength of a claim. Words such as “can,” “usually,” and “under these conditions” are small, but losing them changes what the reader is being told. A practical check is to compare the claim rather than just the wording: does each version describe the same mechanism, scope and uncertainty? Fluent language and factual agreement are separate requirements.
The same applies to a catchy title. A title about humans glowing needs an explanation that the light is too faint for unaided eyes and was measured with specialized equipment. It should not encourage the reader to confuse ultraweak photon emission with a thermal image. The useful editorial question is not just whether a sentence is technically defensible. It is what someone is likely to believe after reading it quickly.
Why audio narration changes the writing
Audio was another important part of the product. I wanted readers to be able to listen rather than making reading the only way to explore a subject. But narration makes weaknesses in writing easier to hear. A sentence with several qualifications may be understandable on screen and cumbersome aloud. References that work as links are not naturally spoken. Numbers and unfamiliar names can interrupt the flow. Treating audio as another version of the experience, rather than simply another file to generate, creates a reason to revisit the explanation itself.
Designing quizzes that reinforce understanding
Quizzes introduced a different kind of discipline. The question needs to be understandable on its own, and the options need one clearly intended answer. In the sailing-stones example, a useful question asks what actually pushes the rocks. It points back to the explanation’s mechanism. A vague question about whether the rocks are “mysterious” would mostly test the wording of the page. I want a quiz to give the reader another way to engage with an idea, while being careful not to interpret a correct click as proof of durable learning.
What early testers taught me about returning
Early testers pushed me to think beyond individual fact pages. Their feedback was that there needed to be something that made people want to return and continue. That influenced my work on the wider experience: topic choice, progression, saved interests and gamification. These features give curiosity somewhere to go after the first interesting page. For a broader look at how playful activities can support education, see TechEduCareer’s guide to game-based learning. The question became how to make the next step clear without turning every moment into a demand for another click.
Build one complete learning journey first
For someone building a similar product, I would start by making one complete journey work. Can a new visitor choose something interesting, understand it, hear it if they prefer, inspect the source, and answer a useful question? That journey exposes dependencies that a feature list hides. A quiz depends on an explanation. Narration depends on a usable script. A convincing illustration depends on an accurate caption and a clear account of its origin.
AI-assisted workflows still need human judgment
Connecting those pieces into an agent-assisted workflow has been one of the hardest parts. AI can help produce and revise material, but it does not remove the need to check claims, preserve source relationships or distinguish synthetic illustrations from documentary photographs. Nor does an automated sequence become reliable merely because it runs repeatedly. The meaningful unit of work is the complete page and the reader’s experience of it, rather than a count of generated assets.
What I still need to learn
The library’s growth gives me more opportunities to find inconsistencies, not a reason to assume the work is finished. I still need better evidence about which experiences people value, why they return, and what they remember. A growing content count, a successful publication or an encouraging comment can be useful signals, but they answer different questions. My main lesson is to keep those questions separate while building a path that is easy to try.
I began with a personal interest in unusual facts. The project has made me equally interested in what happens immediately after the surprise. A useful explanation, a voice to listen to, a source to inspect and a question to consider can give that moment somewhere to lead. Whether it becomes a lasting learning habit is something I still need to learn from the people using it.
Disclosure: The author is Watt’s founder. This article was prepared with AI writing assistance. Watt’s educational efficacy has not yet been measured.
Scientific references
Norris et al., “Sliding Rocks on Racetrack Playa, Death Valley National Park: First Observation of Rocks in Motion,” PLOS ONE (2014). Read the study.
Kobayashi et al., “Imaging of Ultraweak Spontaneous Photon Emission from Human Body Displaying Diurnal Rhythm,” PLOS ONE (2009). Read the study.
For several days, I was searching for the right graphic design software. I tried different applications, watched tutorials, and even looked into online courses. My goal wasn’t to become a professional designer. I simply had an idea for a logo and wanted to turn it into something I could actually use.
That sounds straightforward—until you open a design program for the first time. Suddenly, your idea has to wait while you figure out layers, paths, alignment, shortcuts, and a dozen unfamiliar tools. I wasn’t short of ideas. I was short of time to learn another application.
Then I discovered VectorCraft, an open-source vector graphics editor from the ArtCraft project.
What caught my attention wasn’t only the editor itself. It was the possibility of connecting it to ChatGPT using the Model Context Protocol (MCP).
That raised a question I couldn’t resist: What if I could explain what I wanted to create instead of learning every button needed to create it?
From an Idea to an Experiment
I decided to test the idea on my Windows computer. After installing VectorCraft, I found that it included a command-line component capable of exposing drawing tools through MCP. With the editor running locally, I configured ChatGPT to connect to it.
It took some exploration to get the connection working. We checked the installed files, examined the available commands, confirmed that the local connection was listening, and configured the MCP server in ChatGPT. This wasn’t a magical one-click setup—and that is worth saying.
Connecting ChatGPT to VectorCraft: Setup and Verification
To let ChatGPT create and edit objects directly in VectorCraft, enable VectorCraft’s local control interface and configure its MCP connection in the ChatGPT desktop application. These steps use Windows and the default VectorCraft installation directory.
Step 1 — Start VectorCraft with local control enabled
Close any VectorCraft window that was opened normally. Open Windows PowerShell, then copy and run:
The CommandLine should contain vectorcraft.exe" --control 7979. The process ID may differ on your computer.
Step 4 — Check whether the connection port is accessible
In PowerShell, run:
Test-NetConnection 127.0.0.1 -Port 7979
Look for TcpTestSucceeded : True. This means the local port is accepting TCP connections. If it shows False, confirm that VectorCraft is still open with --control 7979 and that the MCP configuration uses the same port.
Note: A successful TCP test confirms that the port is reachable, but does not by itself verify the MCP integration.
Step 5 — Verify the connection through ChatGPT
Return to ChatGPT Desktop, confirm that VectorCraft MCP is enabled, and open a chat. Ask ChatGPT to create an object on the current VectorCraft canvas. If the object appears and can be selected and edited in VectorCraft, the connection is working.
But once the connection worked, something changed. Instead of asking ChatGPT to tell me how to draw, I could ask it to draw in the actual application.
The First Proof: A Simple Rectangle
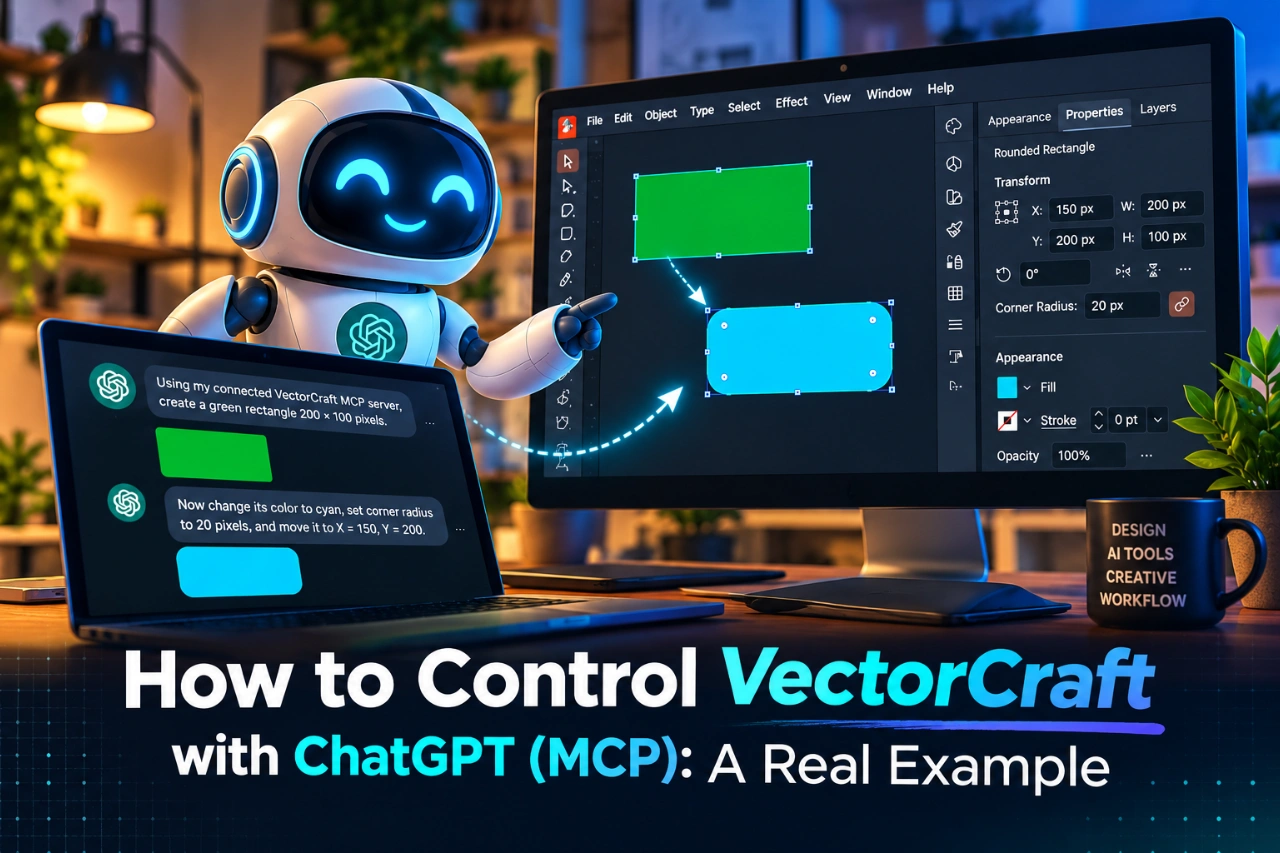
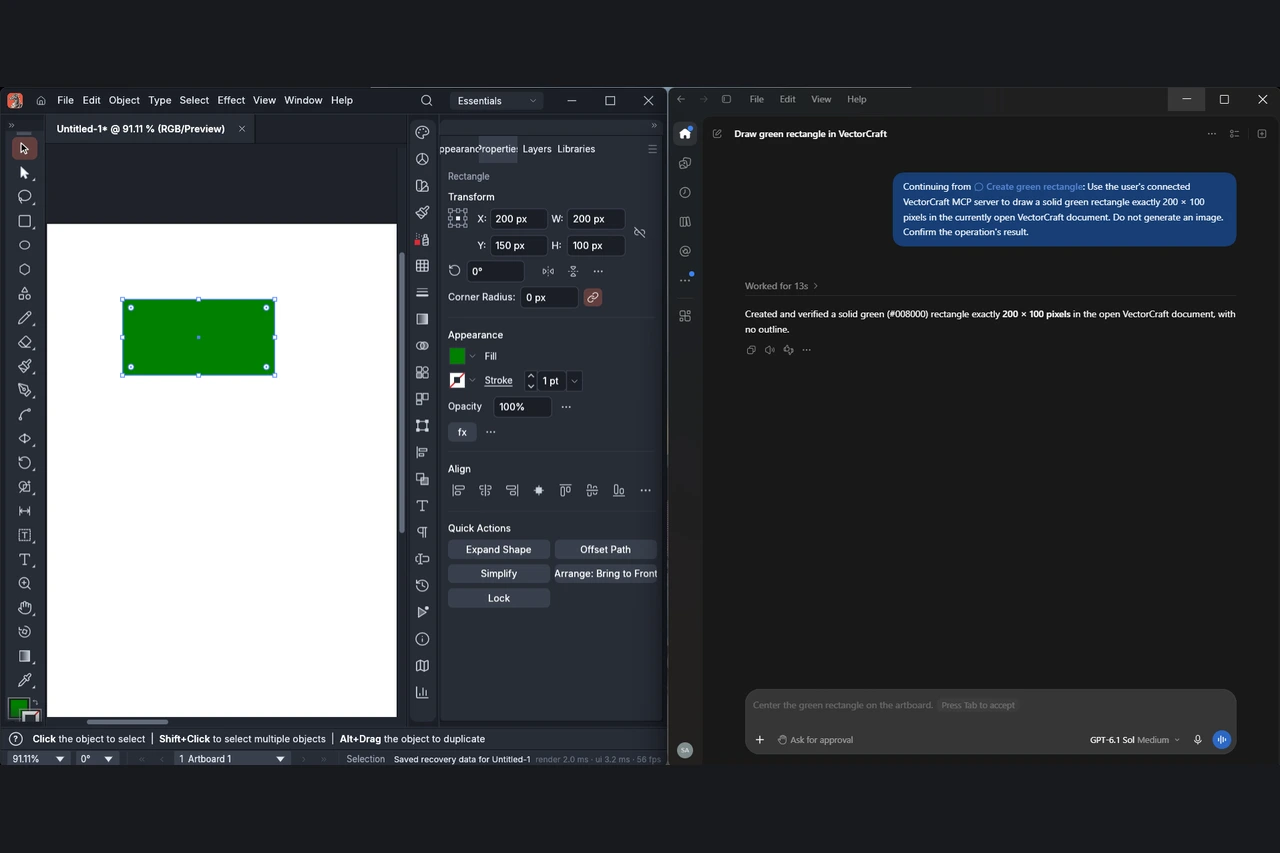
Our first successful test was deliberately modest. I asked ChatGPT to create a green rectangle, 200 by 100, in the open VectorCraft document, using the editor’s drawing tools rather than generating an image.
The rectangle appeared on the canvas as a real, editable vector object. I could select it, inspect its properties, and continue working on it inside the software.
It may not sound impressive. After all, drawing a rectangle manually is easy. But the rectangle wasn’t the point. The important part was that a conversational instruction had become an editable object in a separate design application.
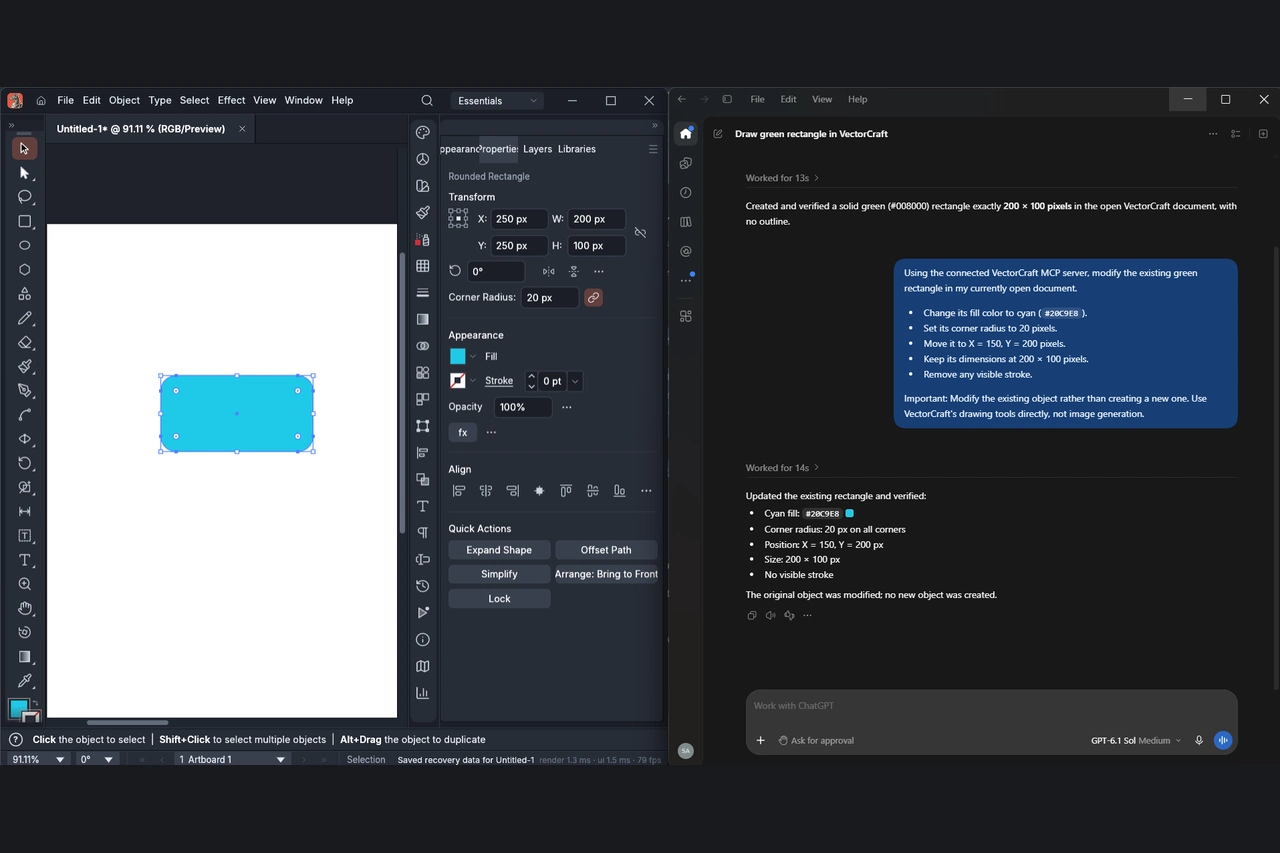
Then we took the test further. I asked ChatGPT to modify the existing rectangle: change its fill to cyan, round its corners, move it to specific coordinates, keep its dimensions unchanged, and remove its outline.
It updated the same shape rather than replacing it with a new picture. The properties panel confirmed the cyan fill, 20-pixel corner radius, 200 × 100 pixel dimensions, and no visible stroke.
There was one detail worth checking: although ChatGPT reported moving the shape to X = 150 and Y = 200, the editor’s Properties panel showed X = 250 and Y = 250. That small mismatch was a useful reminder to verify AI actions in the actual software rather than relying only on its confirmation.
This was the moment the experiment became genuinely interesting to me. I wasn’t just producing an image from a prompt. I was iterating on a design through conversation.
Why Editable Vector Objects Matter
There is an important difference between asking an AI image generator for a logo concept and asking an AI assistant to work inside vector-editing software.
An AI-generated picture can be useful for inspiration, but it isn’t necessarily made of separately editable design elements. In our experiment, the result was a shape inside VectorCraft, with properties we could inspect and change. That meant we could refine the object without starting from scratch each time. It reminded me of my earlier experiment building a WordPress tool with ChatGPT: the interesting part was letting AI work inside real software, not simply asking it for advice.
For someone trying to translate a mental picture into a practical design, that difference matters. It turns AI from a source of suggestions into a collaborator that can perform specific operations in the tool you’re using.
What MCP Actually Changed
MCP, or Model Context Protocol, is a way for AI assistants to connect with compatible tools and services. In this case, the connection allowed ChatGPT to use VectorCraft’s drawing capabilities. The official MCP documentation explains how the protocol connects AI applications with external tools.
Without that connection, ChatGPT could explain where to click or suggest steps to follow. I had already explored which AI tools support MCP, but seeing one actually operate a design editor made the idea much more tangible. With it, I could describe an action and see the result directly in the editor.
We used VectorCraft version 0.11.0 on Windows for this experiment. Our setup involved its local control connection and a separate command-line MCP component. Those details are useful for a future tutorial, but the bigger lesson isn’t tied to one version or one application: when an AI assistant can operate real tools, the way we learn and use software starts to change.
Did AI Do Everything for Me?
No—and I wouldn’t want to tell the story that way.
I still had to decide what I wanted, describe it clearly, look at the result, and decide what should change. Some instructions needed refinement. The software connection also required setup and troubleshooting. The AI could carry out drawing operations, but it couldn’t decide whether a design communicated the right idea or looked professional.
That distinction matters, especially when we talk about the future of creative careers. Designers bring much more than software proficiency: visual judgment, research, composition, accessibility, consistency, and an understanding of the people a design needs to reach.
What this experiment suggests is not that those skills become unnecessary. It’s that people with ideas may be able to start experimenting sooner, without first spending weeks mastering an unfamiliar interface.
What This Could Mean for Students and Beginners
Think about a student creating a poster, a small-business owner testing a visual identity, or a beginner exploring digital illustration. Traditionally, the first challenge is often learning the software well enough to express the idea.
AI-assisted creative tools could lower that initial barrier. You might begin by describing a shape, adjusting its dimensions, trying a different arrangement, and learning the design concepts along the way.
That doesn’t remove the value of learning design software. In fact, understanding how the software works can help you give better instructions and spot mistakes. But it changes where the learning journey can begin: with an idea and a willingness to experiment.
The Bigger Discovery Wasn’t the Rectangle
I originally set out to work on a logo. I’m not sharing that design here, because the finished logo isn’t what this story is about. The small rectangle experiment explains the discovery much better: I could ask an AI assistant to create an object, then modify that very same object inside a real vector editor.
A few days earlier, I had been asking myself which software I needed to learn. Now I was asking a different question: How clearly can I explain what I imagine?
I don’t think technical skills will disappear, and I don’t think every creative task will become effortless. But I do think we’re entering an interesting period in which imagination, communication, and the ability to judge results can take a more central role.
The future of creativity may depend less on knowing which button to press—and more on knowing what you want to create.
For me, that’s a far more exciting discovery than a perfectly drawn rectangle.
Your friend messages you on Instagram asking for money. Strange, because you were having pizza together yesterday, and they definitely didn’t mention needing an emergency loan.
A few minutes later, you discover their account was hacked. Their password wasn’t enough to keep someone out. But what if there had been a second lock on the door?
That’s where two-factor authentication (2FA) comes in. It’s one of the simplest ways to protect your online accounts, and it’s much easier to use than it sounds.
Why Your Password Needs a Sidekick
Think about how many accounts you have. Email, Instagram, TikTok, gaming platforms, shopping websites, streaming services, and probably a few you’ve completely forgotten.
Now think about how many passwords you remember. If the answer is suspiciously small, you’re not alone.
Passwords can be stolen in several ways. A website might suffer a data breach, exposing account information. Someone might trick you into entering your password on a fake login page, a scam called phishing (the NIST authentication guidance explains why some login methods resist this kind of attack better than others). Or you might reuse the same password on several websites.
Imagine using one key for your house, car, office, and bicycle. Convenient? Absolutely. A brilliant security plan? Not so much.
That’s why a strong, unique password is a great beginning, but shouldn’t always be your only protection.
Imagine someone finds your house key. Normally, that’s enough to get inside. But what if your door also required a code that only you could provide?
That’s the idea behind two-factor authentication.
When you log in to a website, your password is usually the first check. The second might be a code from your phone, a physical security key, or another way of proving it’s really you.
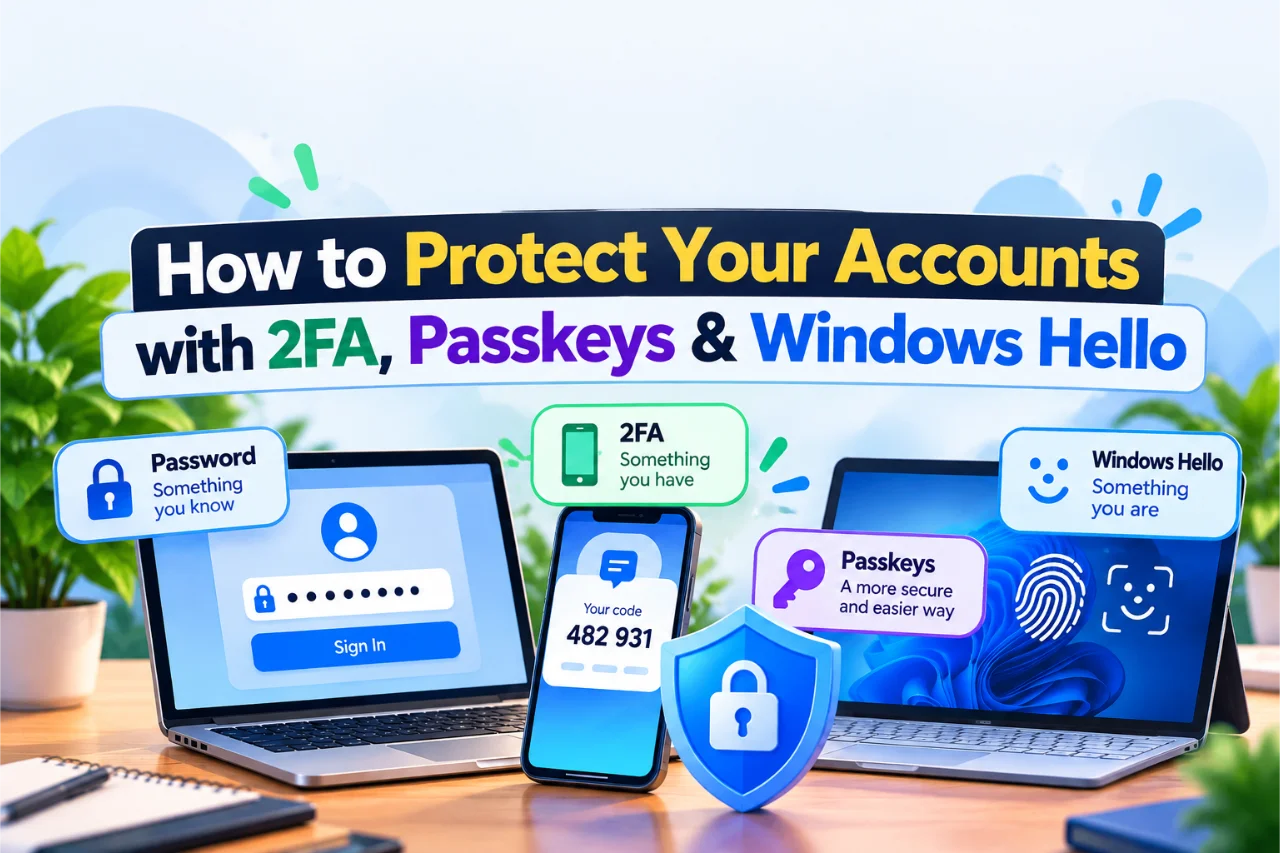
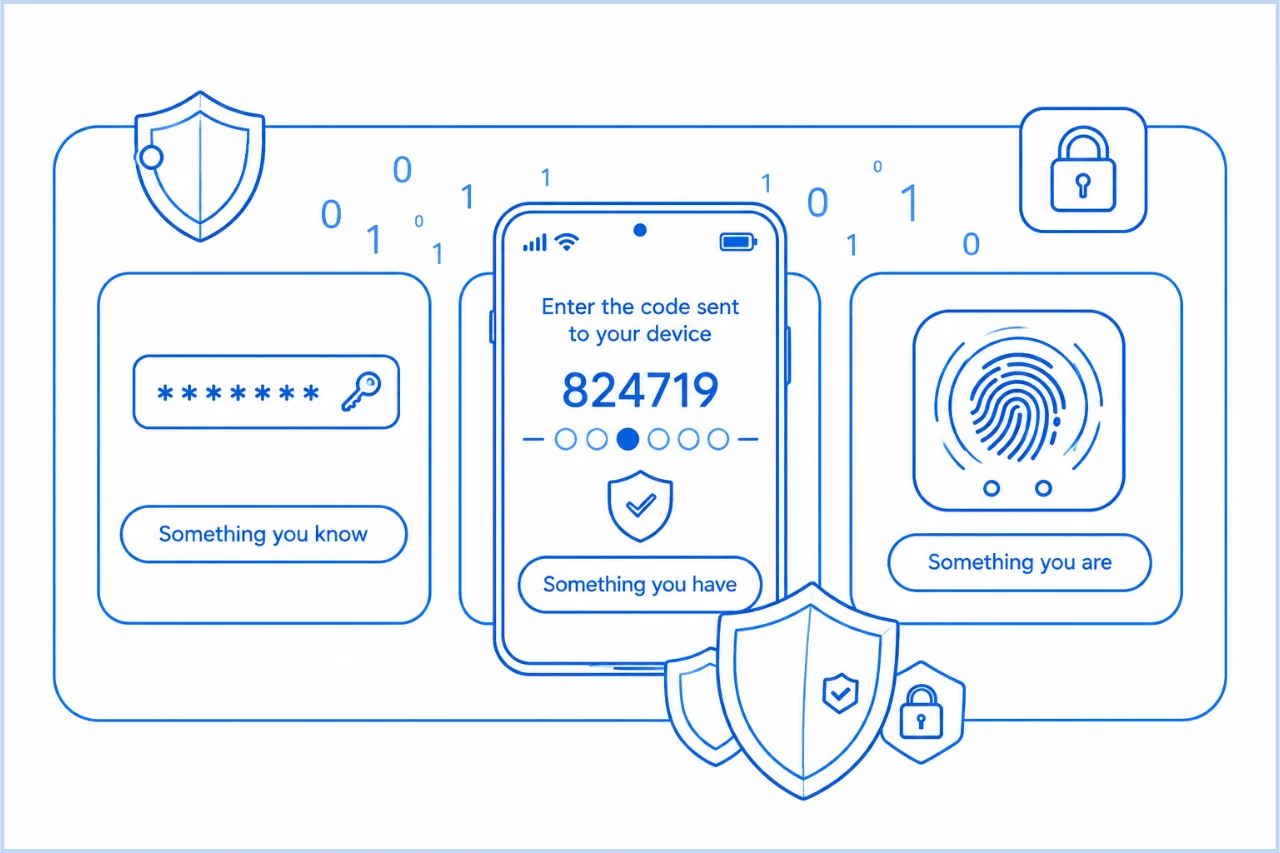
Security experts group these checks into three categories: something you know (a password or PIN), something you have (your phone or a security key), and something you are (your fingerprint or face). That’s the whole list—no special vocabulary required.
The important part is combining two different kinds of proof. Entering two passwords doesn’t count as two-factor authentication, because both are things you know.
You might also see the abbreviation MFA, meaning multi-factor authentication. It’s the broader name for using two or more authentication factors.
And that’s really all you need to understand before we look at the different methods.
Quick tip: If a website offers 2FA, turn it on—especially for your main email account. Your email is often the key to resetting passwords for everything else.
The 3 Most Common 2FA Methods
There are several ways websites can ask for that second piece of proof. Some are easier to use, while others offer better protection against scams.
Method
What’s good
What’s less good
Strength
SMS codes
Simple, works on most phones
Codes can be phished; phone numbers can be hijacked
Basic
Authenticator apps
Free, often work offline, stronger than SMS
Codes can still be stolen through fake login pages
Good
Hardware security keys
Excellent phishing protection
You need a compatible key and a backup plan
Very strong
These are general comparisons, not guarantees. Actual protection also depends on how the service handles login and account recovery.
SMS codes: the familiar text message
You enter your password, and the website sends a six-digit code to your phone. You type the code, and you’re in.
It’s easy, and it’s certainly better than having no second factor. But scammers can trick you into giving them that code, sometimes using a fake website that looks almost identical to the real one.
Criminals can also sometimes take control of a phone number through a SIM-swap attack, where they convince a mobile provider to transfer the number. So SMS is useful, but it isn’t the strongest option.
Authenticator apps: a little stronger
Apps such as Google Authenticator and Microsoft Authenticator can generate temporary login codes on your phone. Many of these codes change every 30 seconds and work without mobile reception.
That’s handy when you’re traveling or your phone signal decides to take a holiday.
Authenticator apps generally provide better protection than SMS because they don’t depend on your phone number. However, a convincing phishing website can still steal a code if you type it there.
Security keys: the physical option
A hardware security key is a small device, sometimes resembling a USB stick, that helps prove you’re signing in to the correct website.
Hardware security keys from brands such as YubiKey and Google Titan, along with other FIDO2-compatible devices, can provide phishing-resistant sign-ins. You might plug one into your computer or tap it against a compatible phone. One security key can protect multiple accounts—you don’t need a separate key for every website.
The clever part? A properly implemented FIDO2 login is tied to the real website. A fake copy can’t simply collect a reusable code and use it elsewhere.
Hardware keys are especially useful for people protecting important accounts. But they’re not mandatory for everyone, and having a backup key or recovery method matters.
Passkeys: what if you didn’t need a password at all?
Here’s where things get interesting. A passkey lets you sign in without typing a traditional password. Instead, you might use your phone’s fingerprint reader, facial recognition, or device PIN.
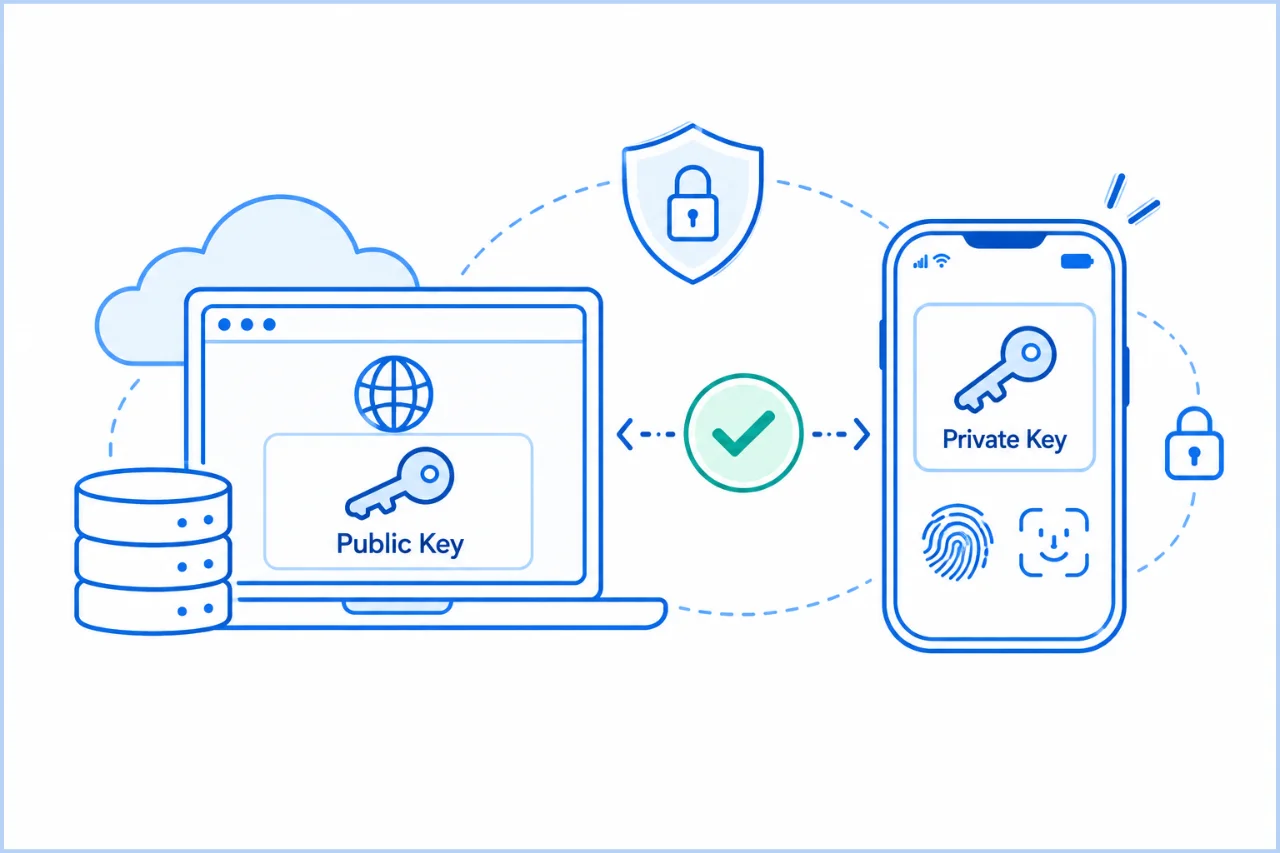
Behind the scenes, a passkey uses two matching digital keys. The website receives a public key, while the private key stays protected by your device or passkey provider. Some passkeys can also be securely synchronized between your devices.
When you sign in, your device proves it holds the private key without handing that secret to the website. Imagine a lock that checks your key without taking it away. That’s the basic idea.
Why passkeys are harder to steal
Traditional passwords can be typed into convincing fake websites. Passkeys work differently. They are connected to the legitimate website’s identity, so a fake website generally can’t trick your passkey into authenticating it as the real one.
That’s why passkeys are considered phishing-resistant.
They’re not magic, of course. Someone could still try to trick you into approving an action, compromise your device, or abuse an account’s weaker recovery options. But passkeys remove several common problems that come with passwords.
Can passkeys work across your devices?
Yes, depending on where they’re stored. Some passkeys are synchronized through supported password managers or device ecosystems, such as Apple’s iCloud Keychain or Google’s password-management services. Others remain tied to a particular device or hardware security key.
You may also be able to sign in on your computer using a passkey stored on your nearby phone, often by scanning a QR code and approving the request.
Support varies between websites, devices, browsers, and passkey providers, so the exact experience isn’t identical everywhere.
Windows Hello, Face ID, and fingerprints: what’s actually happening?
You’ve probably unlocked a phone by looking at it or placing your finger on a sensor. Windows Hello brings similar convenience to compatible Windows computers, using facial recognition, fingerprints, or a PIN.
Apple’s Face ID and Touch ID provide comparable device-verification experiences.
But here’s something that surprises people: your face or fingerprint isn’t normally sent to the website you’re logging into.
During normal passkey sign-in, your device checks your face or fingerprint locally. If the check succeeds, it can use your passkey to answer the website’s login request. The website gets cryptographic proof of a valid sign-in—not a photograph of your face or a copy of your fingerprint.
Is Windows Hello an extra layer on top of 2FA?
Sometimes additional checks are required, but Windows Hello isn’t automatically a third step after password and 2FA.
Consider two situations. In the traditional approach, you enter a password and then a code from your authenticator app.
With a passkey on your Windows computer, you might choose the passkey and confirm using Windows Hello. Your device holds the passkey, and your face, fingerprint, or PIN approves its use. That’s why this kind of sign-in can meet MFA requirements without asking for another six-digit code.
That combination can satisfy MFA requirements without a separate six-digit code.
Windows Hello for Business uses a device-bound cryptographic credential together with a PIN or biometric check. Personal Windows Hello and passkey experiences can differ depending on the account and service.
In other words, more login screens don’t necessarily mean more security. The goal isn’t to build a castle with seventeen doors. It’s to use the right locks.
Did you know? A device PIN used with Windows Hello isn’t the same as sending a website a password. It helps unlock a protected credential on your device. And using a fingerprint to unlock your phone doesn’t automatically mean every app on that phone has 2FA enabled.
Suggested diagram: Side-by-side login flows showing password + authenticator code versus passkey + Windows Hello.
Four security myths we can happily retire
“I’m not important enough to be hacked.”
You don’t need to be famous or wealthy to attract scammers. Many attacks are automated. Criminals try stolen passwords against large numbers of accounts, hoping some will work.
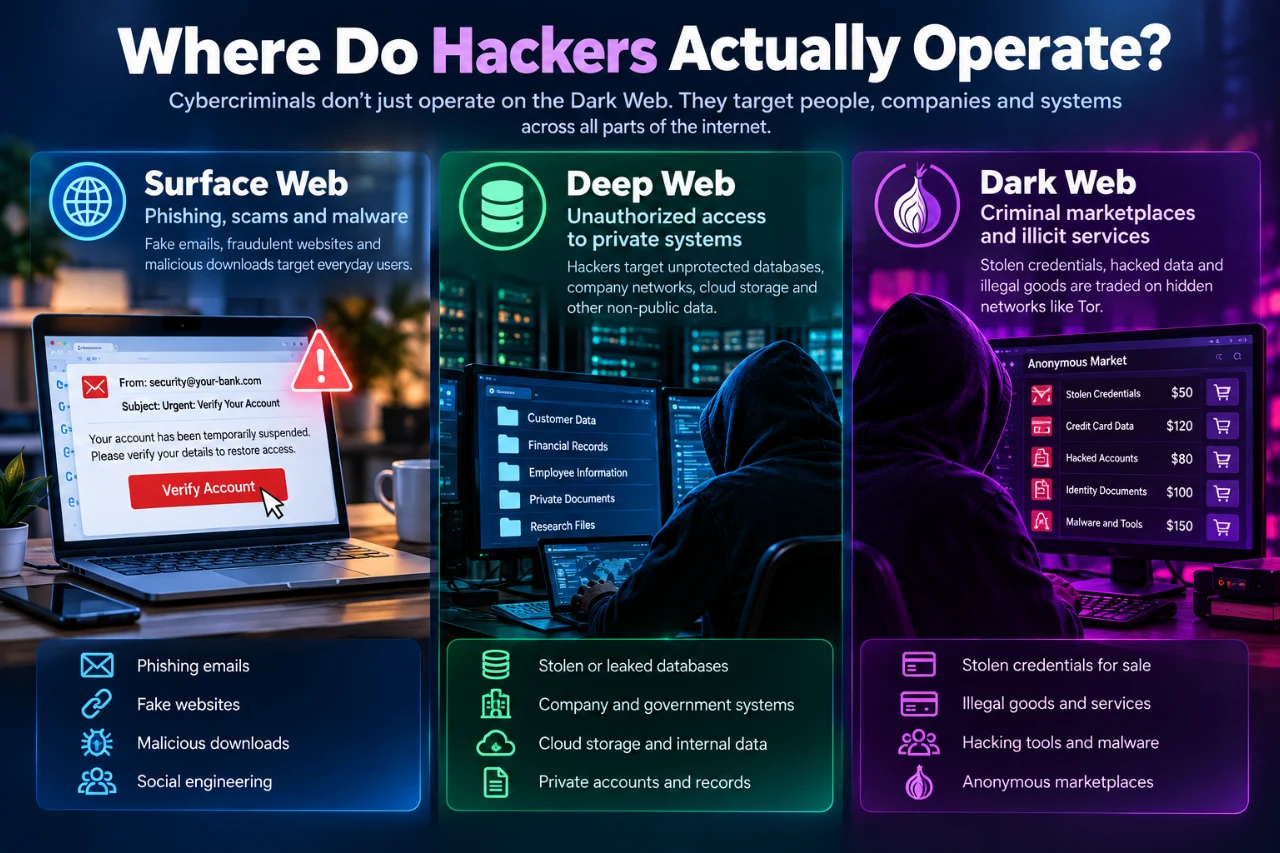
Your gaming account, email address, or social profile can still be valuable to someone else. For a wider look at where online scams and stolen data circulate, see our article on the surface web, deep web, and dark web.
“2FA is too annoying.”
Yes, entering another code can be irritating, especially when you’re in a hurry. But many services remember trusted devices, and passkeys can make secure sign-ins quicker than passwords.
A few extra seconds now can save hours of account recovery later.
“If I use Face ID, I don’t need any other security.”
Face ID can protect your device and help authorize passkeys, but it doesn’t automatically secure every online account. If a website still uses a password-only login, that account may remain vulnerable even though your phone has excellent biometric security.
“Once I enable 2FA, nobody can hack me.”
We wish! 2FA greatly reduces certain risks, but it doesn’t prevent every scam, stolen session, malicious app, or account-recovery attack. Good security means making attacks harder, not expecting a magical shield.
Your seven-step account safety plan for this week
You don’t need to become a cybersecurity expert by Friday. Start with these manageable steps.
Secure your main email account first. Give it a unique password and enable the strongest available authentication method.
Use a password manager. It can create and remember different passwords for every account.
Enable 2FA on important accounts. Prioritize email, banking, social media, shopping, and gaming.
Choose an authenticator app over SMS when possible. If SMS is the only available option, use it rather than leaving 2FA off.
Try passkeys where supported. Start with one familiar service and learn how its recovery options work.
Save your backup codes securely. Keep them somewhere accessible if your phone is lost, but not in an unprotected screenshot.
Review account recovery and connected devices. Remove unfamiliar sessions and make sure your backup methods still work.
You can spread these tasks over several days. There’s no prize for completing everything in one evening.
And please don’t experiment with deleting your only working login method before confirming that your backup works.
Quick questions you might still have
Is 2FA free?
Usually, yes. Most major online services offer at least one free 2FA option, and many authenticator apps are free. Physical security keys cost money, but they’re optional for most everyday users.
Can someone hack my account if I have 2FA?
Yes, it’s still possible. Phishing, stolen login sessions, compromised devices, and weak account recovery can create risks. However, strong 2FA significantly improves your protection.
What happens if I lose my phone?
That depends on your setup. Backup codes, another registered device, a spare security key, or supported recovery options may help you regain access. Prepare these before you lose the phone, not afterward.
Are passkeys better than passwords?
For many online sign-ins, yes. Properly implemented passkeys resist traditional phishing and eliminate password reuse. Their overall safety still depends on device security, storage, synchronization, and account recovery.
Do I need both a passkey and an authenticator app?
Not necessarily. A passkey sign-in can already provide strong multi-factor protection when it includes device-based user verification. Some services may still require additional verification for sensitive actions or recovery.
One more lock, a lot more peace of mind
You don’t have to understand every technical detail to protect yourself online.
Start with your email. Add a second factor. Try a passkey when you’re comfortable. Make sure you have a way back into your accounts if a device disappears.
Good security shouldn’t make your digital life miserable. It should help you get on with your day—without wondering why your Instagram account is suddenly advertising suspicious sunglasses.
When people ask me how to get ready for a data analyst interview, they usually expect a list of advanced topics. In reality, most analyst interviews reward strong basics, clear thinking and calm communication far more than clever tricks.
At Dataford we collect interview reports from real candidates. For data analyst roles alone, that now covers 28k+ candidate reports and about 42k reported questions across 3,400+ companies. The pattern is clear. SQL appears in about 46% of company guides, more than any other topic. Behavioral and leadership questions are the largest question category, with about 18k reports. Metrics, statistics and product sense questions fill most of the rest.
Below is how I would prepare for each part, followed by a simple plan for the weeks before your interview.
Know what the process looks like
Before you study anything, it helps to know the shape of the loop. The median data analyst process in our data has three rounds. About 85% of reports mention a recruiter or HR screen, and about 57% mention an online assessment, case study or take-home exercise. Hiring manager, panel and final rounds show up less often, but be ready for them.
In practice, you will likely face a timed test, usually SQL, before you meet the team, and you will need to explain your work to people who are not analysts.
Ask your recruiter early what each round covers. Most are happy to tell you, and the answer will save you hours of guessing.
SQL: the round that decides whether you continue
The SQL screen is a common place for candidates to drop out. Our data shows about 9.7k reported questions in the SQL and data manipulation category for analysts, which makes it the second largest category after behavioral.
The good news is that the questions are rarely exotic. In most screens you can expect:
Filtering and aggregating with WHERE, GROUP BY and HAVING
Joining two or three tables, and knowing when a LEFT JOIN changes the row count
Window functions such as ROW_NUMBER, RANK and running totals
Date logic, such as weekly signups or monthly active users over a period
Handling NULLs and duplicates without losing rows by accident
When I practice SQL, I follow one rule: write the query on paper or in a plain editor before running it. Then explain each clause out loud as if a teammate were listening. Interviewers often care more about your reasoning than perfect syntax. Saying “I am grouping by user first so each person counts once” shows you understand the data.
Also practice checking your own answer. A quick sanity check, like comparing a total against a simple COUNT, catches many mistakes.
Statistics: depth on the basics
Statistics and probability questions make up about 3.7k of the analyst questions in our data, and A/B testing adds a few hundred more. Most of them test whether you can use basic ideas correctly.
Make sure you can explain these in plain words:
Mean versus median, and when an outlier makes the mean misleading
What a p-value tells you and what it does not
How an A/B test is set up, including the control group, sample size and test length
Common A/B test problems, such as stopping early or checking too many metrics
Correlation versus causation, with one real example you can describe
A useful test for yourself: try explaining an A/B test to a friend who has never studied statistics. If you can do it in two minutes without jargon, you are ready for most analyst rounds.
Business and product case questions
Metrics questions are the third largest category in our analyst data, with about 5k reports, and product sense adds about 2.3k more. These are the “how would you measure this?” or “why did this number change?” questions.
A typical prompt sounds like this: “Weekly orders in our app dropped 8% last week. How would you look into it?”
I like a five-step structure for these:
Clarify. Which orders, which platform, and compared with what baseline?
Rule out data issues. Was there a tracking change, an outage or a holiday?
Segment. Break the drop down by region, device, channel and new versus returning users.
Form a hypothesis. Say what you think happened and what data would confirm it.
Recommend. Suggest a next step, even if it is simply a deeper analysis.
You do not need years of industry experience here, just structure and curiosity. A simple way to practice is to pick an app you use every day, write down its three most important metrics, and explain why each one matters. Then imagine one of them dropped and walk through the five steps.
Communication and behavioral questions
This is the part candidates most often skip, and it is the biggest category in our data. Several of the most common analyst questions we see are about communication, such as presenting analysis to non-technical leaders, explaining a technical concept clearly, and prioritizing competing data requests.
Prepare five or six short stories from your own experience. Class projects, internships, research work, volunteer roles and part-time jobs all count. Good themes to cover are:
A time your analysis changed a decision
A time you worked with messy or incomplete data
A time you explained something technical to a non-technical person
A time you had to choose between two urgent requests
A time you made a mistake and fixed it
Use the STAR format (situation, task, action, result) and keep each answer under two minutes. Put a number on the result when you can, such as hours saved or a change in a metric.
During technical rounds, communication matters too. Think out loud, state your assumptions, and ask questions when a prompt is vague. Silence makes it hard to give you credit.
A Simple Four-Week Practice Plan
If you have about a month, here is a plan that fits around school or a full time job. Aim for 45 to 60 minutes a day.
Week 1: Foundations. Do SQL basics every day: filters, aggregates and joins. Review mean, median and distributions. Write down your five or six behavioral stories in rough form.
Week 2: Depth. Add window functions and date logic to your SQL practice. Study A/B testing and p-values until you can explain them simply. Practice one metrics case question a day out loud.
Week 3: Realistic practice. Do a timed SQL set of three or four questions twice this week. Practice two case questions a day and tighten your behavioral stories to under two minutes each. Look up real questions for the companies you are targeting. I built the Dataford data analyst interview guide partly for this step, so candidates can see which topics and questions come up most often.
Week 4: Mock interviews and rest. Do at least two full mock interviews with a friend, mentor or your career center. Review your weakest area, and stop adding new topics in the last two days.
If you only have one or two weeks, keep the same order and shorten each stage. SQL and behavioral stories should always come first, since they appear in almost every process.
Final thoughts
Data analyst interviews are very learnable. The candidates who get offers are usually the ones who practiced SQL until it felt routine, can bring structure to a vague business question, and can explain their thinking to anyone in the room. Start early, practice out loud, and treat each interview as practice for the next one.
A few days ago, I wanted to add a simple feature to my WordPress website: click an article image and see it enlarged.
Nothing complicated, right?
Normally, my first instinct would be to search for a plugin. Find one that supports my WordPress version, check whether it works with my theme, look at the reviews, install it, configure it, and hope it doesn’t introduce another problem.
And that’s exactly what I did.
I searched for different solutions and tried several plugins. Some appeared to be designed for specific page builders, such as Elementor. Others raised questions about compatibility with Gutenberg, my theme, or the WordPress version I was using.
I even installed two more plugins that morning: MetaSlider and MetaSlider Lightbox. According to an article I found, they should work together to provide the functionality I needed.
Unfortunately, that didn’t work as expected either.
All I wanted was for readers to click an image and see a larger version without leaving the article. I didn’t need slideshows, complicated galleries, or dozens of settings.
That experience later informed another practical experiment: building a lightweight WordPress plugin for social publishing rather than installing a larger system. And after spending so much time on such a small feature, I started wondering: Do we really need another plugin for every little thing we want to add to our websites?
What if I ask AI to build it?
After trying different options without getting the result I wanted, I decided to approach the problem differently.
I opened Claude, explained what I wanted to achieve, and asked whether it could help.
To my surprise, the very first response included JavaScript code and an explanation of how to use it.
Seriously? After all that searching and experimenting with plugins, I suddenly had a possible solution in front of me.
But there was another question.
These days, we often see discussions about AI-generated code. Some people say it’s unreliable, messy, insecure, or full of bugs. Others claim AI can build almost anything.
I wasn’t interested in proving either side right. I just wanted my little feature to work without creating new problems for my website.
So I decided to ask another AI for a second opinion.
I copied the code into ChatGPT and asked it to review the proposed solution.
Instead of simply confirming that everything looked fine, we discussed how the feature should behave on different devices, what might go wrong, and whether anything needed to be improved.
After a few adjustments, I had a revised version ready to test.
I added it to WordPress using WPCode, a plugin I already had installed and had found useful for many other small website customizations.
Yes, I know. I was trying to avoid plugins while using a plugin! 😂
But there was an important difference: I wasn’t installing another dedicated plugin just to enlarge images. WPCode was already part of my website, and I could use it to add a small piece of custom functionality.
And it actually worked!
We tested the solution, made a few adjustments, and eventually got exactly the result I had imagined.
Now, when someone clicks an eligible image in one of my articles, it opens in a larger view over a darkened background. The reader can examine the image and close it without leaving the page.
Want to see the result? Click the image above to enlarge it. You’ll see the lightbox we created with AI assistance in action—no extra image needed.
Was everything perfect from the first attempt? Of course not.
At one point, the feature worked on one article but not another. We investigated with Chrome DevTools and eventually found that clearing the LiteSpeed cache resolved the issue.
I’m not going to explain every technical detail here, because that’s not the point of this story.
The interesting part is that I didn’t have to understand every line of JavaScript to participate in the process.
I knew what I wanted. I could explain the expected behavior, test the result, describe what wasn’t working, and ask AI to help investigate.
And together, we got there.
That was satisfying.
But the story wasn’t quite finished.
The unexpected discovery: WordPress could already do something similar!
Just when I thought everything was done, we accidentally discovered something rather funny.
WordPress already had a built-in image enlargement feature called “Expand on click.”
Yes. After all those plugin searches, installations, experiments, and AI conversations! 😂
So how did we miss it?
It turned out that the image I was working with already had a link assigned to it. In the editor menu we were using, the enlargement option wasn’t visible while that link remained.
Once we removed the existing image link, the Expand on click option appeared. You can read more about image options in the WordPress Image block documentation.
We enabled it and compared the result with our custom solution.
WordPress’s built-in viewer enlarged the image against a light background that covered the article. Our custom version opened the image over a darkened, semi-transparent background, leaving the page visible underneath.
Both did the basic job, but they looked and felt different.
Could someone with WordPress development experience customize the built-in viewer using CSS, and perhaps a little JavaScript, to achieve something similar? Most likely.
But our solution was already working, and I preferred how it looked.
So I decided to keep it.
And no, I don’t regret the time we spent building it.
Without that experience, I wouldn’t have learned nearly as much about what AI could help me accomplish.
Does that mean WordPress plugins are unnecessary?
Not at all.
Plugins are incredibly useful, and many provide functionality that would be difficult or impractical to recreate with a small piece of custom code.
A dedicated lightbox plugin, for example, might offer image galleries, navigation between pictures, zoom controls, animations, and many other features.
For someone who needs those capabilities, installing a well-maintained plugin could be the right decision.
WordPress itself also includes more functionality than we sometimes realize. As my experience demonstrated, finding a built-in option isn’t always as straightforward as it sounds.
And then there’s a third possibility: creating a small, tailored feature with AI assistance.
None of these approaches is automatically better than the others.
What matters is understanding what you’re trying to achieve and choosing a solution that makes sense for your website.
The bigger lesson: AI gives us another option
Looking back, the most interesting part of this experience wasn’t the image lightbox itself.
It was realizing that something I previously would have approached only by searching for existing software could also be created with AI assistance.
And this isn’t limited to enlarging images.
Maybe you want a custom table that behaves differently from the standard WordPress block. Maybe you’ve imagined a small interactive element, a special layout, or a feature that none of the plugins you’ve found handles quite the way you want.
Until recently, many website owners would have faced a familiar choice: find an existing tool, hire a developer, or give up on the idea.
Now there’s another possibility.
You can explain what you’re imagining to an AI assistant and explore whether it can help you build it.
That doesn’t mean AI-generated code is always correct or safe. Testing still matters, and complex or security-sensitive functionality may require an experienced developer.
But for smaller, well-defined ideas, the possibilities are genuinely exciting.
There’s something else I learned during this experiment, too.
Working with AI isn’t simply about asking a question and copying the answer.
The way we explain our ideas, describe the expected result, provide context, and communicate what isn’t working can make a big difference.
There’s a name for this: prompt engineering.
It’s a subject I plan to explore in another article, because I believe learning how to communicate effectively with AI is becoming an increasingly useful skill—not just for programmers, but for anyone who wants to turn ideas into practical results.
And perhaps that’s the most important thing I’d like you to take away from this experience.
The next time you’re searching for a plugin or struggling to find a tool that does exactly what you need, consider another possibility.
What if you could create that little feature yourself, with some help from AI?
Sometimes the solution is already there. You just need to find it, and perhaps customize it.
Other times, AI can help you build something closer to what you imagined.
Either way, the ability to experiment and create is becoming accessible to more people.
And I think that’s one of the most interesting things about the future of technology.
How many passwords do you have? Five? Twenty? Fifty?
There’s your email, banking, shopping, social media, streaming, gaming, and perhaps a few accounts you haven’t visited in years. Now imagine being told that every one needs a different, long password.
Excellent advice. There’s just one small problem: we’re humans, not password databases.
Fortunately, there are several ways to manage passwords. Some people trust their browsers, others prefer dedicated apps, and some still swear by a pen and notebook. Which one makes sense?
How Did We End Up With So Many Passwords?
Almost every online service now wants an account. Reusing one password everywhere sounds convenient, but if that password is exposed through one service, other accounts using it may also be at risk. Unique passwords help contain that problem. Learning to manage accounts securely is part of everyday digital literacy, alongside the other digital skills teenagers can develop before university.
And yet, expecting anyone to memorize dozens of them is hardly realistic.
What Makes a Strong Password Today?
For years, the familiar advice was to combine uppercase letters, lowercase letters, numbers, and symbols, then change the password regularly. But NIST’s current Digital Identity Guidelines emphasize length and checking against commonly used or compromised passwords, rather than mandatory character mixtures or routine changes.
Under those guidelines, a password used as the only authentication factor must be at least 15 characters long. This is a requirement for systems following that standard, not a claim that every website already enforces it.
A long, unpredictable passphrase may be easier to remember than a short password full of punctuation. If a password manager generates a random password, you generally don’t need to remember it yourself.
Why Passwords Sometimes Stop Being Private
A data breach or deceptive login page can expose even a strong password. A service may suffer a data breach; a convincing fake login page may trick someone into entering credentials; malicious software may capture sensitive information. And when people reuse the same password, one incident can affect several accounts.
There’s no need to imagine a mysterious villain waiting behind every website. The practical lesson is simpler: make passwords unique and have a manageable way to store them. Passwords are only one part of online privacy; other tools, such as Tor and onion routing, address different privacy concerns.
Option 1: Let Your Browser Remember
Chrome, Edge, Firefox, Safari and other modern browsers can save passwords, generate new ones, and fill them in when you sign in. Depending on your settings, they may also synchronize credentials between your devices.
For many people, a browser’s built-in manager is a perfectly reasonable starting point. The UK National Cyber Security Centre (NCSC) recognizes browser-based password management as a practical option.
But device security still matters. Someone using your unlocked computer may access accounts you’ve already signed in to, even without knowing your passwords. And you should avoid saving credentials in a browser on a public or shared computer.
Bottom line: Very convenient, particularly if you mostly use your own devices and one browser ecosystem.
Option 2: Cloud Password Managers
Dedicated services such as Bitwarden and 1Password keep credentials in an encrypted vault and can synchronize them across supported browsers and devices. They can generate passwords and fill login forms, reducing the temptation to reuse credentials.
Of course, storing an encrypted vault through an online provider raises fair questions about trust, security, access and recovery. Encryption is important, but no software or provider is immune to every failure.
Bottom line: Convenient for people who regularly switch devices, provided they understand how the vault is protected and recovered.
Option 3: Offline Password Managers
What if you prefer to control where the database is stored? KeePassXC keeps passwords in an encrypted database file that you manage yourself.
Does that mean opening a file and copying your email password by hand every morning? Fortunately, no. KeePassXC offers browser integration for supported browsers, so it can fill credentials without repeated manual copying.
The trade-off is responsibility: you need reliable backups and, if you use multiple devices, a method for accessing the database on each one. Keeping a vault locally doesn’t guarantee safety if malicious software compromises the computer.
Bottom line: Greater control over storage, with more responsibility for backups and synchronization.
Option 4: The Notebook — Still in Business
And now, the original password manager: a notebook and a pen.
No subscription, no software updates, no synchronization conflicts. Just paper. It sounds old-fashioned, but the NCSC has acknowledged that writing passwords in a dedicated book can be reasonable when it is kept physically secure.
Nobody can access a paper notebook remotely over the internet. It can, however, be lost, stolen, photographed or damaged. And manually typing a long password from page 17 of a notebook is not everyone’s idea of a relaxing evening.
Bottom line: A workable option for some people, provided physical security and convenience are considered.
Do We Really Enter Passwords Every Day?
Usually not. Many websites and apps keep us signed in using authenticated sessions. That is why you can open your email without typing the password every morning.
But this also means someone using your unlocked device might access an already signed-in account without needing the password at all. A good screen lock matters regardless of where you store passwords.
Four Approaches, Different Priorities
Approach
Main advantage
What to consider
Browser manager
Easy and built in
Device and browser-account security
Cloud manager
Convenient across devices
Provider trust, vault protection and recovery
Offline manager
Control over database storage
Backups and synchronization
Paper notebook
No software dependency
Physical security and manual entry
These are general trade-offs, not security ratings. If you use one laptop, a browser manager may be enough. Switching between several browsers and a smartphone? A dedicated vault might be more convenient. Others may prefer local storage or paper.
One practical rule matters more than the brand of manager: avoid keeping several competing, outdated copies of the same credentials. When a password changes, make sure the version you rely on gets updated.
Can a Password Manager Become a Problem Itself?
Yes. A password manager collects valuable credentials in one place. If someone opens your unlocked vault, the consequences can be serious. Losing access to the vault without a recovery method can also be painful.
But reusing weak passwords everywhere carries its own risks. Password managers are useful because they make good habits more practical, not because they magically eliminate every security problem. Both the NCSC and CISA offer guidance on using password managers.
What If a Password Has Already Been Exposed?
Have I Been Pwned lets you check whether an email address appears in its database of known breaches. Its separate password-checking service can help identify previously exposed passwords.
A conceptual view of data breach lookups and password security checks in action.
A match doesn’t automatically mean someone currently controls your account, and no match doesn’t guarantee complete safety. But if a breach exposes a password, change it on every account where you used it.
What About Signing In With Google?
Sometimes a website doesn’t ask you to create a separate password at all. You simply select Continue with Google.
In that case, the website typically relies on Google to authenticate you rather than receiving your Google password. If you use several Google accounts, it can still be helpful to record which one you used for each website. Otherwise, six months later, signing in can become a guessing game of a different kind.
And What About Passkeys?
Some services now let you sign in with passkeys, device PINs, fingerprints or other authentication methods. These can reduce dependence on traditional passwords, but they raise new practical questions: What happens when your trusted device is at home? What if you lose your phone?
We’ll explore those questions in our next article on two-factor authentication, passkeys and safer logins.
Conclusion: A System You Can Actually Live With
Password security shouldn’t feel like a second job.
Browser saving, cloud managers, offline encrypted databases and paper notebooks all offer ways to manage an increasingly complicated digital life. Each comes with trade-offs.
The goal isn’t to win a competition for the most sophisticated setup. It’s to use unique credentials, protect the places where they’re stored, and make sure you can still access your accounts when something goes wrong.
The best password system is one you can reliably use.
So, which camp are you in: Team Browser, Team Cloud, Team Offline—or Team Notebook? 😊
What happens when you open a normal website in Tor Browser? We examined a real Tor circuit while visiting TechEduCareer and compared our observations with the Tor Project’s documentation.
How does Tor work, and what happens when you visit a website through Tor Browser? Most people open a browser without thinking about the route their internet connection takes. Tor changes that route by passing traffic through multiple relays, helping protect your IP address and online privacy.
What is Tor?
Tor is short for The Onion Router. Its network is made up of independently operated servers called relays. Tor Browser sends web connections through this network and includes browser-level privacy protections. You can use it to visit ordinary public websites, not just sites ending in .onion.
For a typical visit to a regular website, Tor builds a circuit with three relays: an entry guard, a middle relay, and an exit relay. The exit relay makes the final connection to the destination. The website generally sees the exit relay’s IP address instead of your original one. Source: Tor Project — About Tor Browser.
How Does Tor Work? Understanding Onion Routing
Figure 1. How Tor’s onion routing works: three relays help protect your IP address by separating your identity from the destination website.
Imagine sending a message wrapped in several envelopes. Each intermediary can open only its own envelope to learn where to forward the remaining package. Tor uses layered cryptography to achieve a related effect: your browser establishes keys with relays, and each relay processes only the layer relevant to its hop.
Typical route to an ordinary website:
Your Tor Browser → Entry guard → Middle relay → Exit relay → Website
The design limits what any individual relay learns:
Entry guard: can see your connection’s source IP and the next relay, but not the final ordinary website destination from the Tor circuit alone.
Middle relay: knows its neighboring relays, not your original IP and the destination together.
Exit relay: connects to the destination and can see where traffic is going, but ordinarily does not know your original IP.
Website: sees a connection from the exit relay. It may still identify you if you log in or share personal details.
This is a simplified explanation. Tor’s actual circuit construction involves cryptographic handshakes, directory information, and additional safeguards. Source: Tor Project — Cryptographic keys.
Our Tor Browser Experiment: Testing a Real Tor Circuit
Figure 2. Our Tor Browser experiment: a connection to TechEduCareer.com through Switzerland (entry guard), Finland (middle relay), and the Netherlands (exit relay). Relay locations may change between sessions.
To understand how Tor works in practice, we examined a real Tor Browser circuit. We installed Tor Browser and used it to open TechEduCareer.com, an ordinary website on the public web. Tor Browser’s circuit display showed one route passing through three countries:
Entry guard: Switzerland
Middle relay: Finland
Exit relay: Netherlands
In that session, the displayed exit IP was 185.132.53.121. An IP-information lookup identified the address as Tor-related. This was consistent with the circuit display: our visit to an ordinary website used a Tor exit relay.
What the test demonstrated: the browser displayed a three-relay path and an exit address that was different from the user’s direct internet connection. What it did not prove: that every Tor session uses those countries, that an IP-geolocation database is always accurate, or that a person using Tor cannot be identified by other means.
Why does the website see another IP address?
On a normal direct connection, a website commonly sees the IP address used by your network or its gateway. With Tor, the exit relay contacts the ordinary website on your behalf. The website therefore sees the exit relay’s address.
This also explains why a website may think a Tor visitor is in a different country. IP geolocation describes an address, not necessarily the physical location of the person using it. Security systems may recognize public Tor exit IP addresses and ask for a CAPTCHA or block a request. Recognizing Tor use is not the same as learning the user’s real IP.
Does Tor choose new relays every time?
Not exactly. Tor deliberately reuses a relatively stable entry guard over time. Constantly choosing new entry relays would increase the chance of encountering an adversarial guard. Middle and exit relays can change as circuits are created, including for different sites. The Tor Project explains why guards remain stable in its entry-guard guide.
New Circuit versus New Identity
Tor Browser has two options that sound similar but do different jobs:
New Tor Circuit for This Site reloads the site over a new circuit. It does not clear cookies or unlink your current session from earlier activity.
New Identity closes tabs and windows, clears private browsing data, and uses new circuits for subsequent activity.
These tools solve different problems. A VPN generally routes traffic through infrastructure operated by a provider; that provider may be in a position to observe or associate some connection information. Tor distributes a typical web circuit among separate relays. Private or incognito mode, meanwhile, primarily changes how your browser stores local session data—it does not hide your IP address from websites.
Question
Tor Browser
Typical VPN
Private/Incognito mode
Does a website usually see your original public IP?
No, it sees the Tor exit
No, it sees the VPN endpoint
Yes
Uses several independently operated relays?
Yes, for typical exit circuits
Usually no
No
Protects other apps automatically?
No
Often, if system-wide
No
Primary purpose
Network privacy and anonymity protections
Encrypted tunnel to a provider
Reduce local browsing traces
Comparison of how Tor Browser, a typical VPN, and private/incognito mode protect your connection.
Why might Tor feel slower?
A Tor connection takes extra hops and passes through relays with varying capacity and network load. That adds latency compared with many direct connections. Performance also depends on the destination website, the exit relay, and the current network. The privacy trade-off is real: Tor is not designed to be the fastest possible route.
What Tor cannot protect you from
Tor is useful, but it is not a magic anonymity switch:
Account identification: logging in to an account tells the service who you are, regardless of the visible exit IP.
Information you disclose: names, messages, files and other clues can reveal identity.
Unprotected applications: opening Tor Browser does not route your other browsers, games or applications through Tor.
Unsafe downloads: documents opened outside Tor Browser may contact external resources.
Traffic correlation and compromised devices: sophisticated observers or malware can undermine privacy even when the network design works as intended.
HTTPS still matters for ordinary websites. Tor encrypts and routes traffic inside its network, but an exit relay is not a substitute for HTTPS encryption between the browser and the destination service. With HTTPS, the exit relay cannot simply read the protected page contents. Source: Tor Project — Tor encryption.
Is Tor only for the dark web?
No. Our experiment used Tor Browser to visit an ordinary public website. Tor can help people reduce tracking, research sensitive topics and access information where censorship is a concern. Some websites block Tor exits, and laws and restrictions vary by location. Tor itself is a privacy technology, not a category of illegal content.
For most people, Tor Browser is worth knowing about, but it does not need to replace Chrome, Firefox, Edge, or another everyday browser. A regular, updated browser with sensible privacy settings is often more convenient for routine tasks such as streaming, shopping, and banking.
Tor Browser is particularly useful when you want to reduce IP-based tracking, research a sensitive topic, or reach information in an environment where access is restricted. However, Tor connections can be slower, some websites block known exit relays, and signing into a personal account still identifies you to that service.
Practical takeaway: use Tor when its additional network privacy protections serve a purpose, rather than assuming it makes every online activity anonymous.
Frequently asked questions
Can I open Google or other regular websites with Tor Browser?
Yes, although some services may require additional verification or block known exit relays.
Can my internet provider tell I use Tor?
On a direct Tor connection, the provider may recognize a connection to the Tor network. It generally cannot read the ordinary website destinations you access through Tor. Bridges can help where direct Tor access is blocked.
Does Tor change my IP for every page?
No. Circuits can be reused, and the entry guard is intentionally stable. Different sites can use different circuits.
Does Tor protect Chrome or other apps?
No. Only traffic configured to use Tor benefits from its routing; Tor Browser does not automatically protect unrelated applications.
Does Tor guarantee anonymity?
No. It makes some kinds of network tracing harder, but account logins, user behavior, malware and advanced attacks can still compromise privacy.
What comes next: onion websites
There is one major distinction we have intentionally left for Part 2. Ordinary websites are reached through Tor exit relays. Onion services ending in .onion use a different connection design that does not require an ordinary internet exit relay. We also tested an onion search service and saw that its circuit display differed from the one used for TechEduCareer.com.
In the next article, we will explain how onion websites work, what their unusual addresses mean, how they are discovered, and what our own Tor Browser experiments showed.
Imagine receiving an email that appears to come from your bank. It has the right logo, familiar colors, and an urgent warning about your account. You click a link, enter your password, and later discover that the message was fake.
Was the hacker hiding on the mysterious Dark Web? Perhaps—but the attack itself may have happened entirely on the ordinary internet you use every day.
That is one of the biggest misunderstandings about the Dark Web: cybercrime does not belong exclusively to a hidden digital world. To understand where hackers operate, we first need to distinguish the Surface Web, Deep Web, and Dark Web.
The internet is bigger than what Google shows you
Search engines discover and index many public pages, but they do not display every piece of web content. Your email inbox, banking dashboard, and school portal are also accessed through the web, yet their private contents are not publicly searchable. Other services operate through specialized privacy networks such as Tor.
1. Surface Web: The part everyone can find
The Surface Web (or Open Web) consists of public web content that conventional search engines can discover and index: news articles, educational websites, public forums, online stores, and company websites.
Not being indexed does not automatically make a page part of the Dark Web. A public page that Google has not discovered can still be accessible in an ordinary browser.
2. Deep Web: The private part you already use
The Deep Web is web content not indexed by ordinary search engines. Much of it is entirely routine: private email, online banking, school portals, medical records behind logins, company intranets, subscription content, and private databases.
You usually do not need special network software to access it—just the correct account or permission. The Deep Web is not inherently suspicious; privacy and access controls are normal parts of the internet.
3. Dark Web: Services on specialized networks
The Dark Web refers to content accessible through specialized networks or configurations designed to provide additional privacy or anonymity. The best-known example is Tor. Some Tor-hosted sites use addresses ending in .onion, called onion services.
An onion service can conceal the network location of the server. That can protect journalists and confidential sources, but the same privacy properties can be misused for criminal activity. The technology alone does not tell you whether its use is legitimate.
Surface Web vs Deep Web vs Dark Web
Feature
Surface Web
Deep Web
Dark Web
Typical example
Public news article
Private email inbox
Tor onion service
Indexed by ordinary search engines?
Often
Generally not
Generally not
Special network software required?
No
Usually no
Often yes
Automatically illegal?
No
No
No
Can criminals use it?
Yes
Yes
Yes
Main distinction
Public discoverability
Not publicly indexed
Specialized privacy network
The categories describe access and discoverability—not whether the people using them are good or bad.
So where do hackers actually operate?
Across all three. Many attacks on ordinary people do not require the Dark Web at all.
Example 1: A phishing attack on the ordinary web
A criminal creates a fake login page resembling a familiar service, then sends a convincing email or social media message. The page may be hosted on conventional web infrastructure with an ordinary domain name. The victim never visits the Dark Web.
Example 2: Unauthorized access to a private account
An attacker who compromises an employee account may reach confidential documents or internal systems. Those resources may be part of ordinary business services behind a login—not Dark Web sites. The problem is unauthorized access.
Example 3: Stolen data traded in criminal networks
After a breach, stolen credentials and access to compromised systems may be advertised on illicit marketplaces or forums, including some onion services. But criminals also use ordinary websites, messaging platforms, and other online infrastructure. Europol’s 2025 assessment describes stolen data as a commodity that enables further fraud, extortion, and cyberattacks.
Are all hackers criminals?
No. Ethical hackers test systems with authorization to find weaknesses and improve defenses. Security researchers investigate vulnerabilities and malicious activity. Malicious hackers break into systems without authorization, steal data, or cause harm. Their technical knowledge may overlap; permission, intent, and conduct make the difference.
Why would anyone use the Dark Web legitimately?
Privacy is not automatically suspicious. Journalists and confidential sources may need communication methods that reduce the risk of exposing their identities. SecureDrop, an open-source system used by news organizations, relies on Tor to support confidential submissions and communication. Other legitimate uses include resisting censorship, security research, and protecting sensitive conversations.
How does Tor actually work?
Tor, short for The Onion Router, ordinarily routes Tor Browser traffic to a conventional website through multiple relays. A simplified route is your device → entry relay → middle relay → exit relay → website. The destination generally sees the exit relay’s IP address instead of yours; no single relay ordinarily knows both your identity and your destination. Onion services use a different arrangement that keeps connections within Tor and can hide the server’s location. Read more in the Tor Project’s official documentation.
Does Tor make someone completely anonymous?
No technology guarantees anonymity in every situation. Signing into an account under your real name can identify you even if your IP address is concealed. Tor Browser does not automatically route every other application on your computer through Tor. Sophisticated attacks, including traffic correlation, can also threaten anonymity under certain conditions.
It helps to separate four goals: hiding a network address, encrypting communication contents, preventing tracking, and keeping a real-world identity private. These are related, but not identical.
Can Dark Web websites use cookies?
Yes. Onion websites can set browser cookies just like ordinary websites. A cookie can let a site recognize your browser while you navigate between pages, even if the site cannot see your real IP address. Tor Browser is designed to isolate website data and normally clear cookies when the browser session ends, but that does not prevent every form of tracking or identification.
For example, an onion site could assign a visitor a session cookie, recognize that visitor on the next page, and lose that particular cookie when the visitor fully closes and restarts Tor Browser. Account logins, browser fingerprinting, and other clues can still matter. We will explore these distinctions in a dedicated article about cookies and tracking.
Is visiting the Dark Web illegal?
In many jurisdictions, using Tor or accessing lawful onion services is not inherently illegal. Laws vary by country, however, and criminal conduct remains criminal regardless of the network used. Buying illegal goods, stealing data, or accessing systems without authorization does not become lawful because Tor is involved.
Is Web3 another part of the Dark Web?
No. Despite its name, Web3 is not another layer of the internet alongside the Surface Web, Deep Web, or Dark Web. Web3 generally refers to blockchain-based applications, decentralized systems, and digital ownership. A Web3 application can operate on the ordinary web, and some services may also use Tor. These terms describe different aspects of how online technologies work.
Five Dark Web myths worth questioning
Myth 1: The Deep Web and Dark Web are the same thing
False. Your private email inbox is Deep Web content, but it is not a Tor onion service.
Myth 2: Everything on the Dark Web is illegal
False. Privacy-preserving services can support journalism, research, and lawful communication.
Myth 3: Hackers only operate on the Dark Web
False. Phishing, account theft, malware, and many other attacks use ordinary internet infrastructure.
Myth 4: Tor makes you impossible to identify
False. Tor provides meaningful privacy protections, not a universal guarantee against identification.
Myth 5: The Dark Web has mysterious numbered levels
Viral stories about secret, increasingly dangerous levels are not a recognized technical model of how the web works.
What should ordinary internet users actually worry about?
For most people, the most effective protections are less dramatic than exploring hidden websites: use unique passwords, enable multifactor authentication or passkeys where available, keep software updated, and be skeptical of urgent messages and unexpected login requests. Understanding online safety is also a core digital skill, as we explain in our guide to digital skills students should learn before university.
A reputable password manager can make unique passwords practical across hundreds of accounts, although password vaults also introduce risks if a provider is breached or a device is compromised. That trade-off deserves a separate article—not a blanket claim that any storage method is perfectly safe.
A question worth exploring
Suppose you open a website right now. Who can see your connection: your internet provider, the website, your employer, or a VPN company? The answer depends on encryption, network configuration, and privacy tools. That’s where our next investigation begins: What Is Tor, and How Does It Hide Your IP Address?
Frequently asked questions
Is the Dark Web bigger than the Surface Web?
There is no reliable universal measurement establishing the Dark Web’s exact share of all web content. Be skeptical of dramatic percentages that confuse the Deep Web with the Dark Web.
Can Google search the Dark Web?
Ordinary search engines generally do not index onion services in the same way as public websites, although information about onion services can appear on the public web.
Is the Deep Web dangerous?
Not inherently. Many everyday private accounts and databases are Deep Web content. Their security depends on how they are protected and used.
Can you access the Deep Web without Tor?
Yes. Email, banking, and school portals are usually accessed with ordinary browsers.
Do you need to visit the Dark Web to learn cybersecurity?
No. You can learn about Tor, privacy, cybercrime investigations, and digital security from legitimate public documentation and educational research.
We use essential cookies to operate this website and optional cookies for analytics where enabled. Choose Accept All, Reject, or Preferences to manage your choices.
Websites store cookies to enhance functionality and personalise your experience. You can manage your preferences, but blocking some cookies may impact site performance and services.
Essential cookies enable basic functions and are necessary for the proper function of the website.
Name
Description
Duration
Cookie Preferences
This cookie is used to store the user's cookie consent preferences.