Laptop displaying VirtualBox, Kali Linux, and Docker with two web server containers, illustrating a beginner-friendly virtual development lab.

Your First Docker Adventure: Build a Web Lab with Kali Linux & VirtualBox

What if your laptop could become a tiny web-hosting laboratory—without turning your everyday computer into a science experiment? This VirtualBox Kali Linux Docker tutorial shows you how to build that lab, one small mission at a time.

Picture this: you open a browser, type an address, and a website appears. Nice. Then you open a second address, and another website appears. Both are running on your computer. Neither needed a traditional web-server installation. And when you’re finished, you can switch the whole laboratory off.

No expensive server. No mysterious data center. No wizard hat required. 🧙

That’s what we’re building today: a beginner-friendly development playground using VirtualBox, Kali Linux, and Docker. We’ll start with a virtual computer, install Docker inside it, and launch two independent Nginx web servers. We’ll even give one of them a personality.

Our promise: these aren’t imaginary commands copied from a manual. We worked through this experiment ourselves using a Kali Linux 2026.3 prebuilt VirtualBox machine. You’ll see what we tested, what each command does, and where the boundaries of our experiment are.

Meet the three characters in our little tech adventure

Before we press any buttons, meet the team. If you’re just starting your tech journey, our guide to essential digital skills for students explains why hands-on practice matters.

  • VirtualBox — the apartment building. It lets your computer host a separate virtual computer, with its own operating system and settings.
  • Kali Linux — our apartment. It’s the Linux operating system inside that virtual machine. We’re using Kali because we also want to explore cybersecurity tools in future lessons.
  • Docker — the clever room organizer. It runs applications in containers, so our web servers can have their own spaces without each needing an entire operating system.

That comparison isn’t perfect—containers share the Linux kernel of their Docker host, while a virtual machine runs a separate guest operating system—but it’s a useful mental picture. And no, Docker doesn’t require Kali: other supported Linux distributions work too.

Mission 0: Prepare your VirtualBox Kali Linux Docker lab

You’ll need a computer with virtualization support, internet access, free disk space, and enough memory to comfortably run a virtual machine. For our experiment, we configured Kali with 4 GB RAM, 2 virtual CPUs, and NAT networking. The prebuilt VM had an approximately 80 GB virtual disk. These are our settings, not a universal minimum.

Hardware compatibility: This walkthrough uses standard Intel/AMD x86_64 hardware. Apple Silicon Macs use ARM-based processors and require an ARM-compatible setup; don’t follow these VirtualBox and Kali VM steps unchanged.

Virtualization setting: If VirtualBox reports that hardware virtualization is unavailable, you may need to enable Intel VT-x or AMD-V (sometimes called SVM Mode) in your computer’s BIOS/UEFI settings. Many computers already have it enabled. The setting’s name and location vary by manufacturer, so consult your device’s official documentation before changing firmware settings.

Our downloads come from official sources. Use these direct links rather than relying on search ads or third-party download sites:

Download from the official sites and check the Kali archive’s published checksum for your exact version. It takes a little extra effort, but learning good download habits early is a superpower.

Mission 1: Build a computer inside your computer

First, install VirtualBox using Oracle’s installer from the official VirtualBox downloads page. Launch VirtualBox Manager when you’re done.

Next, download Kali’s prebuilt VirtualBox archive and extract the .7z file. In VirtualBox Manager, choose Add (or the option for adding an existing virtual machine), find the extracted .vbox file, and open it.

Review the VM settings. We used 4 GB RAM, 2 CPUs, and the default-style NAT network connection. Start the machine.
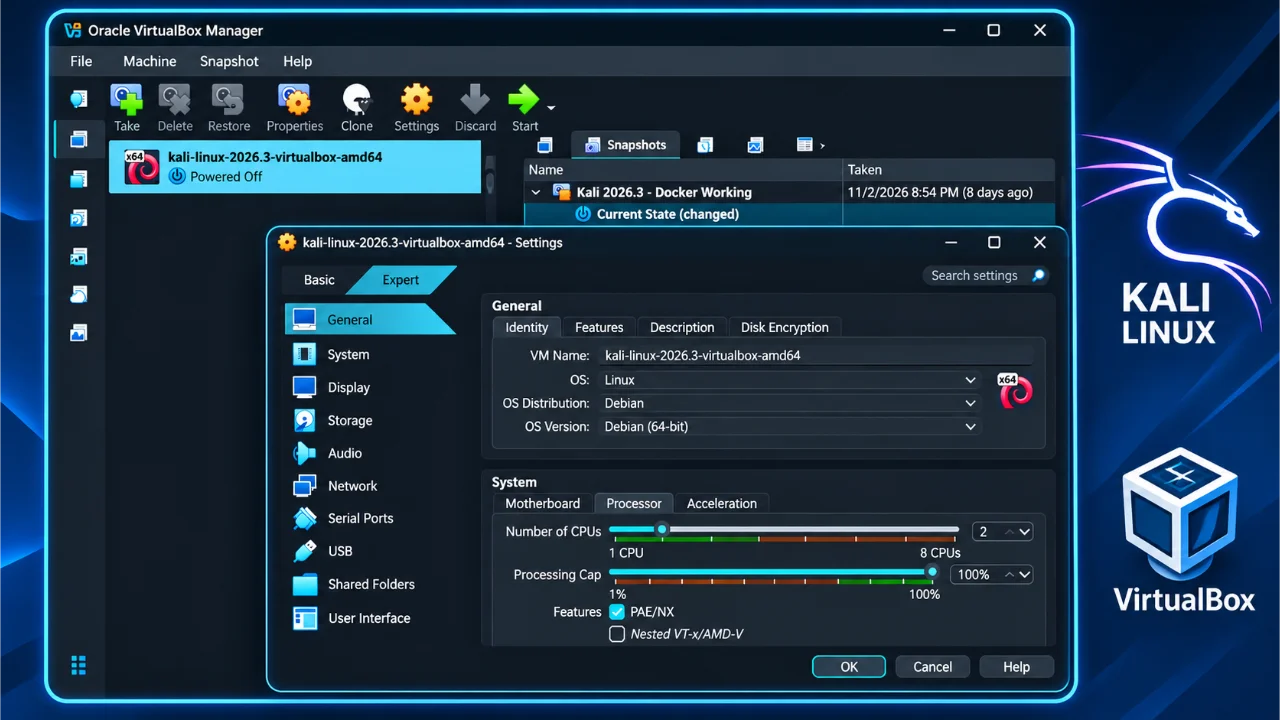
Oracle VirtualBox Manager showing a Kali Linux 2026.3 virtual machine configured with two virtual CPUs for a Docker development lab.
Our Kali Linux virtual machine configured in Oracle VirtualBox for the Docker experiment.

Plot twist: you now have a Linux computer running inside your regular computer. It has its own desktop, terminal, and browser. That’s virtualization in action.

Kali’s prebuilt virtual machine commonly ships with the documented default login kali / kali. Change that password before exposing the VM to other networks or using it for network-facing activities. NAT is convenient for this local lab, but it’s not a magical security shield.

Open Firefox inside Kali and visit a website. If it loads, your virtual laboratory has internet access. First mission complete.

Mission 2: Install Docker in Kali Linux

Open Kali’s terminal. It may look intimidating, but for now it’s simply a place where we give the computer precise instructions. Run these commands one at a time:

sudo apt update
sudo apt install -y docker.io
sudo systemctl enable --now docker

Translation from computer-speak: update the package list; install Docker Engine from Kali’s repositories; start Docker and enable its service for future boots.

Why docker.io? Because that’s the package name used for Docker Engine in Kali’s repository. We’re not accidentally installing the internet. 😄

Check that Docker is there:

sudo docker --version
sudo systemctl status docker

You should see Docker version information and a running service. If the status screen doesn’t return to the prompt, press q. For a simpler one-word service check, run sudo systemctl is-active docker (the result should be active), then use sudo docker ps to verify Docker responds. These are the checks shown in our annotated screenshot.
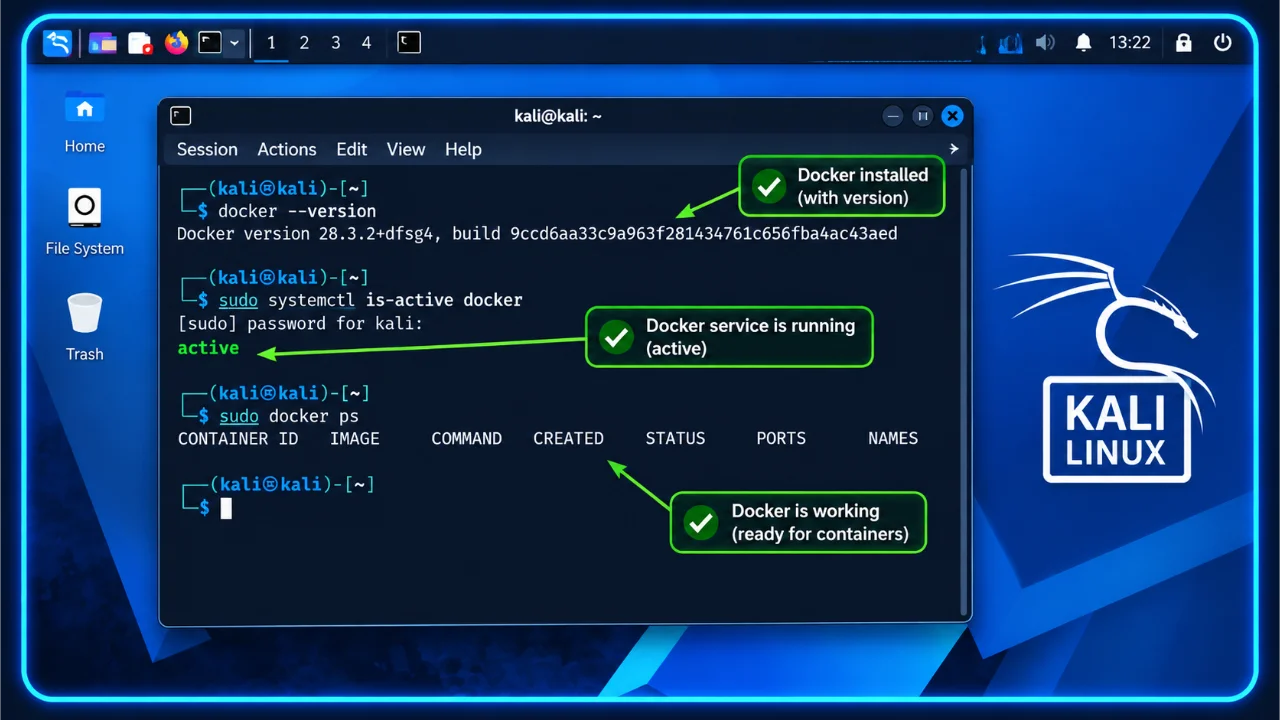
Kali Linux terminal verifying Docker installation, an active Docker service, and a working Docker container engine.
Checking the Docker version, confirming the service is active, and verifying that the Docker engine responds in Kali Linux.

We intentionally use sudo throughout. Giving a normal user unrestricted access to the Docker daemon through the docker group is effectively giving them root-level privileges, as Docker’s official Linux post-installation guide explains. It’s not something beginners need to do just to follow this tutorial.

Mission 3: Say hello to your first container

Time for a tiny victory. Type:

sudo docker run hello-world

Docker downloads the small test image if necessary, creates a container, runs it, prints a message, and exits.

Look for the words “Hello from Docker!”. If you see them, congratulations: you’ve run your first container.

Here’s an important distinction you’ll use again and again: an image is the reusable blueprint; a container is an instance created from it. Think cookie cutter versus cookie. Except these cookies can run software. Please don’t eat them.

Mission 4: Launch your first Docker web server on Kali Linux

Now we move from a friendly greeting to something you can actually see in a browser. Run:

sudo docker run -d --name my-first-webserver -p 127.0.0.1:8080:80 nginx:alpine

Let’s decode that:

  • run creates and starts a container.
  • -d runs it in the background.
  • --name my-first-webserver gives it a memorable name.
  • -p 127.0.0.1:8080:80 maps Kali’s local port 8080 to port 80 inside the container.
  • nginx:alpine is the lightweight Nginx image.

Open Firefox inside Kali and enter http://localhost:8080.

Ta-da! The familiar Welcome to nginx! page should appear. You’ve just launched a real web server from a container image. No separate Nginx installation on Kali required.
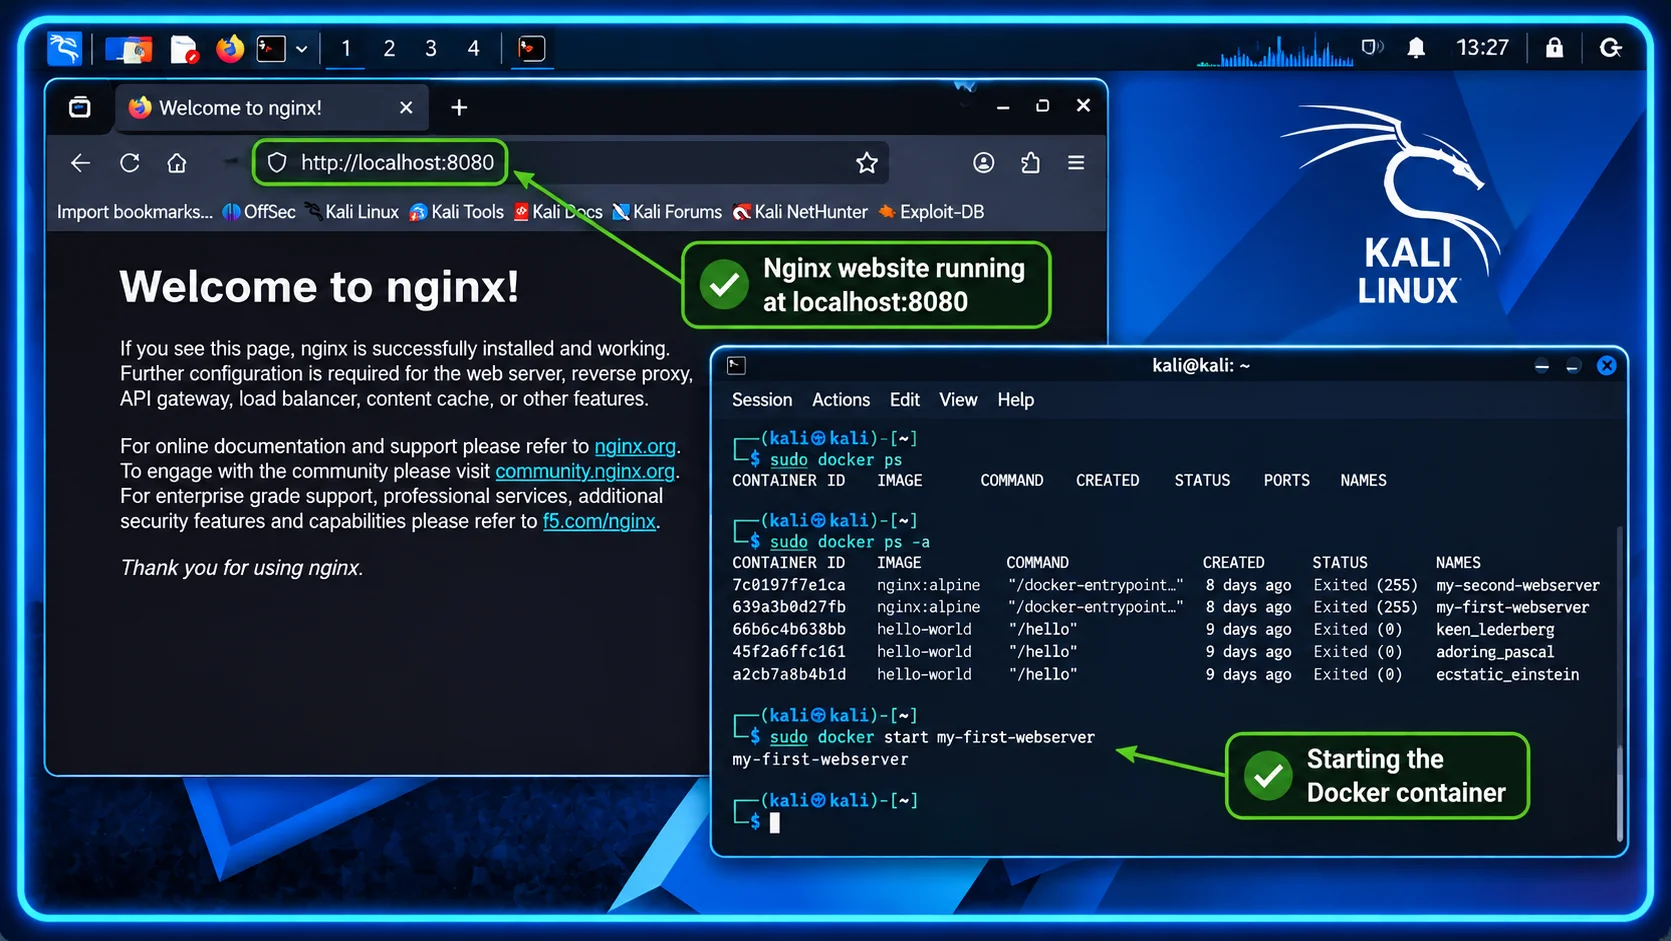
Kali Linux Firefox displaying the Nginx welcome page at localhost:8080, alongside a terminal showing the Docker command used to start the web server container.
Our first Nginx website at localhost:8080, running inside a Docker container on Kali Linux.

Small safety improvement: during our original experiment we used -p 8080:80. This article uses 127.0.0.1:8080:80 so the port is bound only to Kali’s loopback interface. Both approaches demonstrate port mapping, but the latter is a better default for a local beginner lab.

Curious what Docker is running? Ask it:

sudo docker ps

For both running and stopped containers, use:

sudo docker ps -a

Mission 5: The disappearing website trick

Let’s perform a tiny magic trick. Stop your web server:

sudo docker stop my-first-webserver

Refresh http://localhost:8080. The page should stop loading. Did we delete the website? Nope. We simply stopped the container.

Bring it back:

sudo docker start my-first-webserver

Refresh again. Your website returns.

Beginner discovery: docker start restarts an existing container. docker run creates a new container. That difference explains why repeatedly running hello-world leaves several stopped test containers behind.

Mission 6: Run two Docker web servers side by side

What happens if we use the same Nginx image to launch another server? Do we need another Kali machine? Another installation? Another afternoon of setup?

Nope. Just another container:

sudo docker run -d --name my-second-webserver -p 127.0.0.1:8081:80 nginx:alpine

Now open these two addresses in Kali Firefox:

  • http://localhost:8080 — server number one
  • http://localhost:8081 — server number two

Two web servers, one Kali VM, one reusable Nginx image. Each container is its own running instance. We use different host ports because two services can’t listen on the same host address and port at the same time.

At this point, our little virtual laboratory starts to feel like a real developer playground.

Mission 7: Give the second website its own personality

Both websites look identical. That’s a little boring. Let’s change only the second one.

Copy this command into Kali’s terminal:

echo '<h1>Hello from Docker Server 2!</h1><p>Created for TechEduCareer.</p>' | sudo docker exec -i my-second-webserver tee /usr/share/nginx/html/index.html

It sends a small HTML page into the second container and writes it to Nginx’s default website location.

Refresh http://localhost:8081. You should see our custom greeting. Then refresh http://localhost:8080. The first website is unchanged.

Wait—same image, different websites? Exactly! Each container has its own writable layer. Changing a file in one doesn’t automatically change the other.
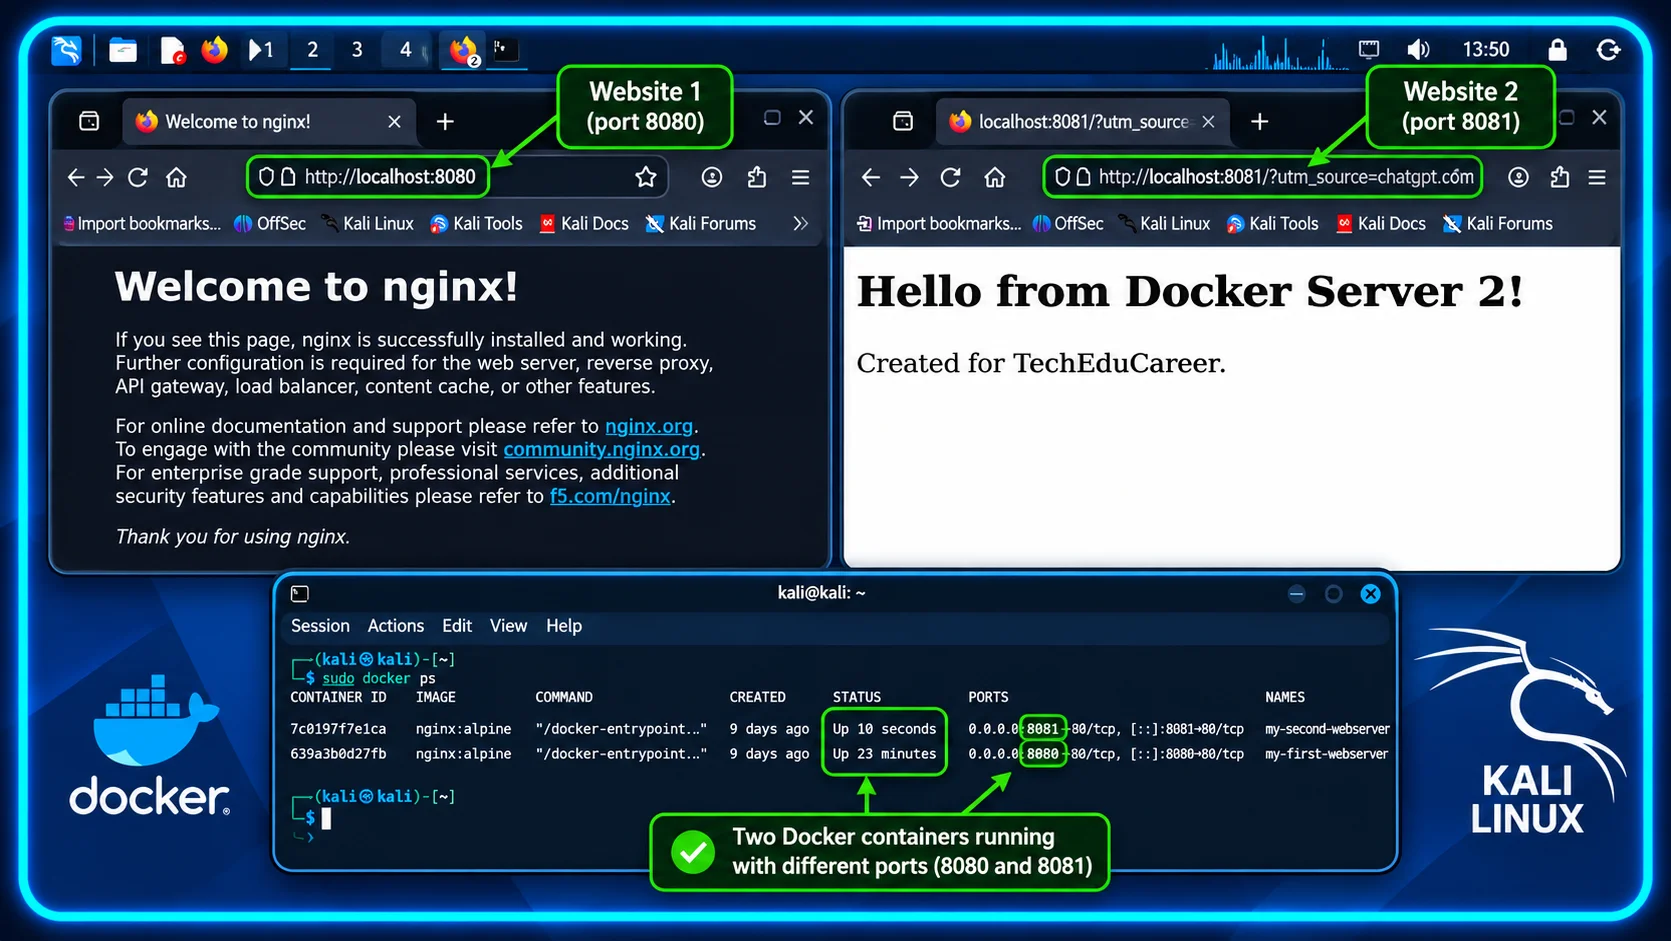
Two Docker Nginx web servers running side by side in Kali Linux at localhost:8080 and localhost:8081, with terminal output confirming both containers are active.
Two independent Docker websites: the default Nginx page on port 8080 and our customized TechEduCareer page on port 8081.

One catch, though: editing files inside a container is great for a demonstration, but not how we’d usually manage an important website. These changes can survive a stop/start, yet disappear if that container is removed and recreated. Persistent storage using bind mounts or volumes is our next lesson—not something we’re pretending to have tested already.

Mission 8: Stop, start, and clean up your containers

We’ve already stopped and restarted our first web server in Mission 5. Before closing the lab, let’s learn the difference between stopping a container and removing it.

See both containers, including any that are stopped:

sudo docker ps -a

To stop our second website without deleting it, run:

sudo docker stop my-second-webserver
sudo docker ps -a

The second container should show Exited, while the first remains Up. This is the state captured in our annotated screenshot below. When you want the second website back, run:

sudo docker start my-second-webserver
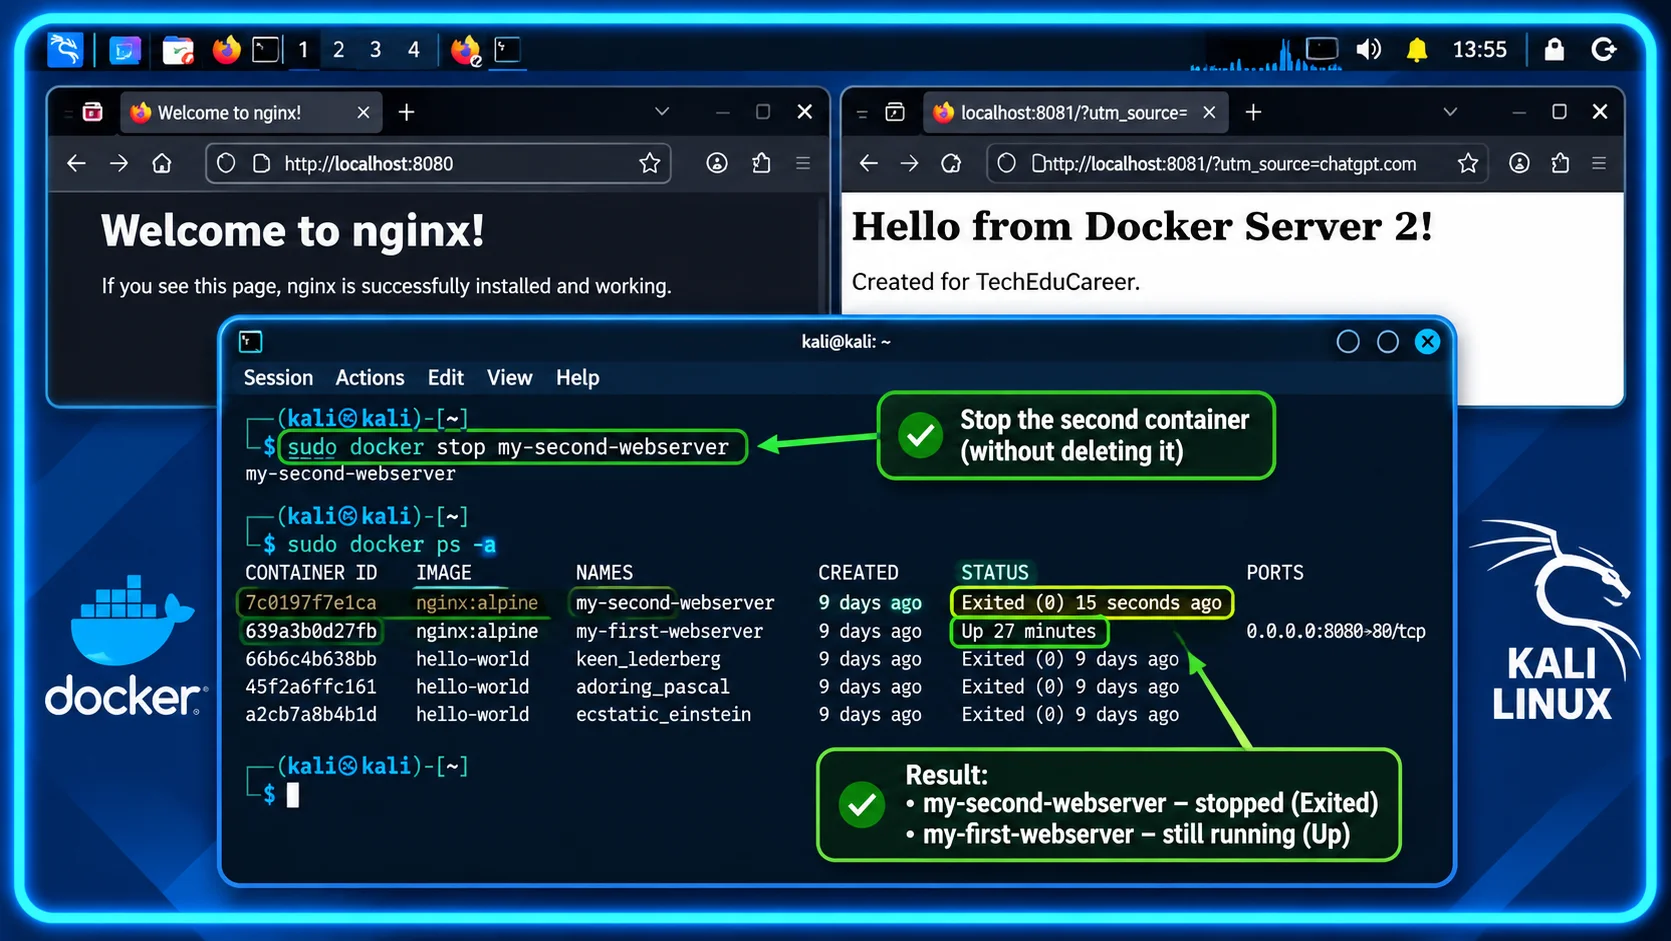
Annotated Kali Linux terminal showing docker stop and docker ps -a commands, with the second Nginx container Exited and the first still running.
After stopping the second container, Docker shows it as Exited while our first web server remains Up.

Optional cleanup — only if you’re finished with the customized website: To delete the second container rather than just stop it, first stop it, then remove it. Skip these commands if you want to keep your customized second website for later experiments.

sudo docker stop my-second-webserver
sudo docker rm my-second-webserver

Important: docker rm removes the container, not the downloaded nginx:alpine image. Our custom HTML was written inside that container, so removing it also discards that change. Only do this when you’re finished with the second website. You can create a fresh container later using the docker run command from Mission 6.

To shut down the Kali virtual machine cleanly, run this in Kali’s terminal:

sudo poweroff

This shuts down Kali and its running containers; it does not delete the VM or Docker images. Next time, start the VM in VirtualBox and use docker start for any existing containers you want running again.

Bonus mission: Create a save point before experimenting further

When you’re learning, being able to undo a messy experiment is wonderful. VirtualBox lets you take a snapshot of the VM.

In our experiment, after Docker was working, we shut down Kali:

sudo poweroff

Then, in VirtualBox Manager, we created a snapshot named Kali 2026.3 – Docker Working.

To do the same, power off Kali, select the VM, open Snapshots, and create a snapshot with a name you’ll recognize. Remember that a snapshot returns the VM to the state captured at that moment. If you took it before the Nginx missions, those later containers won’t be present after restoring it. Also, snapshots are not a substitute for a proper backup.

Your tiny Docker cheat sheet

Command Superpower
sudo docker run hello-world Run a test container
sudo docker ps See what’s running
sudo docker ps -a See all containers, including stopped ones
sudo docker images See downloaded images
sudo docker stop my-first-webserver Stop the first server
sudo docker start my-first-webserver Bring it back
sudo docker rm my-second-webserver Delete the stopped second container (and its internal changes)
sudo poweroff Shut down the Kali VM cleanly
sudo docker logs my-first-webserver Read its logs

Frequently asked questions

Is Docker a mini virtual machine?

Not quite. Our Kali VM has its own guest operating system. Docker containers share Kali’s Linux kernel while isolating applications. Both are useful, but they solve different problems.

Why Kali? Isn’t it for hackers?

Kali is well known for security testing, but it’s also a Linux environment where you can learn commands and run Docker. If you’re curious about the wider cybersecurity world, our beginner’s explanation of the surface, deep, and dark web explores some common misconceptions. We’re using harmless Nginx images here. Please don’t treat containers as a secure sandbox for running unknown malware.

Why can’t I open localhost:8080 on my main computer?

In this tutorial, localhost means Kali itself, because that’s where Docker runs and where we bound the ports. Reaching the service from your outer computer would require different networking choices, which we’re deliberately saving for another lesson.

What if I shut down Kali? Is everything gone?

No. Docker images, existing containers, and files on Kali’s virtual disk remain unless you remove them. The applications stop while Kali is off. When you start Kali again, you can restart the containers.

Could I build my own app in Docker later?

Absolutely. Today’s lesson uses ready-made images. Later we can create our own image, add persistent files, and learn how containers communicate. That’s where the playground gets really interesting.

Level complete: What did we actually build?

We started with an empty VirtualBox window and ended with two independent web servers running inside Docker on Kali Linux. Along the way, we learned what a virtual machine is, how images differ from containers, how ports connect a container to a browser, and why two containers can behave differently even when they started from the same image.

Best of all, our VirtualBox Kali Linux Docker lab keeps these experiments in a virtual machine rather than turning our everyday computer into a pile of half-finished installations. Remember that a virtual machine is not a guarantee of perfect isolation, so use trusted images and keep the lab updated.

Next adventure? We could make website files survive container replacement, explore Docker networking, or package a tiny application of our own. If building a game sounds more exciting than another web page, explore our beginner’s guide to game development. For now, enjoy the two websites. You’ve earned that victory screen.
Official references

Encrypted email comparison featuring Proton Mail, Tuta, and Atomic Mail on a laptop with a glowing security lock, illustrating a real-world privacy and secure email test.

I Tested Free Encrypted Email—and Found an Unexpected Proton Alternative

Why we tested encrypted email ourselves

I wanted to find out whether free encrypted email services could protect a real conversation with someone using an ordinary mailbox. I tested Proton Mail, Atomic Mail and Tuta, focusing on what worked in practice rather than relying on feature lists. If you are starting with everyday account security, our guide to managing passwords explains the basics before you add encrypted email.

Our practical scenario was simple: send a password-protected email from a privacy provider to an external mailbox hosted by Hostinger, open it there, and reply securely. We used Microsoft Edge for the main test; this was not a Tor Browser experiment. We also noted practical limitations visible on the free plans.

How an unexpected alternative changed my plans

I started this experiment expecting to compare Proton Mail and Tuta. I wanted firsthand evidence, not a list of marketing promises. Proton’s password-protected external email and secure reply worked. Mailfence registration did not succeed, so we could not complete its test.

Then I discovered Atomic Mail. Its verification code landed in Gmail’s Spam folder, and its interface was labeled beta. Neither was an ideal first impression. But the free account opened successfully, and the password-protected message reached my external Hostinger inbox. I unlocked it and replied through Atomic Mail’s secure webpage. The reply appeared in my Atomic Mail inbox without another password prompt.

Tuta’s password-protected external message and secure reply also worked in our November 7 test. What happened next was the real surprise: I found a free custom alias feature so useful that I decided to keep using Atomic Mail alongside my main Gmail account. I might even consider paying for it if it proves reliable over time. That is my personal experience, not proof that a beta service is more secure than an established competitor.

Our results at a glance

Test Proton Mail Tuta Mail Atomic Mail
Registration Passed Created Passed
Protected external email Passed Passed Passed
Secure external reply Passed Passed Passed
Free email alias Passed (Proton Pass) Not included Passed (built-in)
Receive email via alias Passed Not included Passed
Reply without exposing primary address Passed (alias reply) Not included Passed (protected reply)
Inactivity policy 24 months (terms) 6 months (deletion) No inactivity deletion

Inactivity policies (official documentation, not tested): Proton’s Terms of Service allow deletion of free accounts after 24 consecutive months of inactivity; its support article also contains annual-activity advice, so users should follow the more cautious guidance. Tuta says free accounts are deleted after more than six months without a login. Atomic Mail’s terms say accounts are not deleted solely for inactivity, although other suspension or termination grounds still apply. These policies may change.

Alias terminology matters: Proton Free includes up to 10 hide-my-email forwarding aliases, according to Proton’s official documentation, but newly created permanent additional Proton addresses generally require a paid plan. Proton also supports plus-address variations. Tuta’s official free-plan comparison does not include additional email addresses; aliases require a paid plan. We personally created a Proton Pass alias, sent a test message to it from Hostinger, received it in Proton Mail and replied. Hostinger showed the alias in both the From and Reply-to fields, not our primary Proton address. Atomic Mail’s built-in alias and password-protected reply were also tested firsthand. These are different alias workflows; Proton’s alias reply test was not a separate password-protected-message test.

Proton Mail: our completed encrypted email experiment

1. Compose and protect the message

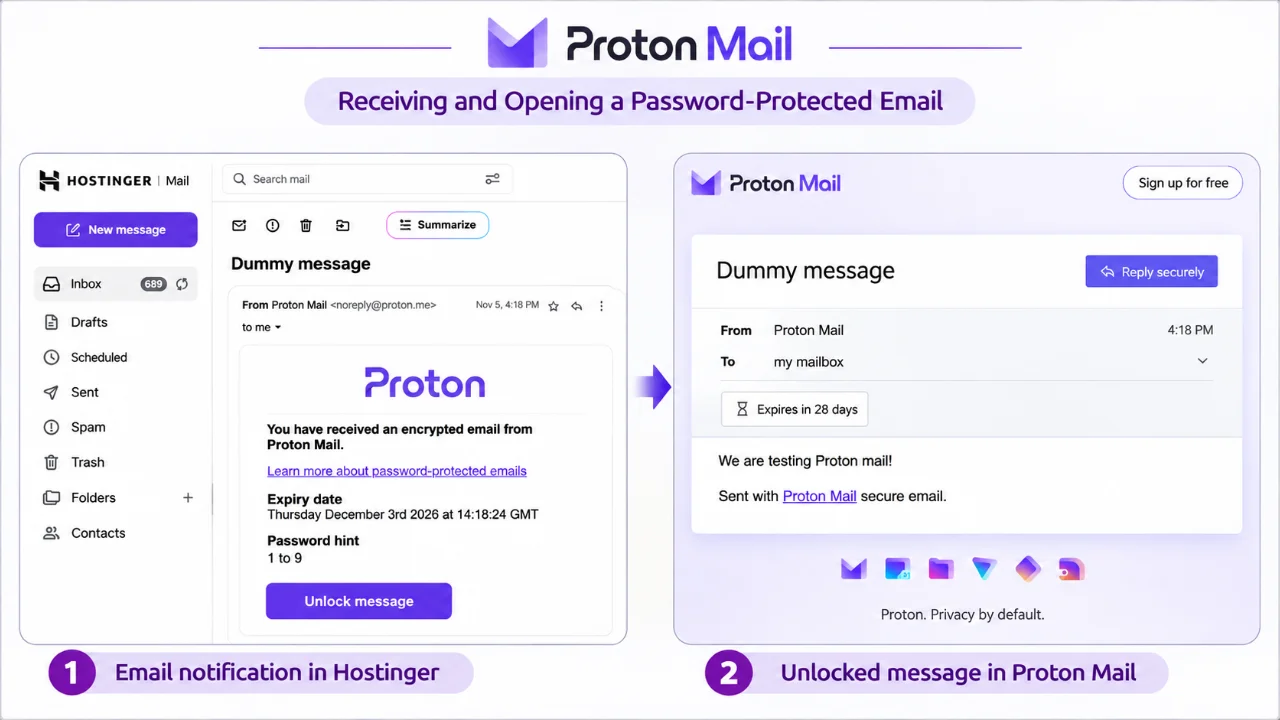
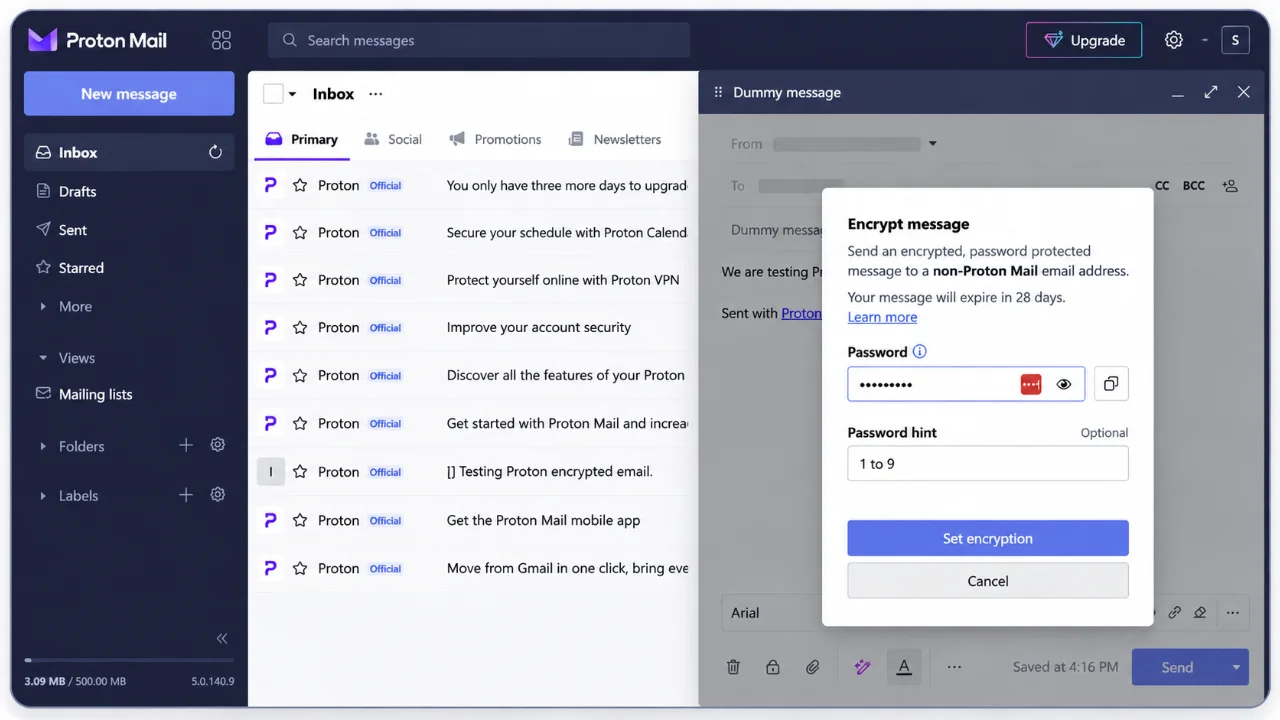
Using a free Proton Mail account, we wrote a test email titled “Dummy message” to an address outside Proton, hosted by Hostinger. In the composer we selected the option to encrypt the message with a password and could add an optional password hint. The interface indicated that the protected message would expire after 28 days, consistent with Proton’s official password-protected email instructions.

Proton Mail password-protected email setup showing the encryption dialog, password field, optional hint, and 28-day message expiration for an external recipient.

2. What arrived in the ordinary inbox?

In Hostinger Mail, the recipient received a notification containing the sender, subject, password hint and a button to unlock the message. The original message body did not appear in the ordinary inbox. Instead, the recipient followed the link to a Proton-hosted secure webpage.

Proton Mail encrypted email test showing a notification received in Hostinger Mail and the password-protected message opened securely in Proton Mail.

Importantly, the external inbox receives a notification, while the protected content is accessed through Proton’s secure page. The subject and other notification details should not be mistaken for end-to-end encrypted content.

3. Unlock and read the message

Once the recipient entered the shared password on Proton’s secure page, the recipient successfully read the test message. The page also offered a “Reply securely” action.

4. Reply securely without a Proton account

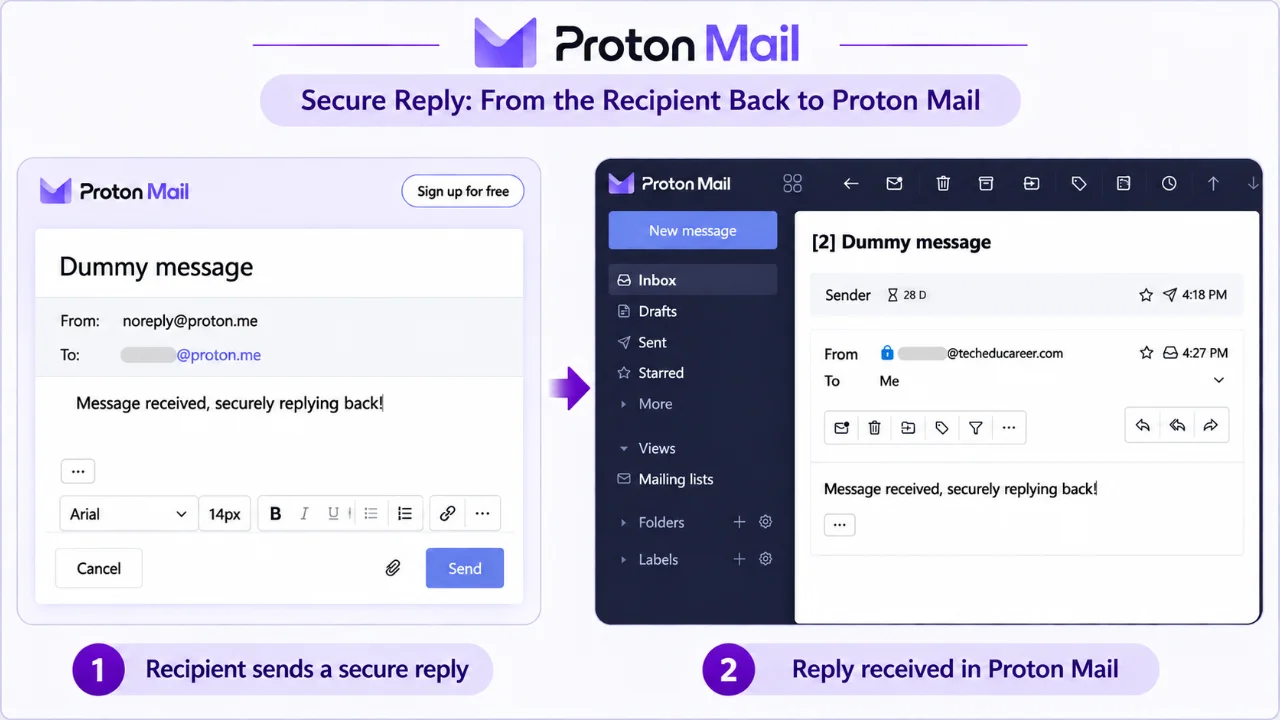
Next, the external recipient used the secure reply form to send “Message received, securely replying back!” In turn, the response arrived in the original sender’s Proton inbox and could be read while logged in, without another password prompt. This confirmed that our two-way protected conversation worked on the free account.

Proton Mail secure reply test showing an external recipient composing a protected reply and the received response appearing in the Proton Mail inbox.

What this test does not prove: encrypted email is not the same as anonymity; and it does not replace two-factor authentication and passkeys for protecting account access. The recipient can still copy or screenshot content, and a compromised device remains a risk. We did not conduct a cryptographic audit of either service.

Atomic Mail: our second completed secure-email experiment

Atomic Mail also made a positive impression with its modern, clean interface and intuitive user experience. I installed it as an app on my Windows computer, where it now sits near the clock in the taskbar notification area. As a result, I can access my mailbox without keeping an Edge tab open all day. It is a small but genuinely useful everyday convenience.

After difficulties with Tuta and Mailfence registration, we successfully created a free Atomic Mail account. Its interface was marked “beta.” The verification email sent to our Gmail recovery address landed in Spam, a deliverability observation rather than proof of weak encryption.

1. Compose a password-protected message

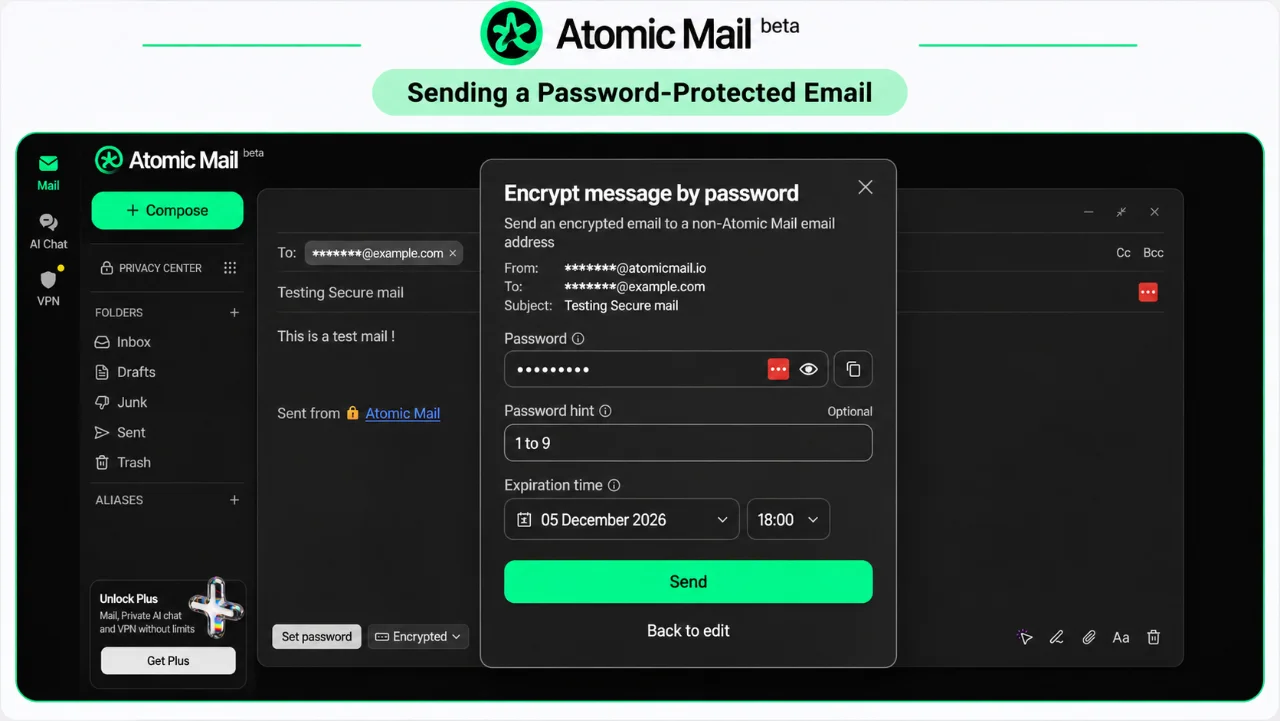
We addressed a test email titled “Testing Secure mail” to the same external Hostinger mailbox used for Proton. Atomic Mail offered an “Encrypt message by password” dialog with a password, optional hint and expiration date. We selected December 5, 2026, approximately 30 days after sending.

Atomic Mail password-protected email setup showing the encryption dialog, password hint, expiration settings, and Send button in its dark-mode interface.

2. Notification, unlocking and reading the message

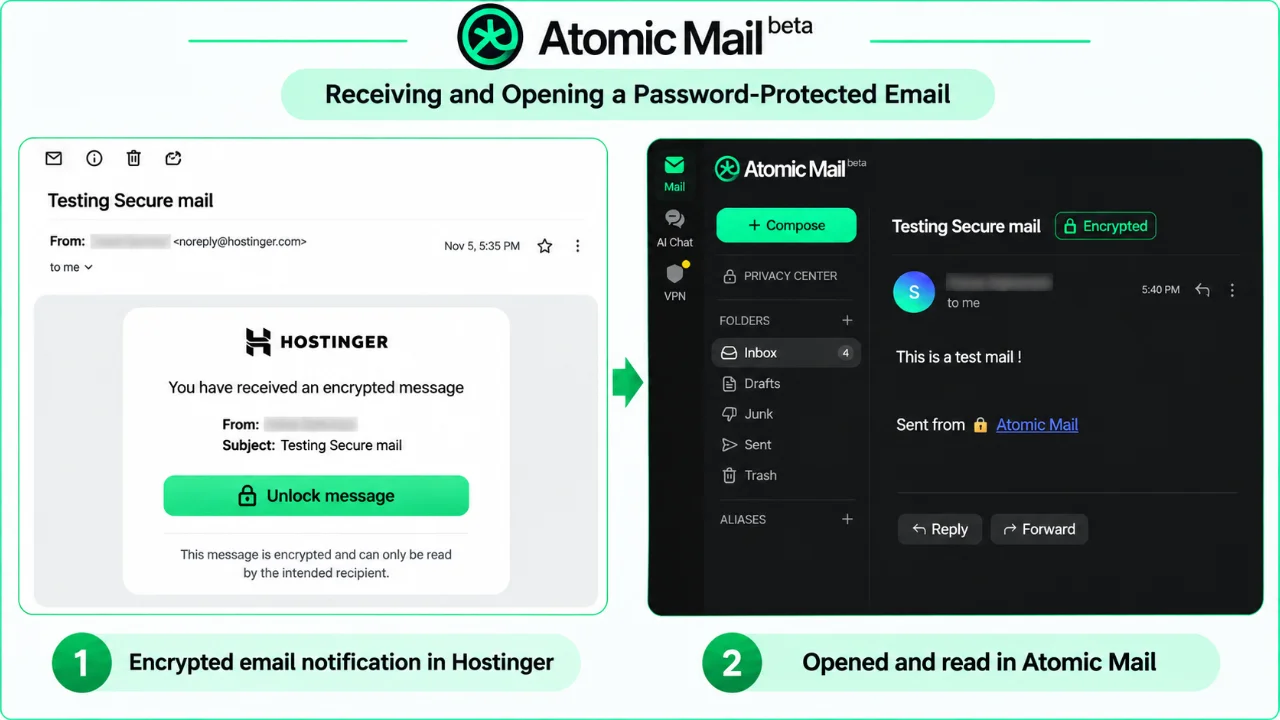
The Hostinger inbox received an Atomic Mail notification displaying the sender, expiration date, password hint and “Unlock message” button, but not the protected message body. This resembles the workflow we observed with Proton.

Atomic Mail encrypted email test showing a notification received in Hostinger Mail and the password-protected message opened and read securely.

We opened the protected message on Atomic Mail’s webpage and read the body “This is a test mail !”. The page offered a Reply button without requiring the external recipient to register an Atomic Mail account.

3. Secure reply delivered

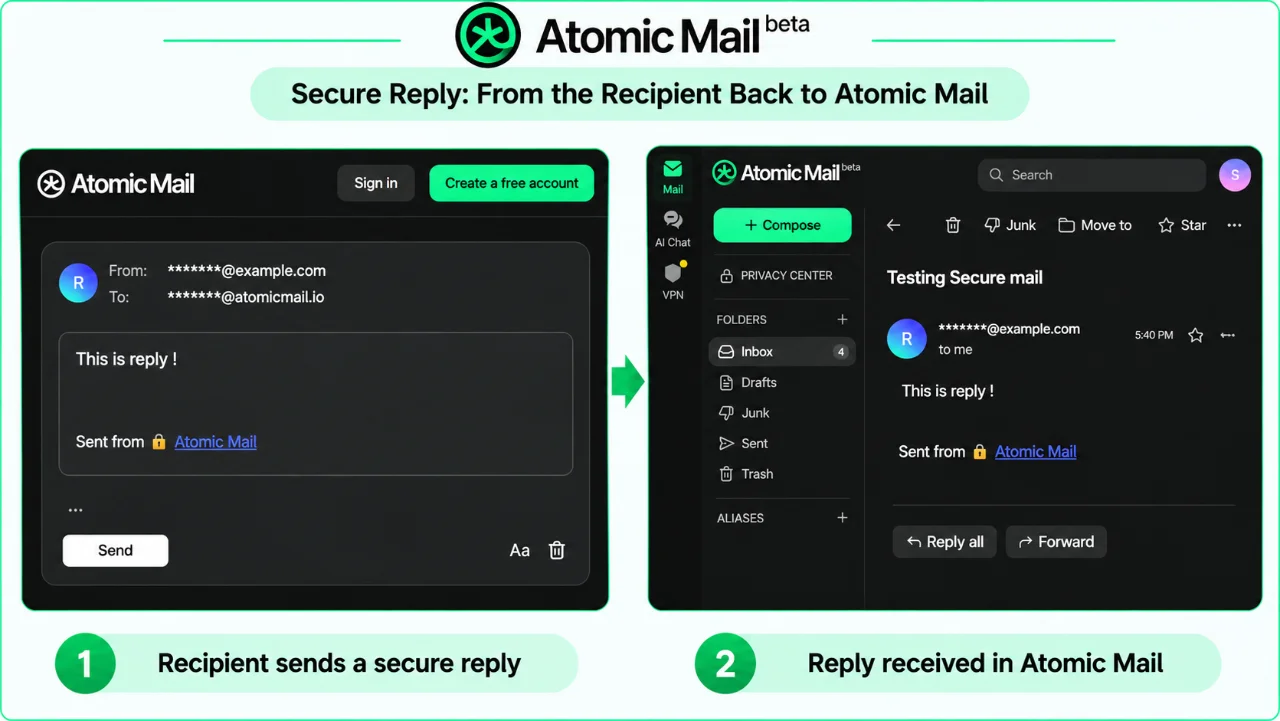
The external recipient composed and sent “This is reply !” through the secure reply page. It arrived in the Atomic Mail sender’s conversation and was readable without entering the shared password again. The full send–unlock–reply workflow therefore worked in our free-account test.

Atomic Mail secure reply test showing an external recipient composing a protected reply and the successfully delivered response appearing in the Atomic Mail inbox

Limits of our findings

This is a functional test, not an independent cryptographic audit. Atomic Mail was marked beta, and we have not assessed its long-term reliability, all free-tier limits or whether its security architecture is equivalent to Proton or Tuta.

Free aliases: the feature that surprised me most

An email alias is an additional address connected to your main inbox. For example, you can use one alias for online shopping and another for newsletters, without sharing your primary address everywhere. If an alias attracts unwanted mail, you can disable it without changing your main address. Aliases help with organization and address separation, but they do not guarantee anonymity. For the setup steps and current plan allowances, see Atomic Mail’s official email-alias FAQ.

Atomic Mail displayed a free-alias allowance of 10.

For comparison, Proton Free officially includes up to 10 hide-my-email forwarding aliases, and we tested one of those aliases ourselves. However, these differ from permanent additional Proton addresses, which generally require a paid plan. Tuta lists additional addresses as a paid feature.

Meanwhile, the Atomic Mail creation screen distinguished longer custom aliases from premium four-character addresses, advertised from $5 per month. A separate randomly generated “Hide My Email” feature was promoted with Atomic Mail Plus. These are distinct features.

Proton Pass aliases: our follow-up test

To make the comparison fair, we also tested Proton’s free hide-my-email aliases. We signed into Proton Pass with the same free Proton account, selected an alias domain and created a shopping-themed forwarding alias. Proton Pass showed an allowance of 10 aliases on the free account. Next, we sent an ordinary email from our Hostinger mailbox to the alias. As expected, it arrived in our regular Proton Mail inbox.

We clicked Reply in Proton Mail and sent a response. In Hostinger, the received reply displayed the Proton Pass alias in both the From and Reply-to fields—not our primary Proton address. This confirms that the free reply workflow protected the primary address in our test. We did not test sending a new, unrelated message from that alias or adding password protection to this particular alias reply.

Which alias experience felt simpler?

Both free workflows worked. However, I personally preferred Atomic Mail’s approach. The Atomic Mail alias we created also looked cleaner and easier to share than Proton Pass’s automatically generated address, which included an extra random-looking suffix. This was an impression of the particular aliases we created, not a claim that every Proton alias must look that way.

Atomic Mail lets me create and manage the tested custom alias within the same email application where I read and reply to messages. By contrast, with Proton, I used Proton Pass to create and manage the forwarding alias and Proton Mail for correspondence. Although the products integrate successfully, moving between them added steps and could be less intuitive for a newcomer. Importantly, this is a usability preference based on our test, not evidence that either provider copied the other’s design or that one offers stronger encryption.

Creating and receiving through a free alias

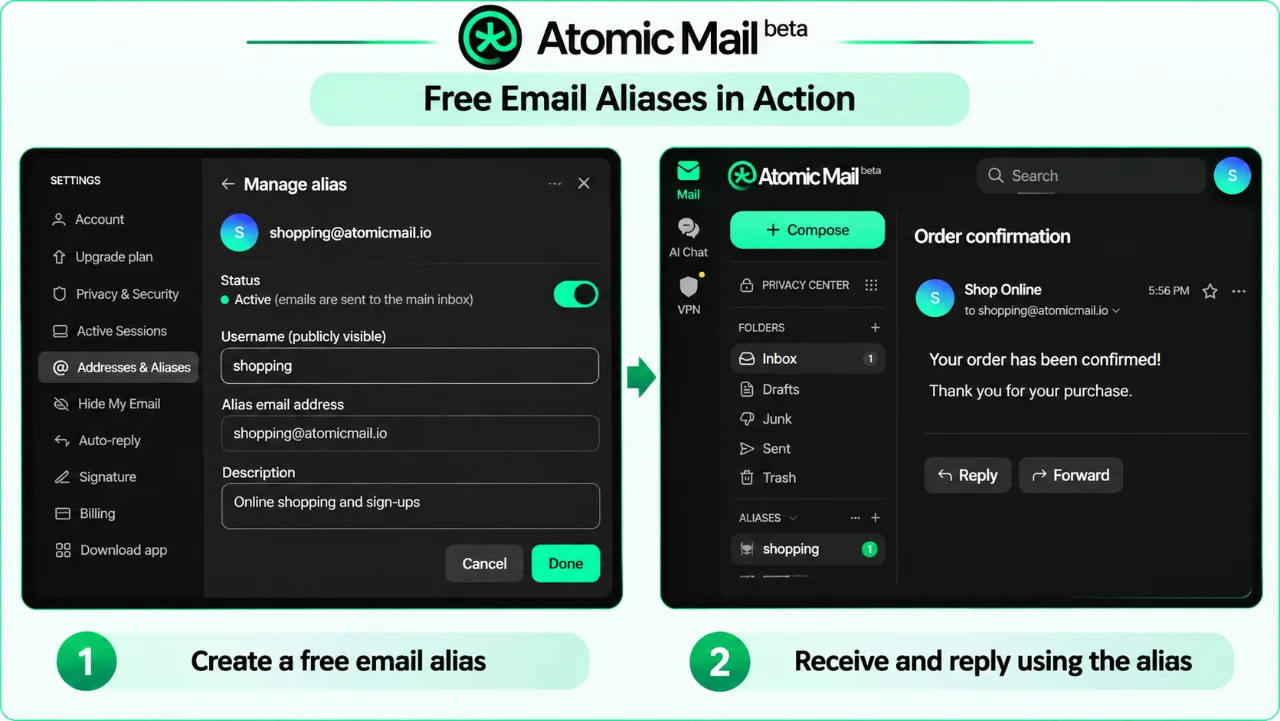
I created a free Atomic Mail alias without paying. The management screen showed it as active, with an on/off switch, a public username and an optional description. Atomic Mail indicated that messages sent to the alias would arrive in my main inbox. I tested this by sending a regular email from my Hostinger mailbox to the alias; it arrived successfully, confirming inbound delivery. The screenshot below is an illustrative, anonymized recreation of the same workflow, using a shopping alias and an order-confirmation example rather than my actual test address or message. Atomic Mail also describes free email aliases among its privacy features.

Illustrative Atomic Mail free alias workflow showing a shopping alias in settings and an order confirmation arriving in the inbox.

Sending an encrypted reply from the alias

I replied to the incoming message and selected password protection. The encryption dialog showed my test alias in the From field—not my primary Atomic Mail address. Hostinger then received an encrypted-message notification showing the alias as sender. I unlocked the message on the Atomic Mail webpage and read the protected reply. The entire alias-receive-and-encrypted-reply workflow worked in my free account.

This is useful address separation, not complete anonymity. In addition, I tested one working alias, not all ten advertised slots, and did not test long-term deliverability or the separate paid Hide My Email feature.

Tuta Mail: our completed encrypted email experiment

1. Send a password-protected email to an external mailbox

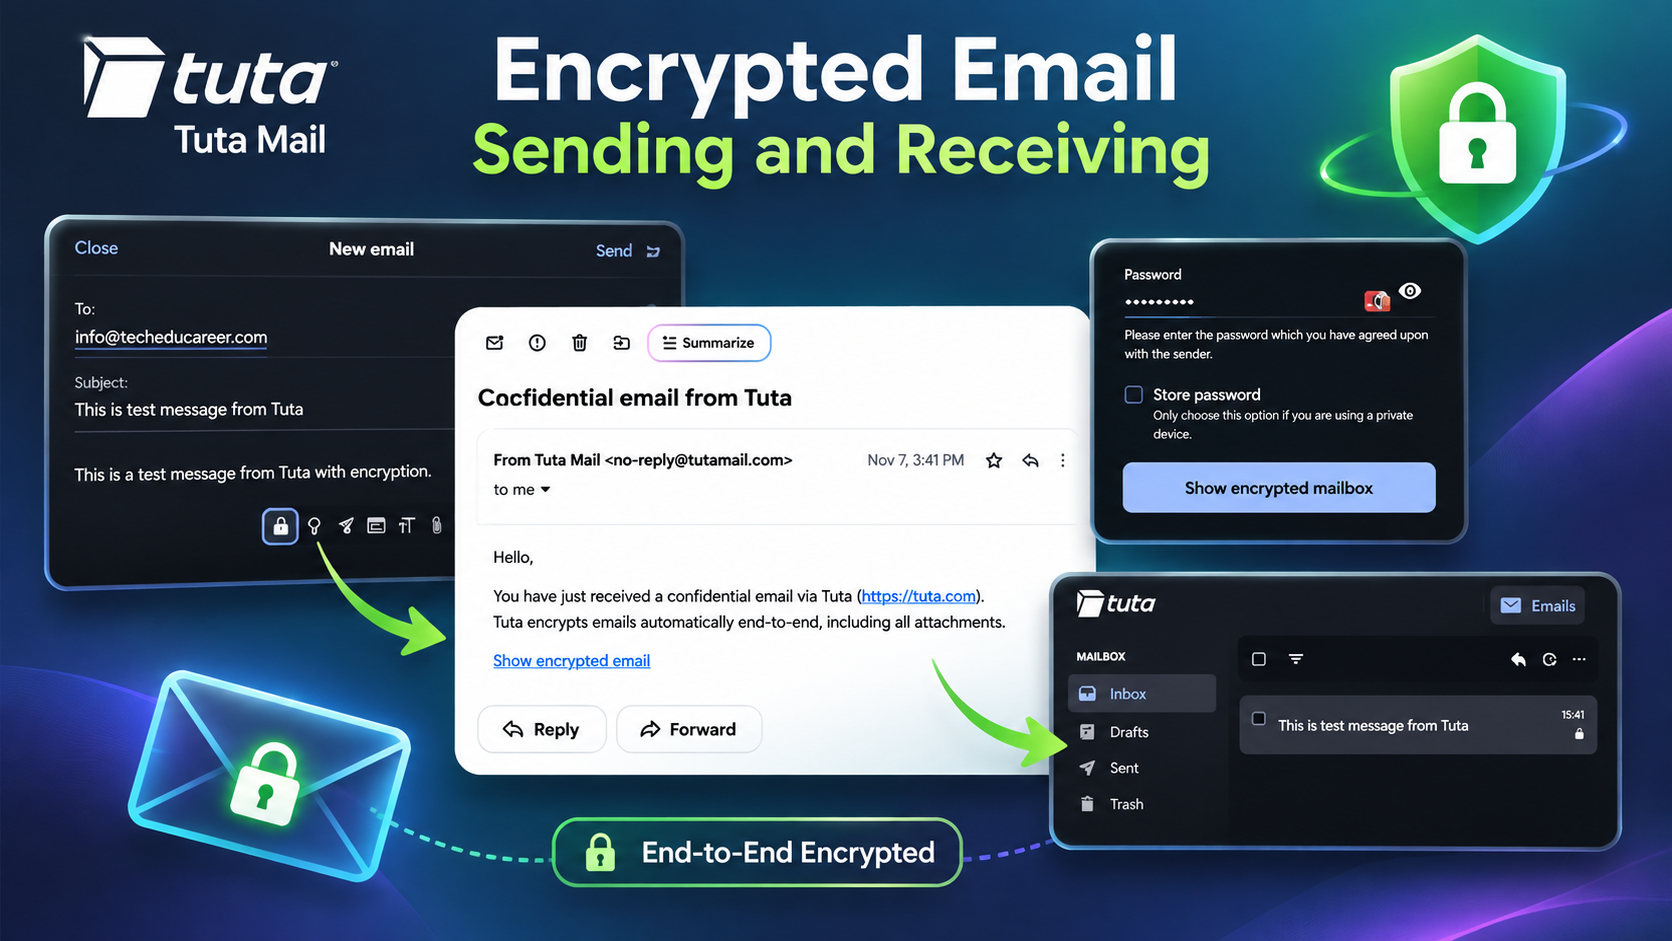
For the Tuta test, we composed a message using our free account to the same external Hostinger-hosted mailbox used for Proton and Atomic Mail. The subject was “This is test message from Tuta,” and the body said “This is a test message from Tuta with encryption.” Tuta’s composer displayed a password field for the external recipient and indicated that the message would be sent end-to-end encrypted.

2. Receive the notification and unlock the message

In turn, the ordinary external inbox received a notification headed “Confidential email from sahak.sg.” It contained a link labeled “Show encrypted email,” rather than displaying the protected message body. Next, following that link opened a Tuta password screen asking for the password agreed with the sender. Once we entered it, we could view the original test message in Tuta’s secure mailbox interface.

Tuta Mail encrypted email test showing message composition, confidential email notification, password access, and decrypted messageCaption: Our Tuta Mail test: a password-protected message was sent to an external mailbox, which received a notification linking to the secure message.
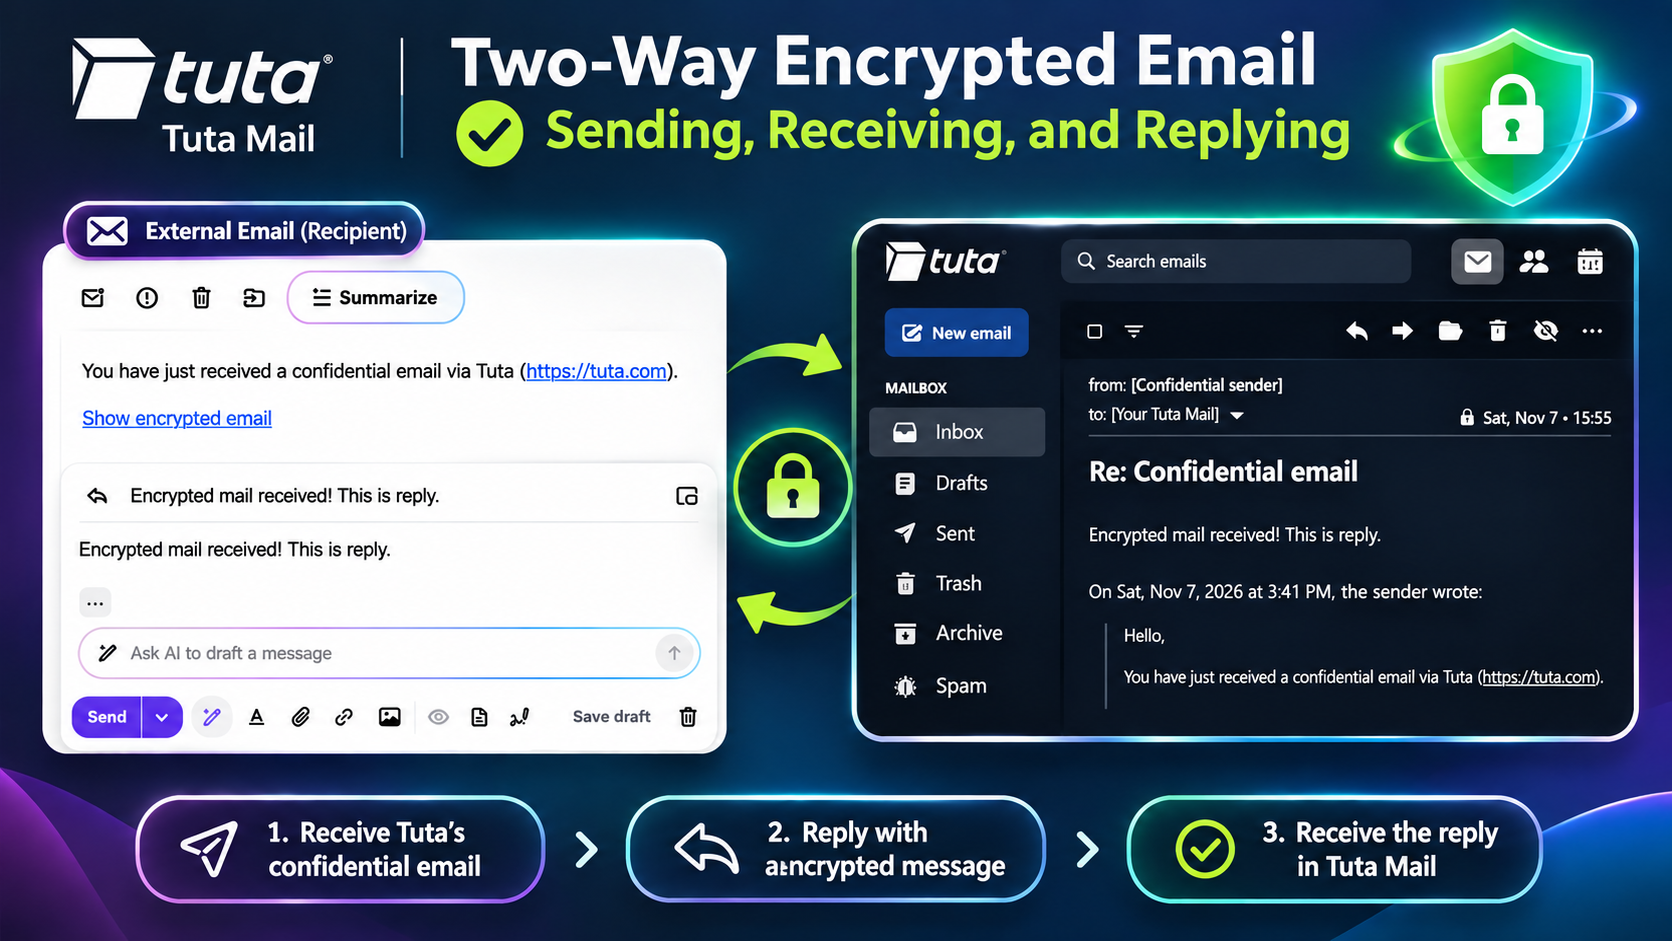
This is an important practical distinction: the ordinary inbox received a notification and link, while reading the protected body required access to Tuta’s password-protected interface. The notification and its visible metadata should not be treated as end-to-end encrypted message content.

3. Reply from the external recipient and receive it in Tuta

Next, we replied from the external recipient’s secure message interface with the text “Encrypted mail received! This is reply”. At 3:55 PM on November 7, the response appeared in the Tuta inbox with a reply subject and the expected text. The reply was readable in the signed-in Tuta account. This completed the two-way external-message workflow in our free-account test.

Tuta Mail two-way encrypted email test showing a reply from an external recipient and its successful arrival in the Tuta inbox.Caption: The external recipient replied through Tuta’s protected interface, and the response arrived in our Tuta Mail inbox during the November 7 test.
4. A free-plan condition worth noting

Tuta’s free-plan registration page stated: “Account will be deleted after 6 months if not logged into.” It also displayed 1 GB of storage, one free account per person, no extra email addresses and a restriction against business use. For an address used only occasionally, this inactivity condition is worth considering. We later checked the published inactivity policies of all three providers, as summarized in the comparison table. These are policy statements, not outcomes of a long-term inactivity test.

Limits of our findings: we demonstrated a successful password-protected send, unlock and secure reply using one free account and one external mailbox. We did not audit Tuta’s encryption implementation, measure long-term reliability or test every free-plan feature. Our observations describe the tested workflow rather than every possible Tuta use case.

Mailfence: our registration did not succeed

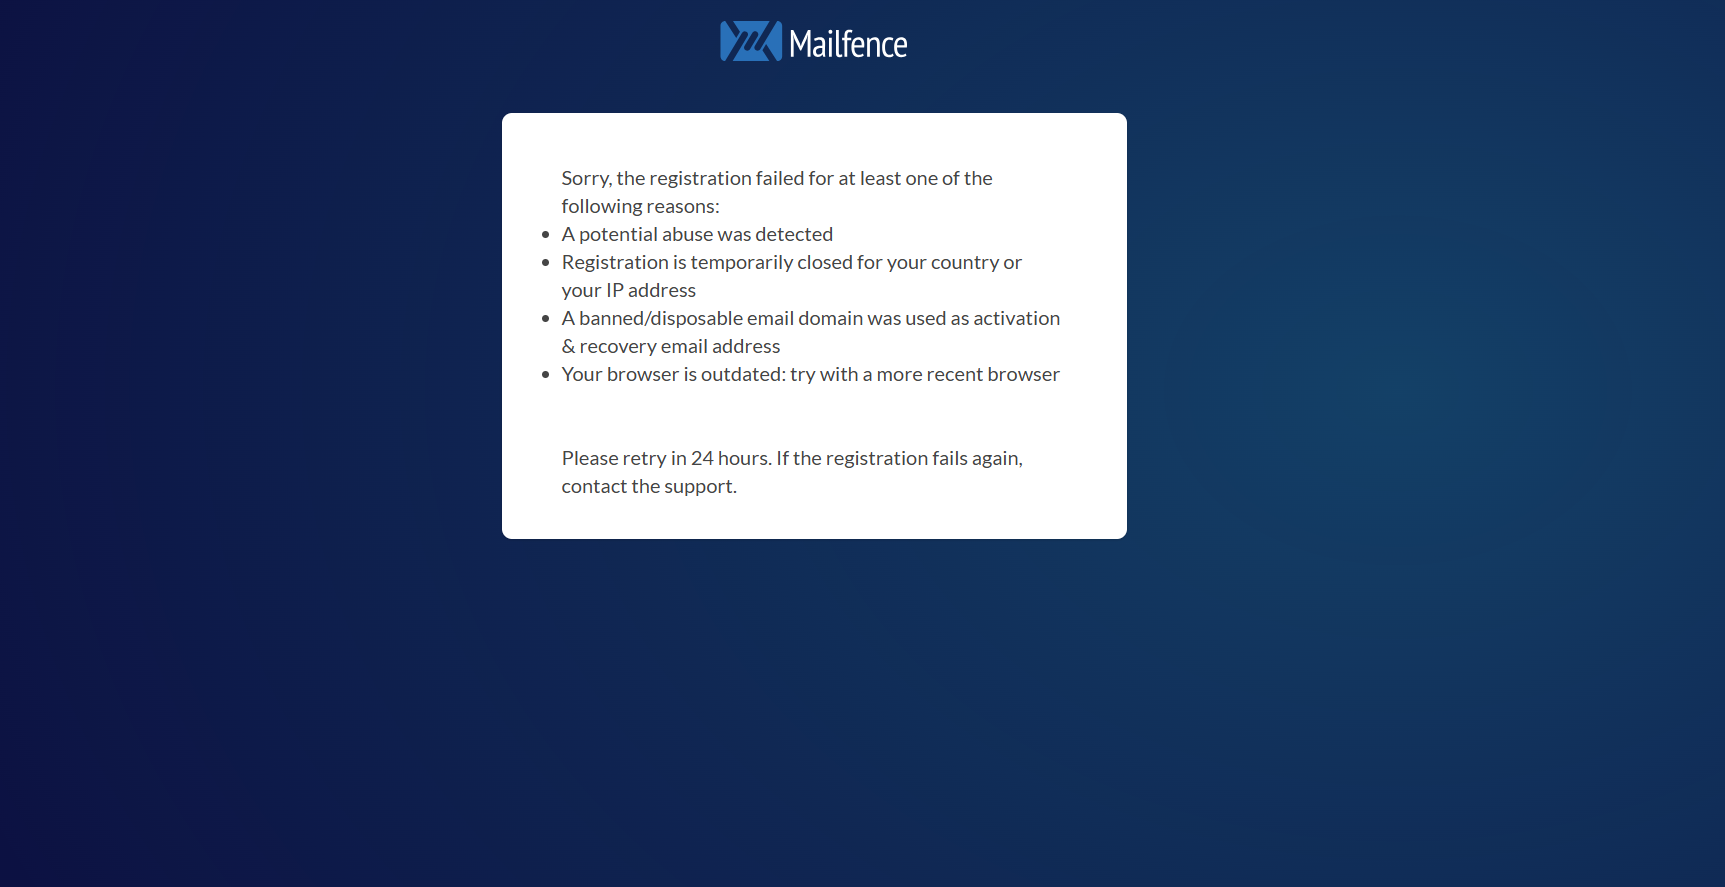
We attempted to create a Mailfence account, but the service displayed a registration failure. Its message listed several possible reasons: potential abuse detection, temporary country or IP restrictions, a banned or disposable activation/recovery email domain, or an outdated browser. The message did not specify which reason applied to us. It advised retrying in 24 hours and contacting support if the problem continued.

Mailfence registration failure screen showing possible causes, including abuse detection, IP restrictions, recovery email restrictions, and an outdated browser, with advice to retry after 24 hours.Caption: Mailfence registration-failure notice.
We decided not to change networks or continue troubleshooting. As a result, we cannot evaluate Mailfence’s actual encrypted-message workflow from firsthand experience, and a failed registration alone does not establish a general problem with the service.

What we learned from the completed tests

The biggest surprise was how well both Proton’s and Atomic Mail’s free aliases worked in practice. Proton’s reply preserved the alias address, while Atomic Mail let us receive through its built-in alias and send a password-protected reply from it. I preferred Atomic Mail’s single-interface workflow, although Proton’s separate Pass and Mail applications worked together successfully. I now intend to use it alongside Gmail, while keeping critical accounts on an established provider until I have more experience with its reliability.

In our tests, Proton Mail, Atomic Mail and Tuta all completed the core journey: send a password-protected message to an ordinary mailbox, unlock it and reply securely. Mailfence did not allow us to finish registration.

All three tested providers worked for the protected external-message workflow. Proton and Atomic Mail also passed our respective free-alias receive-and-reply tests, although their alias types and reply protection differed; this does not establish which service is best overall. Encryption architecture, metadata handling, recovery options, account retention, paid-plan features and long-term reliability all deserve separate assessment.

These results come from my own hands-on experiments, and your experience may be different. That’s why I’d encourage you to try a few services yourself. Gmail is familiar, convenient, and widely used, but that doesn’t mean it has to be your only option. You might discover a feature you didn’t know you needed, a different approach to privacy, or simply an email service that feels better to use. That’s exactly what happened to me—and sometimes the most interesting discoveries begin with a little curiosity.

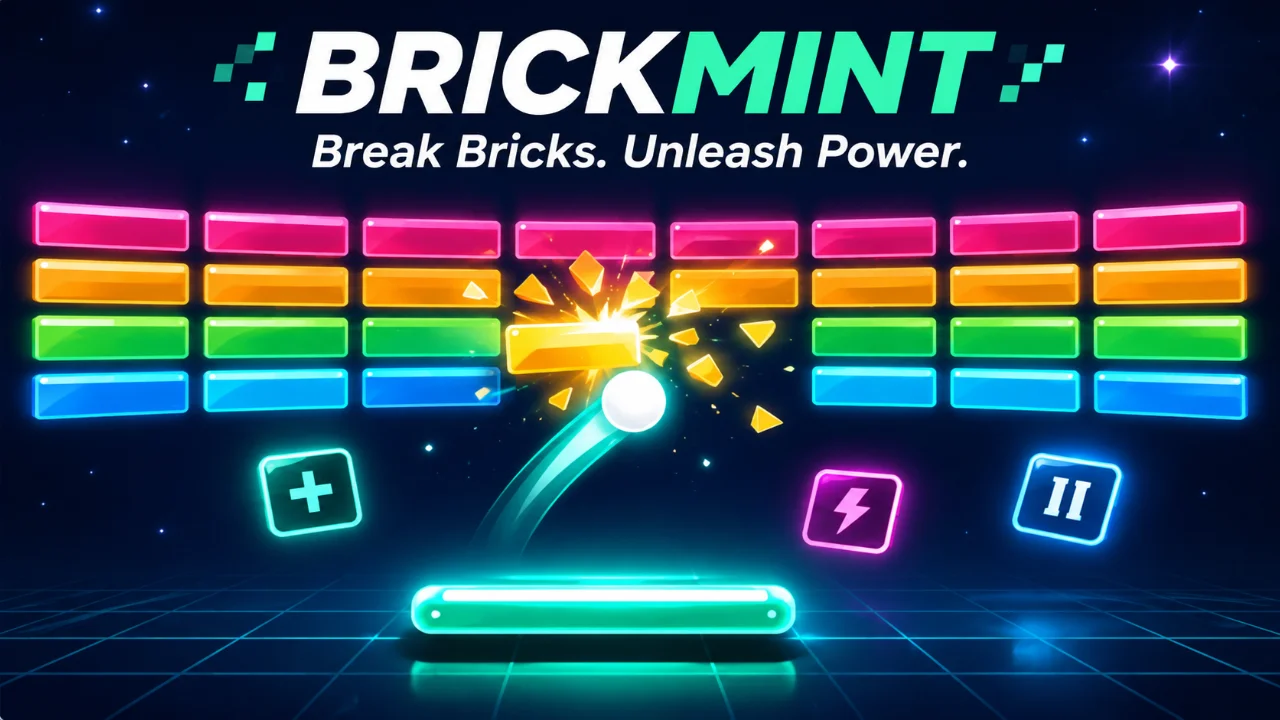
BrickMint arcade brick breaker game featuring colorful neon bricks, a glowing paddle, power-ups, and a bouncing ball, with the tagline “Break Bricks. Unleash Power.”

We Gave ChatGPT a Windows Game—and Built Something New

We gave ChatGPT a small Windows game, asked it to investigate the executable, and ended up creating something of our own. Here’s what happened.

There is something fascinating about old computer games. They might look simple compared with modern titles, but behind their colorful graphics and straightforward controls lies a surprising amount of programming logic.

Recently, I decided to try an experiment with ChatGPT. Instead of asking AI to create a game from scratch, I wanted to see whether it could investigate an existing compiled game, understand how parts of it worked, and use those discoveries to help us build something new.

Our starting point was a small Windows brick-breaker game. Eventually, the experiment led us to create BrickMint, our own free browser game. However, the most interesting part wasn’t the finished game. It was everything we discovered along the way.

The Challenge: Can AI Really Reverse Engineer a Game?

Asking ChatGPT to write a simple game isn’t particularly surprising anymore. If you’re new to the subject, our beginner’s guide to game development explains the foundations. Describe the rules, choose a programming language, and AI can generate a playable prototype. I wanted to explore something different, though.

What if we provided ChatGPT with a compiled Windows executable rather than its source code? Could it examine the program and identify actual gameplay mechanics? Could it distinguish between what it discovered and what it was simply inventing?

Creating a brick breaker based on a description is not reverse engineering. To call our experiment reverse engineering, we needed to investigate the actual executable and find evidence of how its code worked.

Step 1: Examining the Original Game Files

The original game arrived as a ZIP archive containing a Windows executable, several DLL files, and an assets directory. The executable itself was only 32 KB.

We found textures for the paddle, bricks, space background, and special brick types. Filenames suggested extra health, multiball, and slowdown effects. However, a file named BrickTextureMultiBall.png doesn’t tell us how multiball works. To investigate that, we needed to look inside the executable.

Step 2: Looking Inside the Compiled Program

ChatGPT identified a 32-bit Windows program and examined its machine-code instructions with a disassembler. Disassembly translates machine instructions into assembly language, helping reveal what a compiled program does. We did not have the original source code.

Our investigation focused on patterns, calculations, function calls, and memory locations. We identified references to the SIGIL graphics library and functions associated with mouse input, drawing, and frame timing. Gradually, code for updating positions, checking boundaries, handling collisions, and changing gameplay variables emerged.

Important limitation: this was static analysis, not a full runtime debugging session. Some behaviors could be supported directly by instructions; others still required interpretation.

Step 3: Discovering How the Ball Moves

One of our first findings involved ball movement. The executable contained calculations combining movement values with elapsed frame time. In simplified form:

position = position + velocity × elapsed time

Accounting for elapsed time helps keep motion consistent across computers running at different frame rates. For browser games, the requestAnimationFrame API is a standard way to schedule animation updates. We also found boundary checks and changes to the ball’s direction. These provided useful principles for our browser version.

Step 4: Investigating Collisions

Collision detection was one of the most interesting parts. A brick breaker needs to determine when a ball touches a brick, how it should bounce, and whether the brick should disappear.

The disassembly revealed code that iterated through brick records and checked collisions, plus paddle-related calculations involving trigonometric functions. One useful detail was position correction after a collision: if the ball remains overlapping a brick, simply reversing its direction can cause repeated or unusual bounces.

We used this discovery to improve our own prototype. Rather than merely recreating a game’s appearance, we were learning from its implementation.

Step 5: Finding Hidden Gameplay Mechanics

As we investigated further, we found several interesting mechanisms:

  • Multiball: code initialized additional ball records and set the active count to three. Scoring also used the active-ball count.
  • Extra lives: activating one type of special brick increased the player’s life count.
  • Slow motion: the executable contained a temporary effect reducing speed to approximately 35% for around five seconds.
  • Score and high score: both values appeared in the program, along with logic that could reduce a positive score over time.
  • Speed progression: the executable contained bounded acceleration logic.

That last finding led to a design discussion. A ball that becomes too fast can turn a fun game into a frustrating one. We chose to make later levels harder through brick arrangements and durability rather than dramatic acceleration.

Step 6: From Investigation to Our Own Game

While examining the original game, ChatGPT also helped us build a playable browser game using HTML, CSS, and JavaScript. The first version was simple: a paddle, a ball, bricks, and the objective of clearing them without losing all your lives.

Through repeated testing, we adjusted controls, improved collision handling, and introduced new mechanics. Some ideas were inspired by the executable analysis; others were our own. Instead of reproducing the original game instruction by instruction, we were creating an independent game informed by what we learned.

Step 7: Making the Game Our Own

As the prototype evolved, we added:

  • Reinforced bricks: some bricks take two or three hits, changing color as they weaken.
  • Multiple guns: weapon bonuses can equip the paddle with a three-gun configuration.
  • Changing formations: hexagonal, diamond, zigzag, clustered, and randomly generated brick layouts replace repetitive rectangular grids.
  • Temporary power-ups: extra lives, multiball, slowdown, and other bonuses introduce variety.

The Laser Ball

Our final special idea was a piercing ball that temporarily flies through bricks instead of bouncing off them. It can destroy several bricks along its path, including reinforced ones. It was a dramatic finishing touch that didn’t require making the ball faster.

Step 8: Introducing BrickMint

After several iterations, we named our game BrickMint. We gave it a glowing mint-green border and accents while preserving the colorful bricks and dark arcade background.

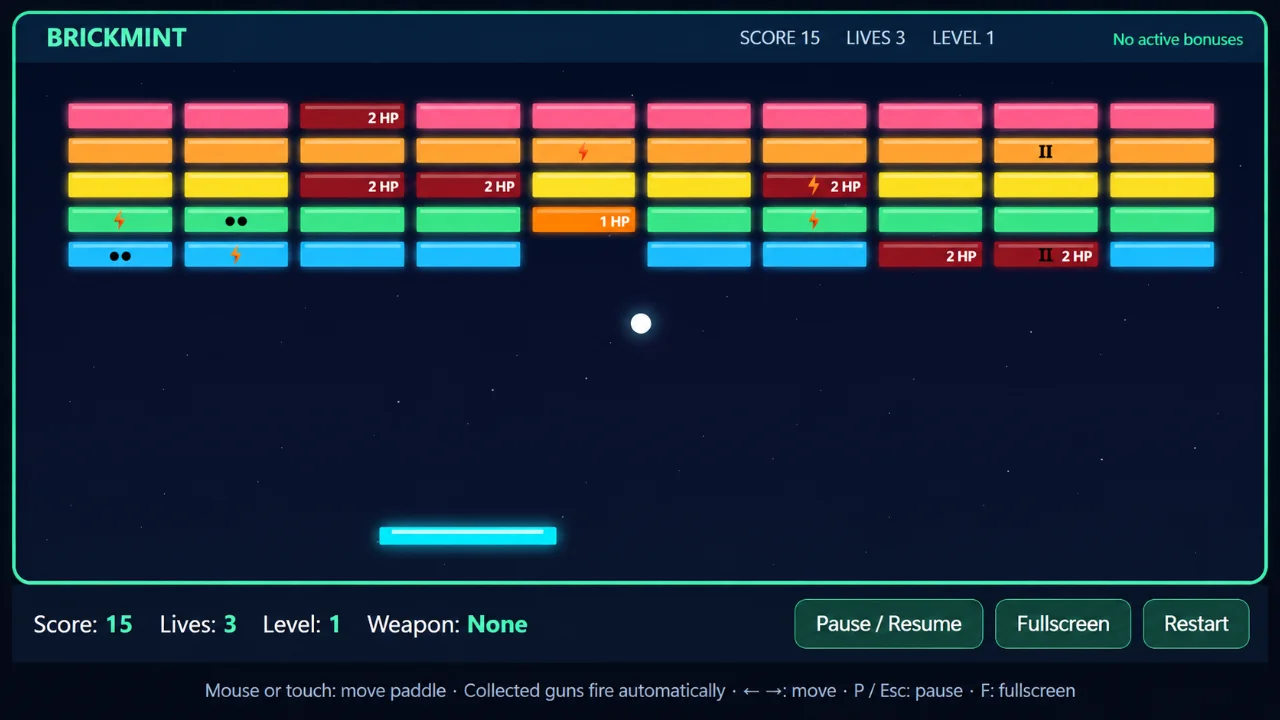
The result is a free browser-based brick breaker with multiple levels, reinforced bricks, power-ups, lasers, and changing formations. For more context on this format, see our guide to how browser games work and what makes them useful for learning. Visitors can play directly in their browser without installing the original Windows program.

BrickMint browser brick breaker game showing colorful bricks, power-ups, and a glowing paddle
BrickMint, our free browser-based brick breaker. Click the image to play.

🎮 Play BrickMint — Free Online Brick Breaker

What Did This Experiment Actually Prove?

The lesson wasn’t simply that AI could write a brick breaker. The interesting part was the combination of investigation, interpretation, implementation, and human decisions.

ChatGPT helped examine a compiled executable, identify relevant instructions, and reconstruct portions of its behavior. It then helped apply selected findings to a new game. However, not every discovery became a feature: we rejected aggressive acceleration and chose more interesting brick patterns instead.

AI contributed analysis and implementation; our testing and feedback shaped the final experience. This hands-on approach also shaped our earlier experiment on creating designs with AI.

What AI Could—and Couldn’t—Do

We did not recover the original source code, prove that every part of the original game was fully understood, or perform comprehensive runtime testing of the executable.

Some findings were directly supported by identifiable machine-code instructions; others required interpretation. Still, we uncovered genuine implementation details involving movement, collisions, special bricks, scoring, and speed-related logic.

That is a meaningful example of AI-assisted static reverse engineering. It also shows why verification matters: an AI explanation can sound convincing even when incomplete. Checking instructions, assumptions, and the resulting code is essential.

Final Thoughts: The Most Interesting Part Was the Journey

The journey started with one question: Can AI reverse engineer a game?

Ultimately, we examined a compiled Windows program, learned about its mechanics, and created a browser game of our own. Along the way, we discovered that AI can be a capable partner for exploring unfamiliar software, explaining complex ideas, and rapidly turning concepts into working prototypes.

Yet the best results don’t come from accepting every suggestion automatically. They come from asking questions, challenging assumptions, testing results, and deciding what actually makes the finished product better.

BrickMint is the result of that process.

🎮 Play BrickMint for free in your browser

Created as a TechEduCareer experiment in AI-assisted reverse engineering and browser game development.

Startup team collaborating around a laptop, with Slack, Pumble, Zoho Cliq, and Zulip logos and the title “Best Slack Alternatives for Startups in 2026.”

Best Slack Alternatives for Startups: Free Plans Compared

What are the best Slack alternatives for startups, and why do so many small teams still choose Slack when other messaging services offer free plans? The answer is not simply that Slack is better. A communication tool becomes the place where decisions, files, questions, and project context accumulate. The best choice depends on how much history a team needs, how it organizes discussions, and what it can afford as it grows.

For this comparison, imagine a startup with 25 employees planning to use the same communication platform for three years. We focus on four ready-to-use, cloud-hosted workplace messaging services: Slack, Pumble, Zoho Cliq, and Zulip Cloud. None requires the startup to manage a server. All four free plans support 25 employees, so team size alone does not force an upgrade. We also explain why Discord may suit a different type of collaboration.

Why message history matters more than a free-plan label

When evaluating the best Slack alternatives for startups, searchable project history deserves as much attention as pricing or storage.

A team chat is not only a place to exchange today’s messages. Six months later, someone may need to find why a feature was delayed, what a customer requested, or which technical approach the team rejected. If those conversations cannot be searched, colleagues may have to repeat discussions or rely on fragmented notes.

Free plans differ in a crucial way: some limit history by time, others by number of messages, and one of our candidates offers unlimited searchable messages on its free tier. A visibility limit does not always mean older data is immediately deleted; retention and deletion policies must be considered separately.

Best Slack alternatives for startups: free-plan comparison

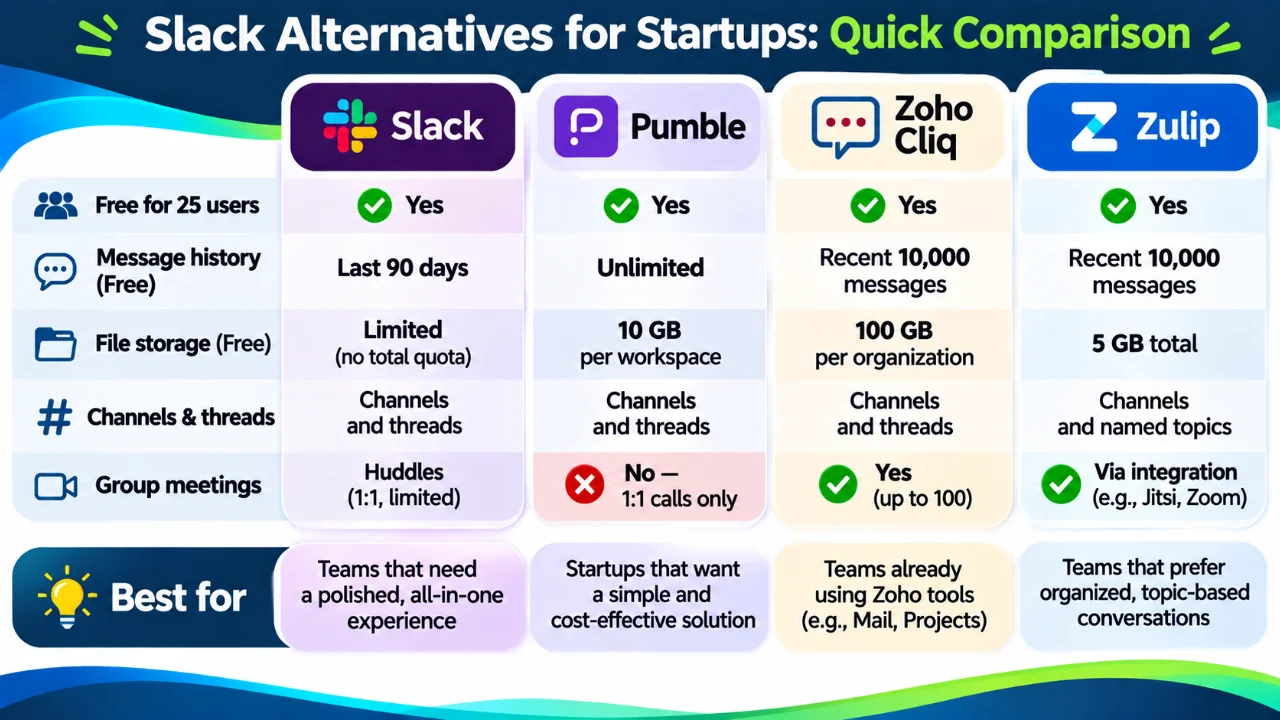
Feature Slack Free Pumble Free Zoho Cliq Free Zulip Cloud Free
Cloud-hosted, no server maintenance Yes Yes Yes Yes
Suitable for 25 users Yes Yes Yes Yes
Searchable message history Most recent 90 days Unlimited Recent 10,000 messages Recent 10,000 messages
Free file storage Files subject to free-plan history limits; no comparable published total-GB quota 10 GB per workspace 100 GB per organization 5 GB total
Conversation structure Channels and threads Channels and threads Channels and threads Channels and named topics
Group meetings included No; free huddles are 1:1 No; 1:1 calls Yes, up to 100 participants and 60 minutes Through an external meeting provider
Most notable advantage Broad app ecosystem Unlimited free history Storage and free meetings Organized asynchronous discussions

Can all 25 employees stay on a free plan? Yes. All four platforms support a 25-person team without requiring a subscription simply because of headcount. Whether the free plan remains practical for three years depends on message volume, file usage, meetings, integrations, and administration needs. A larger team may reach message-count and storage limits sooner than a smaller one.

Comparison of Slack, Pumble, Zoho Cliq, and Zulip free plans, including message history, file storage, meetings, and recommended startup use cases.

Plan features and prices can change; confirm current terms before subscribing.

1. Slack: the familiar benchmark

Slack organizes work around channels, direct messages, threads, and integrations. Its broad app ecosystem and established workflows help explain why teams continue to choose it even when less expensive alternatives exist.

What does Slack Free actually limit?

Slack Free provides access to the most recent 90 days of messages and files. Older content becomes unavailable to free users; Slack also applies a separate one-year deletion policy to older free-workspace content. This means day 91 does not erase an entire conversation, but a team that waits too long before upgrading or exporting may permanently lose older material.

Slack Free also limits app integrations to 10 and huddles to one-to-one conversations. For a startup with occasional discussions and a few connected tools, this may be adequate. For a company using chat as its long-term project memory, the history restriction is a serious consideration.

Slack Pro is listed at $7.25 per user per month when billed annually on its official comparison page. Its paid plan removes the free history-search window and expands meetings and integrations.

2. Pumble: a strong option for startups that need free history

Pumble follows a familiar channel-and-thread approach, with direct messages, file sharing, and workplace collaboration features. Its standout benefit is straightforward: unlimited message history on the free plan.

For 25 employees, Pumble Free offers 10 GB of total workspace storage. That can be enough for documents and occasional screenshots, but a team exchanging many videos, design assets, or large files should monitor usage. Free calling is focused on one-to-one communication; group meetings and screen sharing are paid features.

Pumble Pro is listed at $2.49 per seat per month billed annually. It adds group meetings, screen sharing, and 10 GB of storage per paid seat. A startup that primarily needs searchable conversations can begin free and consider an upgrade when meetings or storage become limiting.

3. Zoho Cliq: generous storage and group meetings on the free plan

Zoho Cliq provides workplace channels, direct and group conversations, integrations, and meetings. Its free plan includes 100 GB of storage per organization and group meetings with screen sharing, for up to 100 participants and 60 minutes.

The important trade-off is search history: free users can search the most recent 10,000 messages. This is a message-count limit, not a 90-day limit. A quiet team might take a long time to reach it; an active startup with multiple channels may reach it much sooner. The published limit concerns searchable history, so it should not automatically be described as permanent deletion of older messages.

Zoho Cliq Standard is listed at $16.20 per month for up to 25 users on annual billing, with unlimited searchable history. That makes its entry paid plan particularly interesting for a 25-person team. Professional and Enterprise plans add more advanced administrative capabilities; teams should assess whether they need those extras rather than paying for them by default.

4. Zulip Cloud: best for discussions that need clear topics

Zulip Cloud approaches workplace chat differently. Instead of relying mainly on channels and nested replies, it organizes conversations into channels and named topics. A development channel, for example, can contain separate discussions for an API change, a release issue, and a customer bug, making it easier to return to a specific subject later.

Zulip Cloud Free includes 10,000 messages of searchable history and 5 GB of total file storage. It offers extensive integrations and permissions. Calls use a selected external meeting provider rather than a built-in free group-meeting service.

Its Standard cloud plan costs $6.67 per user per month billed annually, with unlimited searchable history and 5 GB of storage per user. For engineering, distributed, or asynchronous teams, Zulip’s discussion structure may justify a higher price than simpler chat alternatives. For teams expecting a conventional Slack-like interface, it may require a change in habits.

Do startups really need large file storage in team chat?

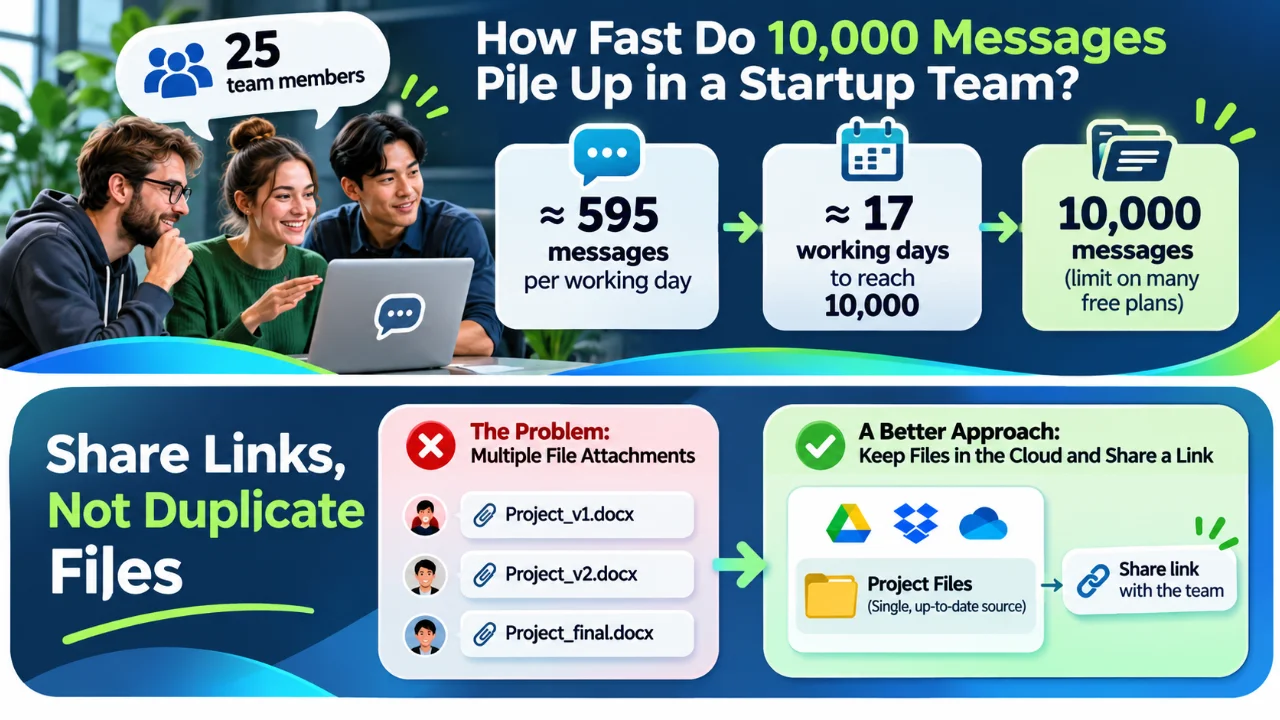
Free storage allowances differ substantially: Zulip Cloud provides 5 GB, Pumble 10 GB, and Zoho Cliq 100 GB. But the largest allowance is not necessarily the most valuable feature for a startup. Many teams already keep project plans, specifications, contracts, and working documents in shared storage such as Google Drive, OneDrive, or Dropbox. In those cases, posting a link to the authoritative document is often more useful than uploading another copy to a chat channel.

For example, if a project manager shares a 2 MB project plan as an attachment, that upload uses approximately 2 MB of chat storage. Repeatedly uploading revised versions can create unnecessary duplicates and confusion over which file is current. A link to the centrally managed document helps colleagues collaborate on the latest version, provided they have the appropriate access permissions. Screenshots, quick illustrations, and temporary files may still be convenient to attach directly.

Set communication rules before the team grows

Startup management should define how employees use messaging and shared storage rather than leaving everyone to invent their own habits. A simple internal communication policy can establish:

  • What belongs in chat: questions, brief updates, coordination, links to approved documents, and notifications.
  • What belongs in shared storage: current project plans, specifications, contracts, deliverables, and documents requiring version control.
  • What should not be posted in ordinary channels: passwords, API keys, confidential personal information, or sensitive client material without the required access controls.
  • How decisions are preserved: record important approvals, responsibilities, and final decisions in a designated project system or document so they do not disappear into message history.
  • Who can access shared links: check permissions before posting; a link does not automatically grant access, and an overly broad link can expose information.

This process can reduce unnecessary attachments, make information easier to find, and lower dependence on any messaging service’s free storage quota. It also makes future platform migration less disruptive. A related lesson appears in our article on choosing custom features versus WordPress plugins: select tools based on a real workflow, not just a feature list.

Why 10,000 messages may not be enough for a 25-person startup

A 10,000-message history allowance sounds substantial until you consider how a team actually communicates. The limit is measured in individual messages, not conversations: if a project manager asks a developer a question and the developer replies, that is two messages. A follow-up and another reply bring the total to four. Messages from different employees and conversations contribute to the shared history allowance.


Message volume is rarely distributed evenly. Project managers and team leads may coordinate several departments, while developers may send fewer but longer updates. Consider this illustrative 25-person startup:

Role Employees Messages/ person/ day Team messages per day
Project managers 2 80 160
Developers 15 15 225
Designers 3 20 60
Sales and operations 5 30 150
Total 25 — 595

At 595 messages per working day, the team generates 10,000 messages in approximately 17 working days—roughly three to four working weeks. These numbers are hypothetical, not measured usage statistics; the point is how quickly a busy team can reach a message-count threshold.

Infographic showing how a 25-person startup reaches 10,000 chat messages in 17 working days and why sharing cloud file links avoids duplicate attachments.

For Zoho Cliq Free and Zulip Cloud Free, a 10,000-message searchable or accessible history limit can mean that older discussions fall outside the free history window. That does not necessarily mean the underlying messages have been permanently deleted. A developer returning from leave may nevertheless struggle to retrieve a decision made just a few weeks earlier.

Practical tip: Before choosing a free plan, estimate the number of messages your team sends each day—not just the number of employees. If you depend on old decisions, document important outcomes separately and verify the platform’s history, export, and upgrade rules.

What would a 25-person startup spend over three years?

To compare costs fairly, we use 25 paid users for 36 months, annual-billing list prices in US dollars, and no promotional discounts. We assume team size and prices remain constant. Taxes, additional storage, optional add-ons, and future price changes are excluded. The free plans are all $0 in software subscription fees for 25 users, but their limitations differ. The paid comparison illustrates optional upgrades, not a requirement to pay at this team size.

Platform / plan Monthly cost for 25 Three-year total
Slack Free $0 $0
Pumble Free $0 $0
Zoho Cliq Free $0 $0
Zulip Cloud Free $0 $0
Zoho Cliq Standard (up to 25 users) $16.20 $583.20
Pumble Pro ($2.49/user) $62.25 $2,241.00
Zulip Cloud Standard ($6.67/user) $166.75 $6,003.00
Slack Pro ($7.25/user) $181.25 $6,525.00

These figures compare published entry-level paid plans, not identical feature bundles. Check the features your team needs before selecting a plan.

For perspective, the difference between Slack Pro and Pumble Pro at these prices is $4,284.00 over three years for 25 users. That money could matter to a bootstrapped startup—but only if Pumble supports the tools and processes the team actually uses.

Which Slack alternative should your startup choose?

The best Slack alternatives for startups solve different communication problems. Match the platform to your team’s actual working style rather than choosing only by price.

  • Choose Slack when established integrations, familiar workflows, and collaboration with external partners justify its cost. Be especially careful with the free history window.
  • Choose Pumble when keeping searchable project conversations without paying is the highest priority and 10 GB of free storage is sufficient.
  • Choose Zoho Cliq when free group meetings and generous storage are important, or when its fixed-price Standard tier suits a growing team.
  • Choose Zulip Cloud when discussions are complex, asynchronous, and easier to manage as clearly named topics. Consider the 10,000-message and 5 GB free limits.

Before committing, run a short pilot with real projects: create channels, invite the team, connect essential tools, upload typical files, and test how easily someone can retrieve a decision from weeks earlier. The interface matters, but finding important information later matters more. If your startup is also building its online presence, see our firsthand guide to launching a business website for another example of practical software choices.

What about Discord as a free Slack alternative?

Discord deserves a brief mention. It offers text channels, threads, voice communication, screen sharing, and searchable discussions. For gaming studios and creative groups, those features can be attractive.

However, Discord was developed primarily around communities, not the full administration and workflow needs of a business workspace. That difference is relevant in practice. For example, TechTitans, a platform connecting technology education and creative learning, has used Discord for its creative community. You can also read our overview of the TechTitans learning platform for background on its educational focus. Organizing a community around shared interests is a different challenge from maintaining an internal company’s long-term record of project decisions.

If your startup is primarily a creative or gaming community, Discord may be worth exploring. If your main requirement is structured internal workplace communication, start with the four cloud services compared above.

Final thoughts: free today, useful three years from now?

Ultimately, the best Slack alternatives for startups are those that preserve access to decisions and fit established workflows as the business grows.

For a 25-person startup, the best Slack alternative is not necessarily the product with the most features or the lowest advertised price. It is the service that keeps conversations organized, preserves access to important decisions, supports the team’s everyday workflow, and remains affordable as activity grows.

Our practical takeaway: Pumble offers the clearest free-history advantage; Zoho Cliq stands out for storage and meetings; Zulip Cloud rewards teams that value topic-based organization; and Slack remains a strong benchmark with a meaningful free-plan history trade-off. Test the contenders with your own team before making a long-term commitment.

Official sources and pricing references

Do guest posts still help SEO? Illustration showing guest posting, backlinks, expertise, and website visibility.

Do Guest Posts Still Help SEO? What Website Owners Should Know

When I started accepting guest articles on TechEduCareer, I quickly realized that guest posting means very different things to different people. Some contributors want to share expertise with a new audience. Others are mainly interested in placing a link. As a website owner, I have to decide which submissions genuinely deserve space on the site.

That experience led me to a question worth exploring: do guest posts still help SEO, or have they become more trouble than they are worth? My answer is that a good guest article can still be valuable—but I would never judge its value by the backlink alone.

Guest posting is not automatically an SEO problem

A guest post is an article written by someone other than the site’s regular editorial team and published for its readers. That can be entirely legitimate. A developer might explain a tool they built. A recruiter might share lessons from hiring technical specialists. A cybersecurity practitioner might walk through a real-world security problem.

The important distinction is why the article exists. Google’s spam policies address links intended to manipulate rankings, including certain paid links and large-scale article campaigns built primarily for link placement. They do not say that every guest contribution is spam.

For me, the first test is simple: would this article still be useful if the outbound link were removed? If the answer is no, the submission probably needs another look.

What can a guest article contribute beyond a backlink?

There are several reasons I might welcome an outside contributor to TechEduCareer:

  • Specialized knowledge. Someone working directly in a field can bring examples and expertise that our editorial team does not have. One example on our site is a contributor’s practical guide to preparing for a data analyst interview.
  • Different perspectives. A thoughtful contribution can challenge assumptions and introduce readers to another approach.
  • Useful original material. Screenshots, demonstrations, case studies and firsthand lessons can make an article more valuable than a generic overview. Our guest contribution on building an educational platform and a fact library illustrates a specific perspective rather than a generic overview.
  • Relevant audiences. A contributor may share the finished article with people who are genuinely interested in the topic.
  • Editorial relationships. Good contributors can become recurring sources of expertise, rather than one-time link seekers.

None of those benefits guarantees better search rankings. They do, however, give a guest article a reason to exist independently of SEO.

The question I ask before accepting a guest post

When reviewing a pitch, I try to think like a reader rather than a link builder. Does the proposed article solve a real problem? Does it fit our focus on technology, education, digital tools and careers? Does the author have a credible reason to write about the subject? Is there something concrete we can verify?

A headline such as “The Ultimate Guide to Technology” tells me very little. A proposed article explaining how a team solved a specific technical challenge, with examples and limitations, gives me much more to work with.

I also look for unnecessary promotional language. An article can mention a company or product where it is genuinely relevant, but it should not read like an advertisement disguised as education.

Our guest contribution policy—and what it does not guarantee

At TechEduCareer, we established editorial requirements to make submissions easier to evaluate. We generally expect at least 700 words, clear language, an appropriate level of originality, disclosure of AI assistance, and content that meets our quality checks. We use a Grammarly score of 80 or higher as one screening signal, not as a substitute for editorial judgment or factual verification.

Our contribution guidelines have also allowed one contextual body link and a nofollow author-bio link. But I want to be clear about an important point: an editorial link allowance is not an SEO entitlement. Every link still needs to be assessed for relevance, commercial relationships and compliance with search-engine guidance.

We should not promise that a contributor will receive ranking benefits, nor assume that a link is safe simply because it appears inside an otherwise useful article. If a placement is paid, sponsored or otherwise part of an advertising arrangement, the link should be appropriately qualified, generally with rel="sponsored" or rel="nofollow", as explained in Google’s outbound-link guidance. Links designed primarily to manipulate rankings can be problematic even without a straightforward cash payment.

Are dofollow links allowed in guest posts?

The term “dofollow” is commonly used to describe an ordinary link without a qualifying rel attribute. It is not a special HTML attribute.

A normal editorial link can be appropriate when an editor independently chooses to cite a genuinely useful source. The concern arises when links are inserted, exchanged or compensated primarily to pass ranking credit. That is why I do not think the right question is “How many dofollow links can a guest author get?”

A better question is: Does this link help the reader, and is there any relationship that requires us to qualify it? If the destination adds no meaningful context, we can remove it. If the relationship is commercial, we should label it appropriately.

AI-written guest articles need human accountability

AI tools can help authors outline, edit and clarify their writing. I use AI in my own publishing workflow, so I do not treat AI assistance as an automatic reason to reject a submission.

What matters is whether the author takes responsibility for the result. Are the claims accurate? Are sources credible? Are examples real? Does the article add information beyond what a generic AI response could produce?

Google’s people-first content guidance focuses on helpfulness, originality and trustworthiness rather than a simple rule that all AI-assisted content is bad. Its spam policies also address scaled content abuse when large amounts of content are produced primarily to manipulate rankings.

For our site, disclosure helps us understand the writing process. It does not replace checking the substance.

Warning signs that make me cautious

Some guest-post pitches deserve extra scrutiny. I become cautious when the proposed topic is unrelated to our audience, the author insists on exact-match commercial anchor text, the article repeats information available everywhere, or the sender treats publication as a guaranteed link transaction.

Another warning sign is a request to add an unrelated link to an existing article without explaining why readers need it. Even when the surrounding content is well written, the link itself can undermine editorial integrity.

That does not mean every commercial contributor is acting in bad faith. It means the editorial purpose, link relationship and reader benefit must be clear.

How I would measure whether guest posts are worthwhile

If we want to know whether guest contributions help TechEduCareer, I would track more than the number of articles published or backlinks exchanged. As I discuss in our practical website promotion checklist, discovery and audience engagement involve more than acquiring links. Useful measurements include organic search impressions and clicks, engaged visits, referral traffic, internal-link clicks, and whether the article continues attracting readers over time.

I would also look at qualitative outcomes: Did the contributor introduce a valuable topic? Did we have to spend hours correcting factual problems? Did readers get something they could actually apply?

Importantly, a rise in traffic after publishing a guest article does not prove the guest post caused it. Search visibility depends on many factors, and a small website can see substantial variation from week to week. Our guide to improving Google and Bing visibility without ads explores that broader picture. We should compare trends carefully and avoid promising results that the data cannot establish.

What website owners can do before pressing Publish

My practical checklist is straightforward: verify the contributor’s claims and sources, confirm the article fits the site’s audience, review originality, inspect every outbound link, clarify any sponsorship or compensation, check the author bio, and make sure the article reads naturally on mobile.

I would also edit the headline and introduction as carefully as I would for an article written internally. Accepting a guest contribution does not mean giving up editorial control. Once it appears on TechEduCareer, readers associate its quality with our website.

So, do guest posts still help SEO?

They can support a healthy publishing strategy, but they are not a shortcut to rankings. A useful contribution may attract readers, earn natural references and strengthen the depth of a site’s coverage. A weak article written mainly to insert a link can waste editorial time and create unnecessary risk.

My view after working with guest contributors is simple: I would rather publish one genuinely useful outside perspective than ten articles whose main purpose is to carry backlinks.

For TechEduCareer, the goal is not to become a guest-post marketplace. It is to build a trustworthy resource where contributors have something worthwhile to teach and readers have a reason to return.

Official resources

Custom WordPress plugin case study showing TechEduCareer Social Publisher, Discord and Mastodon integration testing.

We Built Our Own Lightweight WordPress Plugin Instead of Adding Another One. Here’s What Happened.

Every time I want to add a new feature to my WordPress website, I face a familiar decision: should I install another plugin, subscribe to an external service, or build something myself?

Installing a plugin is usually the easiest option. Search the WordPress directory, compare a few choices, click Install, configure the settings, and hope everything works as expected. But what if I only need two or three features from a plugin that offers twenty?

That question became particularly relevant while working on TechEduCareer, where we publish articles about technology, digital skills, cybersecurity, AI, and practical online tools. Our latest challenge was straightforward: automatically share new WordPress articles to Discord and Mastodon without adding an unnecessarily complicated publishing system. Instead of immediately installing another social media plugin, we decided to experiment with a different approach. We built our own.

The problem: We needed publishing automation, not an entire marketing platform

TechEduCareer already had a social media publishing workflow. Some platforms were handled through Metricool, others manually, and Telegram through its own WordPress integration. What remained was a simple requirement: when a new article went live, we wanted it to appear on our Discord channel and Mastodon profile.

We didn’t need advanced campaign management, social listening, analytics dashboards, or a dozen additional integrations. We needed automatic publication for new and scheduled posts, manual sharing for existing articles, duplicate prevention, independent platform controls, delivery history, and secure handling of credentials.

This was a good opportunity to test whether a purpose-built WordPress plugin could solve a narrowly defined problem. The experiment would also show whether a focused solution was easier to manage than a feature-heavy publishing plugin.

Can a WordPress plugin really be that small?

Yes. According to the official WordPress Plugin Developer Handbook, a basic plugin can begin with a PHP file containing a valid plugin header. WordPress provides hooks and APIs for interacting with posts, settings, metadata, and external services. We could use existing WordPress functionality to detect publication, retrieve post information, store settings, and contact social platforms.

A lightweight plugin is not necessarily a plugin with the fewest lines of code. For us, lightweight meant a focused feature set, minimal unnecessary dependencies, and no large external framework just to publish an article. It did not mean skipping security checks, logging, or error handling. We have not benchmarked our plugin against commercial alternatives, so we are not claiming a measured performance improvement.

Building TechEduCareer Social Publisher

We started with Discord. The initial version configured a Discord webhook, provided a connection test, and allowed us to select an existing published article and share it manually.

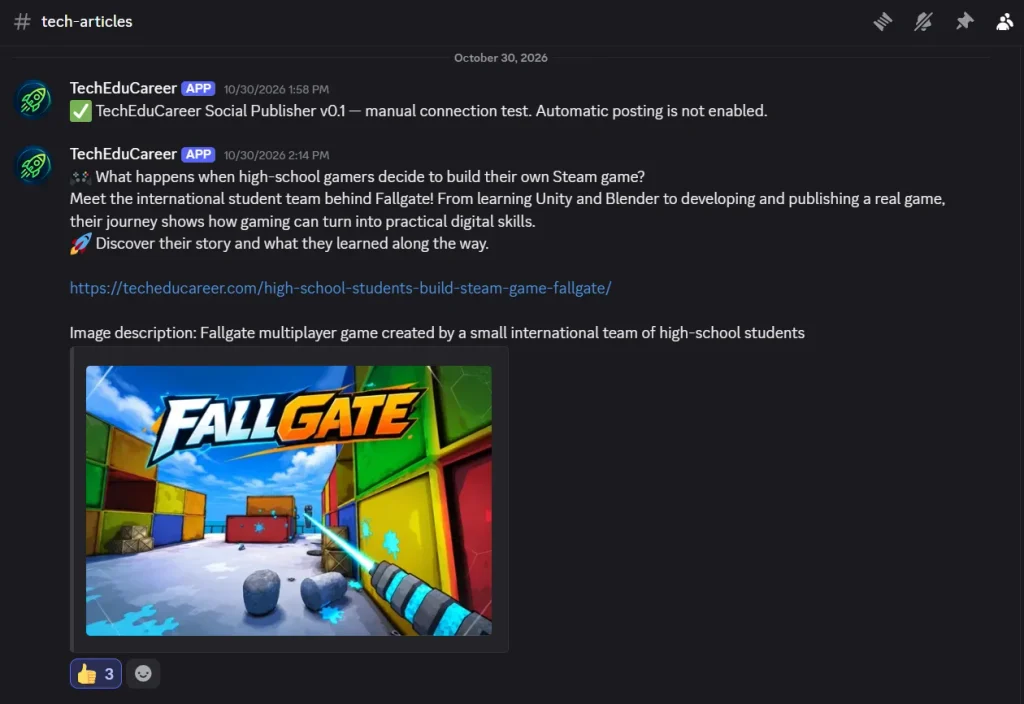
Our first real test used an article about a high-school team that created a game for Steam. The article appeared in Discord with its message, link, and featured image. That was our first milestone.

TechEduCareer article shared to the Discord #tech-articles channel, showing the Fallgate story, article link, and featured image.

Once manual publishing worked, we added automatic publishing. WordPress provides a hook called transition_post_status, which can detect when an article changes from a draft or scheduled state to published. We used that mechanism to publish only when an article became public for the first time.

Without this check, editing an existing article could unintentionally trigger another social media post. We also added delivery records and duplicate checks. The first automatic Discord test succeeded, and updating the article afterward did not publish another copy.

Adding Mastodon was a different challenge

Discord was relatively straightforward because we could use a webhook. Mastodon required integration through its API and an access token. We began with a limited-permission application, then tested whether WordPress could publish a public status. Once the connection worked, we added manual article sharing.

Initially, we experimented with uploading featured images to Mastodon, including image descriptions. Then we noticed something interesting: when we manually pasted a TechEduCareer article URL into Mastodon, the platform could generate a compact preview card automatically.

Why upload the same image separately if a link preview already gives readers a useful introduction? We simplified the automatic workflow to send the article title, a short description, and the URL. Mastodon could then retrieve the article metadata and generate its own preview card. This removed the need for automatic media uploads. The trade-off is that Mastodon controls link preview appearance, and a card is not guaranteed for every URL.

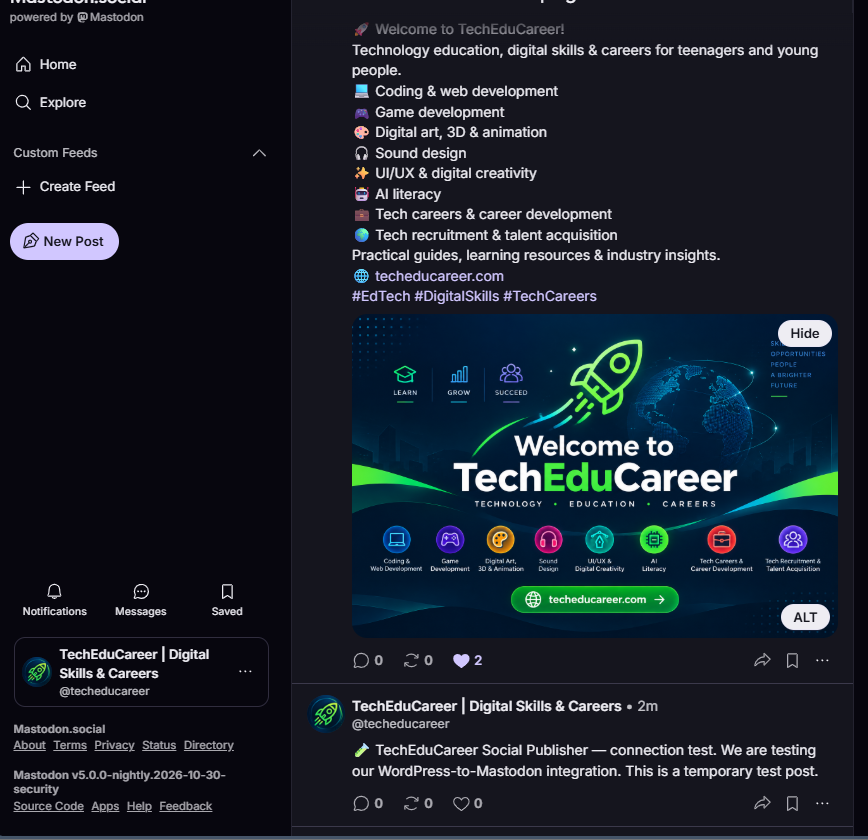
Our Mastodon connection test succeeded: the plugin reported that Mastodon accepted a public test status, and we verified the message on our profile. The screenshot below captures both the WordPress confirmation and the actual Mastodon test post. It demonstrates that the API connection worked, rather than claiming the final article formatting was perfect.

WordPress Social Publisher confirms a successful Mastodon connection test beside the published test message on Mastodon.

Our first automatic Mastodon test revealed a bug

We published a temporary WordPress article to test automatic Mastodon posting. The article appeared on Mastodon, so the API integration worked—but the message displayed literal backslash-n characters instead of proper line breaks. A successful API response had not guaranteed a correct user-facing result.

We corrected the message construction, updated the plugin, and tested again. This time, the title, description, and URL appeared on separate lines, with a compact link preview. The lesson: inspect what was actually published, not just the API response.

Testing duplicate prevention

After successfully publishing the second temporary article, we opened it in WordPress, added another sentence, and clicked Update. Refreshing Mastodon showed no new post. That confirmed the expected behavior in our test: editing an already published article did not trigger another announcement.

This matters because blog posts are frequently updated to fix typos, improve explanations, or add links. Routine edits should not flood social channels with duplicates.

One dashboard for two publishing destinations

As the project evolved, the separate Discord and Mastodon sections became inconvenient. When managing a blog, I think in terms of an article and where it has been published—not two unrelated integrations. So we introduced a shared article selection area and one Social Publishing History table.

Each article now has independent Discord and Mastodon statuses. We also retained separate automatic-posting switches, which proved useful when we temporarily disabled Discord to test Mastodon in isolation.

WordPress custom social publisher dashboard with separate Discord and Mastodon delivery status columns.

What about security?

Building your own WordPress plugin means accepting responsibility for its security and maintenance. For our implementation, we used permission checks, nonce verification for administrative actions, input validation, and output escaping. Credentials were stored in WordPress settings rather than displayed on public-facing pages.

These precautions do not automatically make custom code secure. WordPress documentation emphasizes validating and sanitizing inputs, escaping outputs, checking permissions, and protecting sensitive actions. A production plugin should also be reviewed for error handling, unexpected API responses, credential exposure, compatibility, and recovery behavior.

For social publishing, uncertain network outcomes deserve special attention: a request may reach the platform even if WordPress does not receive confirmation. Blindly retrying can create duplicate posts, so our implementation takes a conservative approach to uncertain outcomes.

What we learned about scheduled publishing

WordPress scheduled posts use WP-Cron, which is not a continuously running system scheduler. On typical installations, due tasks are checked when the site receives requests. Publication may therefore occur later than scheduled on a low-traffic website. Our plugin reacts when WordPress actually transitions the article to Published; it does not run an independent scheduler.

Should you build your own plugin or install an existing one?

I would not recommend custom development for every WordPress feature. Established plugins can offer mature integrations, ongoing maintenance, documentation, compatibility, and support. For complex payment, authentication, backup, or security features, those advantages can be particularly important.

Custom development makes more sense when requirements are narrow, well understood, and realistic to maintain. Existing plugins often win when you need many features or vendor support; custom plugins can offer tighter control over a unique, focused workflow. The real question is whether maintaining the code makes sense over time.

The production test changed our decision

After numerous connection, formatting, and duplicate-prevention tests, our first real scheduled article was published automatically to both Discord and Mastodon. The delivery history confirmed both requests succeeded. But successful delivery was not the same as a satisfying publishing experience.

Discord initially failed to show the article image as expected. We replaced the featured image with a WebP version, reset the article’s delivery record, and shared it manually again. The image then appeared correctly. We also removed an unnecessary visible image-description line from Discord messages, leaving a cleaner post with the article link and preview.

Mastodon was different. Although its API accepted our posts, its automatically generated link card cropped the featured image and repeated information already present in the message. We experimented with shorter text and the optional image-upload setting, but the result still wasn’t the presentation we wanted. When posting directly in Mastodon, we could control the final appearance more comfortably.

So we made a deliberate choice: remove Mastodon from our custom plugin and handle those posts manually, alongside LinkedIn and X. We kept Discord automation because it solved a real problem and worked reliably for our workflow. The plugin became a focused, Discord-only publisher, with manual sharing, automatic publication, duplicate prevention, and a per-article history reset. Resetting a record does not delete a social post; we handle that separately.

Regardless of how many tests we performed, we came to a simple conclusion: more automation doesn’t necessarily mean a better publishing experience. The purpose of automation is not to connect every possible platform. It is to save time without sacrificing the quality of what readers actually see.

The bigger lesson: Build what you need, not everything you can

The most valuable part of this project wasn’t writing PHP or connecting another API. It was deciding what not to build. We didn’t need to recreate an entire social media management platform or maintain an integration merely because we had managed to make its API work. A simple delivery table was useful; keeping every platform inside our plugin was not.

AI-assisted development made it easier to prototype and refine the implementation, but it didn’t remove the need for human decisions, real testing, or maintenance. If you’re considering a small WordPress plugin, start with one clearly defined problem. Build the smallest useful version, test it in the actual environment, expect mistakes, fix them, and keep the features proportional to the problem.

Sometimes, the most useful WordPress plugin isn’t the one with the longest feature list. It’s the one that does exactly what your website needs—and nothing more. Our final decision to keep Discord and publish to Mastodon manually was part of the development process, not a failure of it.

Official resources

Comparison of six free online PDF mergers tested for file uploads, privacy, and document quality.

We Tested 6 Free Online PDF Mergers: Which Ones Upload Your Files?

Six free PDF mergers. A consistent five-page test. One browser’s Network panel. We tested what happens to your files when you merge PDFs online, including upload behavior, deletion controls, output size and usability.

Merging PDFs sounds simple: select your files, arrange them, click Merge, and download. But do your documents leave your computer? Can you delete them from the provider’s servers? And do different tools produce comparable results?

Rather than rely on marketing claims, TechEduCareer tested five services in October 2026: iLovePDF, PDF24, Smallpdf, Adobe Acrobat and PDFTool.org. In November 2026, we extended the comparison with an independent test of PDF Jetty following a suggestion from its team.

How we tested the PDF mergers

For a consistent comparison, we created two synthetic documents containing no personal information: File A (two pages, 28,371 bytes) and File B (three pages, 29,517 bytes). The expected merged sequence was A1 → A2 → B1 → B2 → B3.

All six services were evaluated using the same five-page A1–B3 test structure. The November follow-up used newly prepared synthetic PDFs; output sizes should therefore be treated as observations, not a controlled compression ranking. Each test used Microsoft Edge InPrivate without signing in. We monitored requests in Developer Tools → Network and checked downloaded results for page count, order, extractable text, output size and watermarks. Manual deletion was also tested where offered.

Scope: Network observations can show transfers and API responses. They cannot establish permanent erasure from servers, backups or replicas. Our small synthetic PDFs are not a comprehensive performance or quality benchmark.

Comparison table: six free online PDF mergers

Tool Output size PDF uploaded? Manual deletion evidence Result
iLovePDF 30.8 KiB Yes DELETE request, HTTP 200 Passed
PDF24 53.3 KiB Yes eraseJob request, HTTP 200 Passed
Smallpdf 5.1 KiB Yes UI confirmation; API not identified Passed
Adobe Acrobat 123.7 KiB Yes No anonymous deletion control identified Passed
PDFTool.org 29.6 KiB No upload observed Not applicable to apparent local workflow Passed
PDF Jetty 2.5 KiB No upload observed Not applicable to apparent local workflow Passed

All six tools were evaluated using the same five-page test structure; each output contained the correct five pages and searchable text. Output sizes are reported for their respective test files and should not be interpreted as a like-for-like compression benchmark. Smaller size does not necessarily mean better visual quality.

1. iLovePDF: simple merging and observable deletion

iLovePDF merged both files without registration or payment. Its output was 31,545 bytes, preserved the five-page sequence and remained searchable.

The Network panel showed two successful POST uploads to its API followed by a server-side processing request. After clicking Delete it now, the browser sent an HTTP DELETE request to its task API and received HTTP 200. A later request could no longer access that task.

This supports that the deletion operation was accepted; it does not independently prove erasure of every stored copy. The provider states that files are automatically deleted within two hours.

iLovePDF PDF merger showing automatic file deletion countdown and browser network activity

2. PDF24: free features and a clear erase operation

PDF24 offered additional controls, including page organization and bookmark options. The Network panel recorded upload requests and a separate joinPdf operation. The output was 54,603 bytes and passed our page-order and text checks.

Clicking Erase produced an eraseJob POST request with HTTP 200. PDF24’s interface said files would otherwise be deleted automatically after one hour. The visible API acknowledgment is useful evidence, though not a storage audit.

PDF24 PDF merger showing file deletion confirmation and successful HTTP 200 eraseJob request

3. Smallpdf: the smallest output

Smallpdf produced a strikingly small result: 5,225 bytes, with five pages and extractable text. Its interface was polished, though individual-page organization was marked as a Pro feature.

The browser obtained an upload URL and sent PDF data via signed URLs to Cloudflare R2 object storage, confirming remote transfer. After merging, Smallpdf offered manual deletion with a dialog promising permanent removal. The document disappeared from the interface, but we did not identify an explicit deletion API request in the captured log. That is not evidence that deletion failed.

Smallpdf describes automatic deletion after one hour for ordinary free-tool processing, with exceptions for some saved, shared and account-based workflows.

Smallpdf PDF merger showing two uploaded test files and browser developer tools confirming a successful PDF upload to Cloudflare R2 storage.

4. Adobe Acrobat: successful but heavier in our test

Adobe Acrobat redirected to its Acrobat web application and generated substantial page-loading and analytics activity. Cloud-document resource creation was visible before merging. Despite console warnings and errors, the merge succeeded without requiring an account.

The resulting PDF was 126,664 bytes—by far the largest output in our test. All five pages remained in order with extractable text. Adobe’s anonymous interface said files would be deleted unless saved through sign-in, but did not show us a manual deletion option or an exact retention period.

Our experience felt slower and more complicated than the other tools, but we did not conduct a controlled speed benchmark.

Adobe Acrobat online PDF merger showing the completed five-page test document and Download button, alongside browser developer tools displaying network requests.

5. PDFTool.org: no document upload observed

PDFTool.org claimed to process documents on the user’s device. During file selection and merging, we monitored all network requests. Unlike the four services above, we did not observe a transfer of the PDF contents.

Clicking Merge automatically downloaded a valid 30,341-byte PDF with the correct page sequence and searchable text. Because no separate success or download screen appeared, we initially thought the button had failed. That small usability issue is worth noting.

The observed network behavior is consistent with browser-local processing and makes PDFTool.org particularly interesting for privacy-conscious users. However, it is not a formal code or security audit.

PDFTool.org merging two PDF test files, with browser developer tools showing network activity and no observed PDF file uploads during processing.

6. PDF Jetty: no document upload observed in our follow-up

PDF Jetty was added to our comparison on November 11, 2026, after its team suggested we run our five-page A1–B3 test. We evaluated the free merger in Microsoft Edge InPrivate, without creating an account or paying.

The tool merged the two PDFs in the expected A1 → A2 → B1 → B2 → B3 order. We examined the downloaded five-page document and confirmed that all text markers remained extractable rather than being flattened into images.

PDF Jetty online PDF merger showing two test documents alongside Microsoft Edge Developer Tools Network panel used to monitor file uploads.

With the Network panel set to All and Keep log enabled, the captured requests included PDF.js worker resources and small api.php ping requests (HTTP 204). We did not observe a request transmitting either PDF document during file selection or merging. This is consistent with browser-local processing, but it is not a formal security or storage audit.

Our two mostly text-based inputs totaled approximately 53.6 KB; the merged PDF was 2.54 KB, approximately 95.3% smaller. These synthetic PDFs contained almost no graphics, so the result should not be taken as a typical compression rate for image-heavy or complex PDFs. The tool offered a clear download dialog and completed our basic checks successfully.

Result: Passed. No PDF-content upload was observed in the captured Network requests.

Why browser-local processing matters

Cloud-based PDF mergers can use encryption and strict deletion policies, but their workflows still transfer document contents to remote infrastructure. Browser-local tools can avoid that transfer entirely when the processing is genuinely performed on-device.

Free, encrypted and browser-local are three different properties. A service can be free and encrypted while still uploading documents. Conversely, a local tool still deserves scrutiny for scripts, analytics and unexpected network behavior.

How to check whether a PDF merger uploads files

  1. Open the tool in Edge or Chrome using synthetic, non-sensitive test PDFs.
  2. Press F12 and select Network.
  3. Enable Keep log or Preserve log and clear existing requests.
  4. Select your PDFs, perform the merge and keep the request log.
  5. Inspect POST and PUT requests, destinations, request payloads and transferred sizes.

Do not search only for the word “upload”: a service may use signed cloud-storage URLs with unrelated filenames. Absence of an obvious upload is useful evidence but cannot conclusively establish that no file data ever left the browser.

What does clicking Delete actually prove?

With iLovePDF and PDF24, we observed deletion-related requests acknowledged by their servers. Smallpdf displayed a deletion confirmation and removed the document from the interface, but its deletion API was not identified. Adobe promised automatic deletion for anonymous files but offered no manual control we could find.

These differences concern observable evidence, not a definitive ranking of the providers’ internal deletion reliability. No browser test can prove that every backup or replica has been erased.

Which free PDF merger should you choose?

Minimizing document uploads: PDFTool.org and PDF Jetty both completed our tests without an observed PDF-content transfer. These results are consistent with browser-local merging, though neither test was a formal security audit.

Feature-rich free cloud option: PDF24 offered useful controls and an observable erase request.

Simple cloud workflow: iLovePDF combined a simple experience with a clear manual deletion option.

Output size: PDF Jetty produced a 2.54 KB PDF in our November follow-up, while Smallpdf produced the smallest output among the original October tests. Because the test files were recreated for the follow-up, these sizes should not be treated as a direct compression ranking.

Already using Adobe? Acrobat completed the task successfully, but its anonymous workflow was less convenient for us.

Final thoughts

All six services passed our basic merging tests, but the privacy and usability differences were real. Four visibly transferred document contents to remote services; PDFTool.org and PDF Jetty completed their respective tests without an observed PDF upload. Output sizes and deletion controls varied, and the November follow-up used recreated synthetic PDFs.

The most useful question isn’t simply “Does this PDF merger work?” It’s also “What happens to my files while it works?”

At TechEduCareer, we believe free tools should explain their limits and data handling clearly. That principle also guides the browser-based utilities in our Tools Hub.

Frequently Asked Questions

Is it safe to merge PDF files online?

It depends on the service and your documents. Cloud-based mergers receive document contents; genuine browser-local tools can avoid transferring them. Use extra caution with sensitive files.

Which PDF merger kept our test files in the browser?

PDFTool.org and PDF Jetty each completed our tests without an observed PDF upload, consistent with browser-local processing. Neither test was a formal security audit.

Do online PDF mergers delete uploaded files?

Several providers publish retention policies. We observed successful deletion API responses from iLovePDF and PDF24, but could not independently inspect their underlying storage systems.

Does a smaller merged PDF mean better quality?

Not necessarily. Compression, fonts, metadata and internal PDF structure all affect size. All six outputs passed our basic text and page-order checks.

Can I merge PDFs without registering?

Yes. All six tools completed our basic tests without requiring an account.

Testing conducted by TechEduCareer in October and November 2026 using synthetic PDFs and Microsoft Edge Developer Tools. The November PDF Jetty follow-up used newly prepared files with the same five-page test structure. Results describe the tested workflows and may change as providers update their services.

AI-assisted business website creation featuring the real Vivaccess homepage on a laptop, with purple branding and a modern workspace.

How We Built and Launched a Real Business Website with AI, Porkbun, and Cloudflare

From domain registration to deployment, business email, SEO, and real-world verification: a firsthand case study.

We built a business website with AI and launched it in just five hours—from domain registration to a live, publicly accessible site. With ChatGPT assisting throughout the process, we registered the domain through Porkbun, deployed the website using Cloudflare Pages, configured DNS and HTTPS, and verified that the website was publicly accessible. The five-hour milestone refers to building and launching the website—not completing every subsequent SEO or search-engine indexing task.

We Needed a Website, Not Another AI Experiment

We needed a professional website for Vivaccess Ltd, a Cyprus-registered company offering international recruitment and talent acquisition services. This was not a fictional demo: it needed a custom domain, responsive design, secure HTTPS, a working contact channel, and a foundation for search discovery. We worked with ChatGPT to create a static website and then tackled the infrastructure needed to launch it.

1. Starting With the Business

Before selecting tools, we defined the message: Vivaccess helps businesses find specialists, source international talent, and grow teams. We chose five pages: Home, Services, About, Contact, and Privacy Policy. We wanted a premium visual identity without limiting the business to one industry or region.

2. Building the Site With AI

ChatGPT assisted with HTML, CSS, JavaScript, page structure, design refinements, and technical troubleshooting. We iterated through versions, testing desktop and mobile layouts, navigation, typography, and visual elements. AI accelerated development, but we still made the business and design decisions and checked the results.

Why not WordPress? We already knew WordPress from TechEduCareer—and had explored how to use AI to improve a WordPress website—but this project initially needed only a handful of relatively stable pages. A static website avoided a database, theme dependencies, and routine plugin updates. For a frequently updated blog or a future recruitment portal, the trade-offs could be different.

3. Registering vivaccess.eu With Porkbun

We registered our domain through Porkbun. Domain registration is not the same as hosting: a registrar manages the name, DNS directs traffic, and a hosting service serves the website. We used Porkbun for registration and Cloudflare for DNS and hosting. Domain buyers should check renewal prices, not just introductory offers.

Porkbun Domain Management dashboard showing the registered vivaccess.eu domain, renewal settings, and domain management options.

Porkbun Domain Management showing the registered vivaccess.eu domain.

4. Deploying With Cloudflare Pages

We deployed the static files through Cloudflare Pages, using a project address at vivaccess.pages.dev before connecting vivaccess.eu. We configured DNS, HTTPS, and a permanent redirect from www.vivaccess.eu to the non-WWW domain. We tested the redirect rather than relying solely on a successful-looking dashboard.

Cloudflare Workers & Pages dashboard showing the Vivaccess website deployment, connected domains, and usage statistics, with sensitive account details hidden.

Vivaccess website deployed with Cloudflare Pages.

5. Business Email and Contact Form

We configured contact@vivaccess.eu using Cloudflare Email Routing to forward incoming messages to Gmail, then tested delivery. Forwarding is not a full hosted mailbox or outbound email service; those require separate arrangements if needed.

Because the website had no application backend, we integrated Web3Forms for contact submissions and tested the form. Third-party form processing also raises privacy questions, so our privacy notice and service safeguards need appropriate review.

One apparent bug turned out to be a local computer issue: clicking the email link did not open a mail app, although inspection showed a correct mailto: link. Browser or operating-system settings can affect what users experience.

6. SEO Is More Than Making a Website Live

We checked the five pages’ titles, descriptions, headings, and internal navigation. We added canonical URLs, Open Graph metadata, a 1200 × 630 social preview image, Twitter/X card metadata, and Organization JSON-LD describing Vivaccess and linking to its LinkedIn company page.

We also configured Google Search Console and Bing Webmaster Tools and submitted a five-page XML sitemap at vivaccess.eu/sitemap.xml. Google initially reported a sitemap fetch/read issue, even though the sitemap was accessible and the homepage passed live URL inspection. We chose to monitor processing rather than immediately change working infrastructure. A submitted sitemap is not a guarantee of indexing or rankings.

7. Verifying the Launch With PowerShell

We did not stop at the deployment success screen. We checked that the live homepage actually contained the new metadata:

curl.exe -sL https://vivaccess.eu/ | Select-String -Pattern 'canonical|og:image|og:url|twitter:card|application/ld\+json'

Then we checked every main page and the social image:

$urls = @(
  "https://vivaccess.eu/",
  "https://vivaccess.eu/services",
  "https://vivaccess.eu/about",
  "https://vivaccess.eu/contact",
  "https://vivaccess.eu/privacy",
  "https://vivaccess.eu/vivaccess-social.jpg"
)
foreach ($url in $urls) {
  $result = curl.exe -s -L -o NUL -w "%{http_code} %{content_type}" $url
  Write-Host "$result  $url"
}

All six resources returned HTTP 200. The five pages reported text/html; charset=utf-8; the preview image reported image/jpeg. That confirmed public accessibility at the time of testing, though not every possible browser interaction or SEO outcome.

PowerShell verification showing HTTP 200 responses for five Vivaccess website pages and the social preview image.

All six Vivaccess resources returned HTTP 200.

8. What Did It Cost?

Our stack combined paid domain registration with free-tier or free services: Porkbun for the domain, Cloudflare Pages and DNS for hosting and routing, Cloudflare Email Routing for incoming messages, Web3Forms for the contact form, and free Google and Bing webmaster tools. ChatGPT access may have a subscription cost. We will add verified actual amounts and applicable service limits before publication; free tiers and prices can change.

9. What AI Did Well—and What Still Needed Us

AI helped generate code, refine the design, explain DNS and hosting concepts, suggest SEO changes, and prepare test commands. Our earlier ChatGPT and WordPress MCP case study explores another way AI can support practical website work. But humans still needed to choose the positioning, assess the design, configure accounts, review privacy implications, and verify that the deployment and email actually worked.

Next time, we would define the full page structure and technical checklist earlier, plan SEO metadata before the final deployment, document tests as we go, and address privacy requirements alongside implementation.

Final Thoughts

We ended with a real business website—not just a mockup—at vivaccess.eu, with its own domain, HTTPS, incoming business email, a tested contact form, and an SEO foundation. Search indexing and compliance review still require follow-up.

AI can help you build a website. Verifying, launching, and maintaining it is what makes it a business asset.

Editorial note: This firsthand case study is not sponsored by Porkbun, Cloudflare, Web3Forms, or other providers mentioned. Add actual costs and selected screenshots before publishing.

Student gaming project portfolio workspace featuring game design software,

The work behind a school gaming project belongs in the portfolio

A highlight reel tells you what made the cut. It doesn’t tell you who planned it, where the first idea failed or what the student changed after someone else looked at it. If we want gaming and media projects to count as learning, we need to see some of that work, not just the final upload.

When I ask what a student did on a project, “I made the video” isn’t quite enough. Did they choose the clips, sort out the sound, write the captions, check permissions? A useful portfolio answers those questions with a few pieces of evidence. It gives the designer, writer or event planner something to show too, even if they never played in the match.

Start with the brief

I would give students a brief they can fit on half a page: what they are making, who it is for and where it will appear. A graphic for a classroom screen can afford small details that will vanish on a phone. A public stream brings different rules about names, images and music. Put those limits in the brief before anyone starts making things.

Then leave room for the student’s own choices. If the brief reads like instructions for every colour and cut, there is little left to explain in the portfolio.

Save one early version

Keep an early draft. It might be a rough video sequence, a hand-drawn graphic or the first running order for an event. Ask the student to add a note about what they were trying to do and what was still bothering them. That is enough to make a later change visible.

Nobody needs a folder full of nearly identical screenshots. Pick one version that shows the starting point and move on.

Record feedback and a decision

Now put the draft in front of someone else. If a classmate cannot read the date on a thumbnail at phone size, record that. If a teacher spots a missing technical check in the event schedule, record that too. The portfolio needs the comment and the student’s decision about it. “I made the date larger so it worked on a phone” is useful evidence. “I improved the design” could mean anything.

Sometimes the student will keep the original choice. That’s fine if they can explain why it still serves the audience. Feedback is a conversation, not an instruction to change everything.

Show the revision

Show the old and new versions side by side. Point to a change that matters: clearer audio, a simpler graphic, an event plan that gives the team time to test its stream. If a student removed a song because they could not use it, include that decision as well. These are small, concrete things a teacher can actually discuss with them.

The work behind a school event is wider than the match itself. Someone has to plan, write, design and produce it. In the school curriculum I work on at Squid Academy, we include portfolio development among those roles. The question is the same in any school: what did this student decide, and what can they show to explain it?

Add credits and a short reflection

Credits belong in the evidence too. Ask who made each part, where images and music came from, and what permission the team had to use them. If students appear in a photo or stream, follow the school’s rules before it goes anywhere public. A private portfolio may be the right place for the work even when public posting is off the table.

I would finish with a short reflection, not a victory speech. What would the student keep? What would they change if they had another afternoon? Which choice can they now explain better? Answers that admit something was awkward or unsuccessful are often more revealing than “everything went well.”

A small example

Take a student making a thumbnail for a school tournament video. The first version looks fine on a laptop, but the date disappears on a phone. They save it, note the feedback, enlarge the type and keep the approved photo credit beside the final file. A reviewer can see the problem and the response in minutes. Without that trail, the thumbnail is simply a thumbnail.

Keep it manageable

I would not ask a teacher to learn another platform for this. A shared folder and a short document will do. Give students six prompts at the start: brief, early version, feedback, revision, credits and reflection. They can collect the pieces while they work. Ask for them after the event and they will have to reconstruct decisions they barely remember.

That also makes review less dependent on who played well or stood in front of the camera. A teacher can ask each student to talk through one decision and check it against the saved work. If the answer is vague, the next question is easy: show me the draft or the feedback that led you there. When the team did the work together, ask each student to name their own contribution and one thing a teammate changed. That tells you more than a shared slide that gives everyone the same credit.

There is no prize for the thickest portfolio. I want to see enough to understand the student’s part in the project and hear them explain a choice or two. The finished event can still be the thing everyone enjoys. The portfolio lets us notice the work that made it happen.

Editor’s related reading: From Gamers to Game Creators: How a High-School Team Built a Game for Steam.

Person discussing prompt engineering with a friendly AI assistant, comparing complex prompt formulas with simple, natural conversation.

Do You Really Need to Learn Prompt Engineering to Use AI?

You open ChatGPT, Claude, Gemini, or Qwen and type a perfectly ordinary question. It answers. Then you visit YouTube and discover dozens of tutorials explaining how to write “perfect AI prompts,” complete with formulas, expert roles, and elaborate instructions. Suddenly, asking a simple question feels like doing something wrong.

But is it? If conversational AI is built to understand natural language, why should everyday users need special training to talk to it? And what exactly are those courses teaching?

This guide takes a practical, balanced look at prompt engineering: what it is, why long prompts sometimes help, when a conversation works better, and when structured instructions really are worth learning. Along the way, we’ll draw on real TechEduCareer work involving WordPress troubleshooting, SEO, design, and AI tools.

What Is a Prompt? You’re Already Writing Them

A prompt is the input you give an AI system. It might be a question (“What is WordPress?”), an instruction (“Summarize this article”), a creative request (“Suggest three logo concepts”), or a detailed task description. Text is common, but depending on the system, an input can also include images, files, audio, and other information.

You do not need to label your message as a prompt. If you have ever asked an AI assistant a question, you have already used one. “Continue,” “Explain,” and “Make this simpler” can all be effective prompts when the preceding conversation makes their meaning clear.

There is a technical nuance: the model may also receive system instructions, conversation history, retrieved documents, or tool results. So your latest message is not necessarily the only information shaping the response. That distinction becomes important when comparing a fresh chat with a conversation that has developed over weeks.

Why Are There So Many Prompt Engineering Tutorials?

Prompt engineering is the practice of designing, testing, and refining instructions and context to obtain useful AI outputs. OpenAI’s prompt engineering documentation describes techniques for improving model responses, especially in developer workflows. It is a real discipline, particularly in software development and repeatable business workflows. Yet online explanations often blur two very different situations: a person exploring an idea through conversation and an application that must process thousands of requests consistently.

For a casual user, “Explain this error message” may be all that is needed. For a customer-support workflow that classifies messages into predefined categories and outputs machine-readable data, ambiguity can break the process. Developers may need carefully specified labels, examples, validation rules, and tests across many inputs.

Good educational material explains that difference. Less useful advice makes ordinary communication sound like a secret technical language. There is no universal formula that turns every prompt into a correct answer.

Are Longer Prompts Better? Not Necessarily

Consider “Help me improve my website.” The AI understands the words, but the task is broad. Does improvement mean loading speed, accessibility, design, search visibility, or conversion? A longer request can resolve those uncertainties: “My WordPress site uses LiteSpeed Cache. Help me investigate a JavaScript error. First identify the likely source; do not change settings until I approve.”

The second request is stronger because it provides relevant context, a specific goal, and a boundary—not because it contains more words. Padding it with impressive adjectives, irrelevant background, and repeated demands may add little value. Long prompts can also contain conflicting instructions that make the task harder.

A useful rule is to provide the information the AI cannot reasonably infer: your objective, the relevant environment, important constraints, and what a successful result would look like. If you do not know these yet, that is not a failure. You can discover them together.

Does “Act as a Professional Expert” Make AI Smarter?

Many prompts begin with “Act as a senior designer,” “You are an experienced researcher,” or “Behave like a professional editor.” This technique is often called role prompting. Anthropic’s prompting guidance emphasizes clear, direct instructions and explaining the context that a new collaborator would need. It can encourage the model to adopt a useful perspective, vocabulary, or style. A request framed around SEO may naturally emphasize search intent, indexing, and internal links.

But role wording does not grant qualifications, unlock hidden knowledge, or guarantee factual accuracy. “Act as a world-class WordPress developer” is less actionable than supplying the actual browser error, installed caching setup, and steps already tried. You can use both, but the evidence and task definition usually matter more than the grand title.

Try replacing a theatrical role with an explicit expectation: “Review this article for factual accuracy, readability, and search intent. Identify weaknesses and explain your reasoning.” That tells the AI what to evaluate and how to respond.

The Alternative: Build the Answer Through Conversation

Not every project begins with a complete specification. When designing a logo, you may not know the final shape, colors, typography, or proportions until you see alternatives. A giant upfront prompt forces you to predict decisions you have not made. Iterative prompting takes a different path: begin with a direction, inspect the result, react, and refine. Google’s Gemini prompt design guide likewise describes iteration and breaking complex tasks into smaller steps.

  • “I need a logo, but I haven’t decided on a visual direction.”
  • “Let’s explore simple geometric symbols.”
  • “The second idea is promising, but it feels too complicated.”
  • “Keep the concept and simplify the shape.”
  • “Now compare two typefaces before we finalize.”
Comparison of one long, complex AI prompt versus a step-by-step conversation, showing how users can explore ideas, give feedback, and refine AI responses.

Two approaches to working with AI: detailed instructions upfront or an evolving conversation. Both can be useful depending on the task.

Each message is a prompt. Together they form a working process. The same method applies to article planning, learning a new subject, debugging code, and researching unfamiliar options. The AI can offer alternatives, ask questions, and explain trade-offs while the user makes the decisions.

In our TechEduCareer design work with AI, the final direction often emerged only after reviewing actual results. No amount of advance description could fully replace seeing a shape on screen. The practical lesson is simple: when visual feedback or testing is available, use it instead of endlessly polishing instructions.

Ask the AI to challenge you, not merely agree

A productive conversation also needs disagreement. AI assistants can sometimes become overly agreeable—a behavior often described as sycophancy. If you ask “Is my design perfect?” you may get less useful feedback than if you say “Critique this design. Identify weaknesses and tell me if a new choice conflicts with decisions we made earlier.”

The goal is not to make the AI argumentative. It is to encourage evidence-based feedback, distinguish facts from preferences, and preserve the user’s control over final decisions. A helpful collaborator should be able to say, “We tried that approach before; here is what happened and what has changed.”

Why Shared Context Changes Everything

Think about speaking with someone you know well versus a neighbor you have just met. With a close family member, a few words may be enough because you share experiences, preferences, and history. With a new acquaintance, you naturally explain more. The difference is not intelligence; it is shared context.

Comparison of a new AI conversation requiring background information and an established conversation where AI uses shared context, previous discussions, and user preferences to provide more relevant responses.

The more relevant context an AI has, the less you need to explain from scratch. However, important details may still need to be repeated.

AI conversations have a useful—but limited—parallel. In a continuing chat, an assistant may have access to earlier decisions, examples, and preferences. In a fresh chat, it may know none of them. Some products offer memory or project instructions, but availability and behavior differ. AI does not understand relationships as a human does, and remembered context can be incomplete or wrong.

For important projects, periodically summarize decisions: “We chose a minimal design, rejected complex icons, and agreed not to publish without review.” This makes it easier to resume work, spot contradictions, or move to another system. Shared context reduces repetition, but it does not remove the need to verify assumptions.

Will the Same Prompt Work in ChatGPT, Claude, Gemini, and Qwen?

Usually, yes—at the level of ordinary language. “Let’s work step by step and challenge my assumptions” is understandable across capable conversational AI models. But the results will not be identical. Models differ in training, reasoning performance, instruction following, available context, and communication style. The application surrounding the model matters too. Our WordPress and MCP case study shows what changes when AI can interact with connected tools.

For example, one assistant might have access to a connected WordPress site, while another can only advise based on text you paste into the chat. One may be able to search the web or edit a Figma document; another may not have those tools enabled. A prompt cannot create a missing integration or grant permission to change a website.

If you move to another AI, transfer a concise project brief rather than assuming it knows your history. Include your goal, current state, key constraints, previous decisions, and what you want to do next. Then evaluate the new assistant’s output on its merits.

Are There Secret AI Commands?

No universal one-word command unlocks hidden intelligence or bypasses an AI system’s normal capabilities. Words such as “Continue,” “Summarize,” “Simplify,” “Compare,” and “Critique” often work because the current conversation supplies the missing object. “Continue” after a half-written outline is clear; “Continue” in an empty chat is not.

Specific applications may support genuine slash commands, keyboard shortcuts, custom instructions, or developer-defined actions. Those are product features, not secret words understood by every model. Similarly, typing “SYSTEM OVERRIDE” or “IGNORE ALL PREVIOUS INSTRUCTIONS” does not grant a normal user higher authority over the system.

The decisive question is whether the AI has enough relevant information to understand the intended task. A short instruction can be clear in an established conversation and meaningless in a new one.

Real Example: WordPress Troubleshooting Without a Magic Prompt

While working on TechEduCareer, we encountered a JavaScript error reported inside a generated LiteSpeed Cache file. Our related AI-assisted WordPress development case study explores the broader question of when to use plugins and custom code. The visible filename alone did not reveal which original script caused the problem. A vague request such as “Fix my website” would have encouraged guesswork.

Instead, the investigation became a sequence of questions: What error does the browser show? Is the file generated by caching or supplied directly by a plugin? Which original script is involved? Can we inspect the evidence before changing settings? The investigation traced the problematic script to a plugin rather than treating the optimized filename as the true source.

That workflow demonstrates three habits more valuable than a decorative prompt formula: supply observable evidence, test hypotheses, and verify the result in the real system. An AI explanation is not the same as a confirmed fix. Screenshots, logs, documentation, and actual application behavior remain essential.

Another Example: SEO Research Needs Evidence, Not Confidence

Imagine asking an AI to find publications that accept unpaid guest articles and allow editorial backlinks. A confident list of ten websites might look impressive, but the important questions are whether submissions are currently open, whether links are permitted, whether they appear in the article or author bio, and whether any fees apply.

For that task, a useful request specifies verification standards: check official contribution pages, distinguish confirmed policies from unknowns, and provide sources. A detailed prompt helps because the deliverable has objective criteria. Even then, websites change their policies, so current research and human review matter.

This is one reason formal prompting can be worthwhile for research: not to make the AI sound authoritative, but to make uncertainty and evidence visible.

When Formal Prompt Engineering Really Is Worth Learning

There are situations where conversational improvisation is not enough. If an organization needs an AI system to process invoices, classify support tickets, extract fields from documents, or generate consistent reports, it needs repeatable behavior. Prompts may be combined with schemas, examples, tools, evaluations, and software checks.

  • Automated workflows: instructions must work across many inputs without a person clarifying each one.
  • Structured outputs: downstream software may require exact fields, types, or formats.
  • High-stakes decisions: evidence, oversight, and independent validation matter more than fluent prose.
  • Large-scale content operations: consistency, brand rules, and quality checks reduce rework.
  • Tool-driven actions: permissions, approval boundaries, and error handling must be explicit.

In these contexts, prompt engineering is part of a broader engineering process. A prompt alone cannot replace testing, access controls, or monitoring. Good courses should teach how to evaluate results and identify failure modes, not just provide impressive templates.

Prompt Engineering vs. Context Engineering

A related term is context engineering: deciding which information, examples, documents, instructions, and tool results an AI should receive for a task. The distinction is useful even for beginners. “Act as an expert” focuses on wording; providing the real error log, plugin list, and past attempts improves the information available for reasoning.

You do not need to memorize the terminology. The practical question is: “What does the AI need to know that it does not already know?” Relevant context usually helps more than elaborate phrasing.

Five Habits That Make AI Collaboration Better

  • Start naturally. Ask your question in your own words; you do not need a template for everyday tasks.
  • Add context when it matters. Mention your goal, environment, constraints, and any previous attempts.
  • Invite clarification and constructive criticism. Ask the AI to question uncertain assumptions rather than guess or agree automatically.
  • Work iteratively. Review outputs, test suggestions, and revise decisions as new information appears.
  • Verify important claims and protect sensitive information. Check reliable sources and actual results; avoid sharing passwords, API keys, or unnecessary personal data.

A reusable instruction for an exploratory project might be: “I don’t know the final result yet. Help me work step by step, explain trade-offs, challenge weak assumptions, and ask when an important detail is missing. Don’t make major changes without my approval.” That is enough to establish a productive process without pretending to be a technical expert.

Frequently Asked Questions

Do I need a prompt engineering course to use ChatGPT?

No. Most people can begin with ordinary questions and follow-up messages. A course may help if you want to build automated workflows, evaluate model behavior systematically, or handle complex repeatable tasks.

Are longer prompts more accurate?

Not automatically. Relevant context and clear constraints can help, but length alone does not guarantee accuracy. Important claims still require verification.

Can AI ask me questions instead of making assumptions?

Yes. You can ask an assistant to clarify missing requirements before proceeding. For simple tasks, it may be more efficient to answer directly and state any assumptions.

Does saying “act as an expert” unlock special capabilities?

No. It can influence perspective or style, but it does not add tools, credentials, or guaranteed expertise.

Can I use the same prompts with different AI models?

Often yes. General instructions transfer well, but results, memory, available tools, and application features differ.

Conclusion: Better Conversations, Not Magic Words

Prompt engineering has genuine value, especially when AI must perform defined tasks consistently and at scale. But everyday users do not need to master a secret language before they can benefit from AI. They can ask, explore, disagree, correct, and learn through conversation.

The most useful skills are familiar human ones: explaining your goal, sharing relevant context, recognizing uncertainty, asking follow-up questions, and checking whether the answer works. AI should help carry some of that communication burden, not place all of it on the person asking for help.

So start with the question you actually have. If the answer is incomplete, keep talking. Sometimes one word is enough; sometimes a hundred words aren’t.

Person using AI to improve a WordPress website, with a laptop displaying plugin management, troubleshooting, SEO optimization, backups, and performance improvements.

How I Used AI to Improve My WordPress Website: A Beginner’s Practical Guide

Can a beginner use AI to improve a WordPress website? Yes—but the useful part is not asking AI to “optimize everything.” The better approach is to use AI as a technical partner: give it access only to the information and actions it needs, make a backup, inspect the site, diagnose one problem at a time, make reversible changes, and verify the result.

I learned this while improving TechEduCareer. I was not approaching the project as a WordPress expert. I wanted to understand what was wrong, what actually mattered, and what could safely be fixed. AI helped with the investigation, but I remained the person approving important decisions. For a separate real-world example, see how we built a lightweight WordPress plugin for social publishing.

What AI can actually do for a WordPress website

An AI assistant can be useful far beyond writing blog posts. Depending on the tools and permissions available, it can help inspect WordPress settings, review plugins, analyze page HTML, find broken or outdated links, examine SEO configuration, interpret browser-console errors, check sitemaps and robots directives, suggest internal links, draft content, and explain unfamiliar technical information in plain language.

The important distinction is between advice and action. An AI can tell you what it thinks should change. A connected AI tool may also be able to make that change. Those are not the same risk level.

Step 1: Make a backup before letting anything change

This became one of my most important rules. Before a meaningful round of website changes, create a restorable backup. WordPress itself recommends regular backups so you can restore your site if an update causes trouble.

A backup changes the whole working style. Instead of being afraid to touch anything, you can make careful, reversible changes and test them. It does not justify reckless changes, but it gives you a recovery point.

How I backed up my WordPress website using Duplicator

For my own website, TechEduCareer, I used the Duplicator WordPress plugin to create a backup before making significant changes.

The process is straightforward:

  1. Install and activate Duplicator from the WordPress plugin directory.
  2. Open Duplicator → Backups and create a new backup.
  3. Select a full-site backup that includes both the WordPress files and database.
  4. Run the backup and wait for it to finish.
  5. Download the backup archive and any accompanying recovery or installer file provided by your Duplicator version.
  6. Store the downloaded files somewhere safe, preferably outside your hosting account.

I particularly recommend keeping an offline copy. If your hosting account becomes inaccessible, a backup stored only on that same server may not help.

One important lesson: a successful backup doesn’t automatically guarantee a successful restoration. Ideally, test the recovery process on a staging website before relying on it for major changes.

With a backup available, I could experiment more confidently, knowing I had a recovery option if something went wrong.

Step 2: Give AI context, not your passwords

At first, a beginner may think the easiest approach is to paste administrator credentials into an AI chat. Do not do that. Passwords, API keys and other secrets should stay private.

A safer model is to use an authorized connector or management tool that exposes specific WordPress capabilities. In my case, the AI could inspect and perform supported WordPress operations through an authorized connection while I retained control over sensitive or destructive actions. Some steps still required me to use the WordPress interface manually.

This division of responsibility turned out to be useful: AI could do the repetitive inspection and analysis, while I handled credentials, approvals and decisions that could have larger consequences.

Step 3: Let AI inventory the site before fixing it

Before changing a WordPress site, ask: What theme is active? Which plugins are installed? Which are active? What WordPress and PHP versions are running? Which SEO and caching plugins are involved? What content types exist?

Taking inventory helps prevent a common beginner mistake: installing another plugin every time there is a problem. Sometimes the better solution is to configure an existing plugin correctly—or remove a plugin that is no longer needed.

Step 4: Review plugins by purpose, not by quantity alone

We reviewed plugins individually: what does this plugin do, is that function still needed, does another plugin already provide it, and does it add front-end code or maintenance overhead?

I removed several plugins that no longer had a useful role. Others stayed because they supported functions I still needed. The goal was not to reach an arbitrary “perfect” plugin count. It was to understand why each component existed.

A real example: tracing a JavaScript error to the actual plugin

This was one of the most useful lessons from the project. The browser console reported a JavaScript syntax error in a file generated by LiteSpeed Cache. It would have been easy to conclude that LiteSpeed was broken and disable optimization.

Instead, we traced the generated file back to the WordPress script that supplied the code. We traced the source to a front-end vendor bundle from UserFeedback, a plugin I had previously installed while looking for a simple Facebook-style “Like” feature.

UserFeedback was not actually needed for that purpose. I removed it, cleared the relevant caches and tested again in a clean browser session. The syntax error disappeared.

The lesson was bigger than one plugin: a filename tells you where an error appeared, not necessarily where the error originated. AI was useful because it could follow the evidence across the browser console, generated cache file, WordPress script handle and plugin inventory instead of guessing.

Step 5: Use AI to understand SEO settings instead of chasing scores

We then worked through the technical SEO foundation: page titles and meta descriptions, canonical URLs, XML sitemaps, robots directives, indexation settings, schema, author information, internal links and redirects.

This also taught me that an SEO audit warning is not automatically a problem. For example, if you deliberately mark a page noindex, you don’t need to optimize it as though it were an important search landing page. Keeping thin tag and archive pages out of search may be more useful than adding artificial descriptions just to quiet an audit report.

If you are starting from zero, our guide to improving Google and Bing visibility without paying for ads explains the broader search-discovery side of the process.

Step 6: Check what search engines can actually discover

We verified the public sitemap and robots file rather than assuming the settings screen was enough. We also connected the site to Google Search Console and Bing Webmaster Tools and submitted the canonical sitemap.

Here’s a useful habit for AI-assisted work: verify the output, not just the setting. If a plugin says a sitemap option is enabled, inspect the public sitemap. If a redirect was created, request the old URL and confirm the HTTP response. If a page should be noindexed, inspect its rendered robots meta tag.

Step 7: Improve content for people, search and AI answers

We reviewed the existing articles and improved titles, search intent, direct answers, headings, internal links and metadata. The aim was not to stuff keywords into every paragraph. It was to make each article easier for a person—and for a search or AI system—to understand.

For answer-oriented content, I found a simple structure useful: answer the main question early, use descriptive headings, explain important distinctions clearly, link related topics, and support factual claims with reliable sources. The same principles make content easier to quote, summarize and navigate.

Step 8: Use AI to find causes, not just symptoms

Another audit reported internal links using HTTP instead of HTTPS. Searching the article bodies did not find the links. We kept investigating and discovered that approved WordPress comments contained an old http://techeducareer.com author URL. WordPress rendered those comment-author links on the affected pages, where the crawler found them.

After removing the unnecessary comments and crawling the site again, the errors disappeared. This is exactly the kind of task where an AI assistant can save time: correlate the crawler report with rendered HTML, WordPress content and configuration instead of repeatedly editing the article itself.

Step 9: Measure before and after

We used an external site audit as one verification layer. During the final cleanup, the Ahrefs Site Audit Health Score moved from 99 to 100 and the reported technical errors went from two to zero. That does not mean a score of 100 guarantees rankings, traffic or AI citations. It means we resolved the specific technical issues that the crawl detected.

That distinction matters. AI can help you make a technically cleaner website, but it cannot promise first place on Google, traffic growth or inclusion in an AI-generated answer.

What I would not let AI do blindly

  • Delete plugins, files or database records just because they look unused.
  • Make broad search-and-replace operations without a backup and preview.
  • Change themes or production code without understanding the rollback path.
  • Share passwords, private API keys or authentication codes in chat.
  • Publish AI-written factual claims without checking reliable sources.
  • Chase every SEO audit warning simply to maximize a score.

A good rule is simple: the larger the possible impact, the more human review you want before execution.

A beginner-friendly AI + WordPress workflow

  1. Create and verify a backup.
  2. Explain your goal and current problem to the AI.
  3. Let it inspect the relevant settings and evidence where authorized.
  4. Ask it to explain the likely cause before proposing a fix.
  5. Prefer the smallest reversible change.
  6. Make sensitive or destructive changes manually or with explicit approval.
  7. Clear caches when relevant.
  8. Verify the public result independently.
  9. Record what changed so you can reverse it.
  10. Re-run the relevant audit or test.

Useful tools in an AI-assisted WordPress workflow

The exact stack will differ from site to site. In this project, different tools had different jobs: WordPress provided the publishing platform and Site Health information; an SEO plugin managed search metadata and schema; a caching plugin handled performance optimization; search-engine webmaster tools showed discovery and indexing information; a crawler provided an independent technical audit; the browser developer console exposed front-end errors; and the AI assistant connected the evidence and helped plan or perform supported changes.

WordPress also documents a troubleshooting approach in which plugins can be isolated to identify conflicts. The principle is worth remembering even if you use different tooling: test hypotheses rather than randomly changing settings.

What I learned as a beginner

The biggest surprise was that I did not need to become a WordPress developer before I could understand and improve my website. AI reduced the distance between seeing a technical problem and understanding what it meant.

But AI worked best when I treated it as a collaborator, not an autopilot. I asked questions, checked changes, sometimes did the manual step myself, and learned enough along the way to make better decisions the next time.

If you are building a new website, you may also find our website launch and promotion checklist useful. The technical cleanup described here is only one part of growing a site; useful content, authority, distribution and patience still matter.

Frequently asked questions

Can ChatGPT or another AI fix a WordPress website?

It can help diagnose problems, explain settings, write or review code and content, and—when connected through an authorized tool—perform supported WordPress actions. It should not be given unlimited control or sensitive credentials, and important changes still need human review and verification.

Do I need to know coding to use AI with WordPress?

No. Many useful tasks require no coding. However, understanding basic WordPress concepts, HTML, caching and browser developer tools gradually makes AI-assisted troubleshooting more effective.

Should AI automatically remove plugins it thinks are unnecessary?

No. First identify what each plugin does and whether the site depends on it. Deactivation is often a safer test than immediate deletion, and a backup should exist before meaningful changes.

Sources and further reading

Student exploring an educational fact library on a laptop, with interactive explanations, audio learning, quizzes, and a Death Valley science example.

Building a Fact Library Taught Me That Curiosity Needs a Next Step

I started Watt because I like learning things I did not know I wanted to learn. A question leads to an explanation, the explanation leads to another question, and suddenly an ordinary subject becomes interesting. The difficulty was that the material I wanted was scattered across websites, with different levels of detail and very different standards of evidence. Collecting facts in one place seemed useful. Building that place taught me that collecting them was only the beginning.

Watt is now a free library of more than 2,000 facts in Ukrainian and English. Readers can explore topics, choose an explanation level, read or listen, and try a short quiz. I built it as a solo founder, and its development has involved the content workflow as much as the interface. My experience is a product-building story, rather than evidence that this format improves learning. I have not yet measured educational efficacy.

Why a surprising fact needs an explanation

The first challenge was deciding what a useful fact page should actually do. A surprising sentence can attract attention, but it may also leave the reader with a misleading impression. Consider the rocks that leave trails across Racetrack Playa in Death Valley. Saying that the rocks move is intriguing. Explaining the observed combination of shallow water, thin ice panels and light wind gives the reader something more useful: a mechanism to understand. The sources behind that explanation matter because they distinguish a recorded observation from an appealing story.

That example also shows why brevity is a difficult editing problem. A short version should keep the mechanism intact. A longer version can explain how researchers observed the movement and why the conditions occur infrequently. Adding more words does not automatically make an explanation better, and removing words can accidentally remove the condition that makes a claim accurate. I came to think of explanation levels as different ways into the same subject, each of which needs to preserve the underlying meaning.

The challenge of keeping two languages accurate

Working in two languages makes that problem more visible. A translation can sound natural while changing the strength of a claim. Words such as “can,” “usually,” and “under these conditions” are small, but losing them changes what the reader is being told. A practical check is to compare the claim rather than just the wording: does each version describe the same mechanism, scope and uncertainty? Fluent language and factual agreement are separate requirements.

The same applies to a catchy title. A title about humans glowing needs an explanation that the light is too faint for unaided eyes and was measured with specialized equipment. It should not encourage the reader to confuse ultraweak photon emission with a thermal image. The useful editorial question is not just whether a sentence is technically defensible. It is what someone is likely to believe after reading it quickly.

Why audio narration changes the writing

Audio was another important part of the product. I wanted readers to be able to listen rather than making reading the only way to explore a subject. But narration makes weaknesses in writing easier to hear. A sentence with several qualifications may be understandable on screen and cumbersome aloud. References that work as links are not naturally spoken. Numbers and unfamiliar names can interrupt the flow. Treating audio as another version of the experience, rather than simply another file to generate, creates a reason to revisit the explanation itself.

Designing quizzes that reinforce understanding

Quizzes introduced a different kind of discipline. The question needs to be understandable on its own, and the options need one clearly intended answer. In the sailing-stones example, a useful question asks what actually pushes the rocks. It points back to the explanation’s mechanism. A vague question about whether the rocks are “mysterious” would mostly test the wording of the page. I want a quiz to give the reader another way to engage with an idea, while being careful not to interpret a correct click as proof of durable learning.

What early testers taught me about returning

Early testers pushed me to think beyond individual fact pages. Their feedback was that there needed to be something that made people want to return and continue. That influenced my work on the wider experience: topic choice, progression, saved interests and gamification. These features give curiosity somewhere to go after the first interesting page. For a broader look at how playful activities can support education, see TechEduCareer’s guide to game-based learning. The question became how to make the next step clear without turning every moment into a demand for another click.

Build one complete learning journey first

For someone building a similar product, I would start by making one complete journey work. Can a new visitor choose something interesting, understand it, hear it if they prefer, inspect the source, and answer a useful question? That journey exposes dependencies that a feature list hides. A quiz depends on an explanation. Narration depends on a usable script. A convincing illustration depends on an accurate caption and a clear account of its origin.

AI-assisted workflows still need human judgment

Connecting those pieces into an agent-assisted workflow has been one of the hardest parts. AI can help produce and revise material, but it does not remove the need to check claims, preserve source relationships or distinguish synthetic illustrations from documentary photographs. Nor does an automated sequence become reliable merely because it runs repeatedly. The meaningful unit of work is the complete page and the reader’s experience of it, rather than a count of generated assets.

What I still need to learn

The library’s growth gives me more opportunities to find inconsistencies, not a reason to assume the work is finished. I still need better evidence about which experiences people value, why they return, and what they remember. A growing content count, a successful publication or an encouraging comment can be useful signals, but they answer different questions. My main lesson is to keep those questions separate while building a path that is easy to try.

I began with a personal interest in unusual facts. The project has made me equally interested in what happens immediately after the surprise. A useful explanation, a voice to listen to, a source to inspect and a question to consider can give that moment somewhere to lead. Whether it becomes a lasting learning habit is something I still need to learn from the people using it.

Disclosure: The author is Watt’s founder. This article was prepared with AI writing assistance. Watt’s educational efficacy has not yet been measured.

Scientific references

  • Norris et al., “Sliding Rocks on Racetrack Playa, Death Valley National Park: First Observation of Rocks in Motion,” PLOS ONE (2014). Read the study.
  • Kobayashi et al., “Imaging of Ultraweak Spontaneous Photon Emission from Human Body Displaying Diurnal Rhythm,” PLOS ONE (2009). Read the study.